Engineering notes
23 notesBuilding, AI, architecture, and production.
Real projects, experiments, technical problems, and lessons from production — written so you can see how I think.
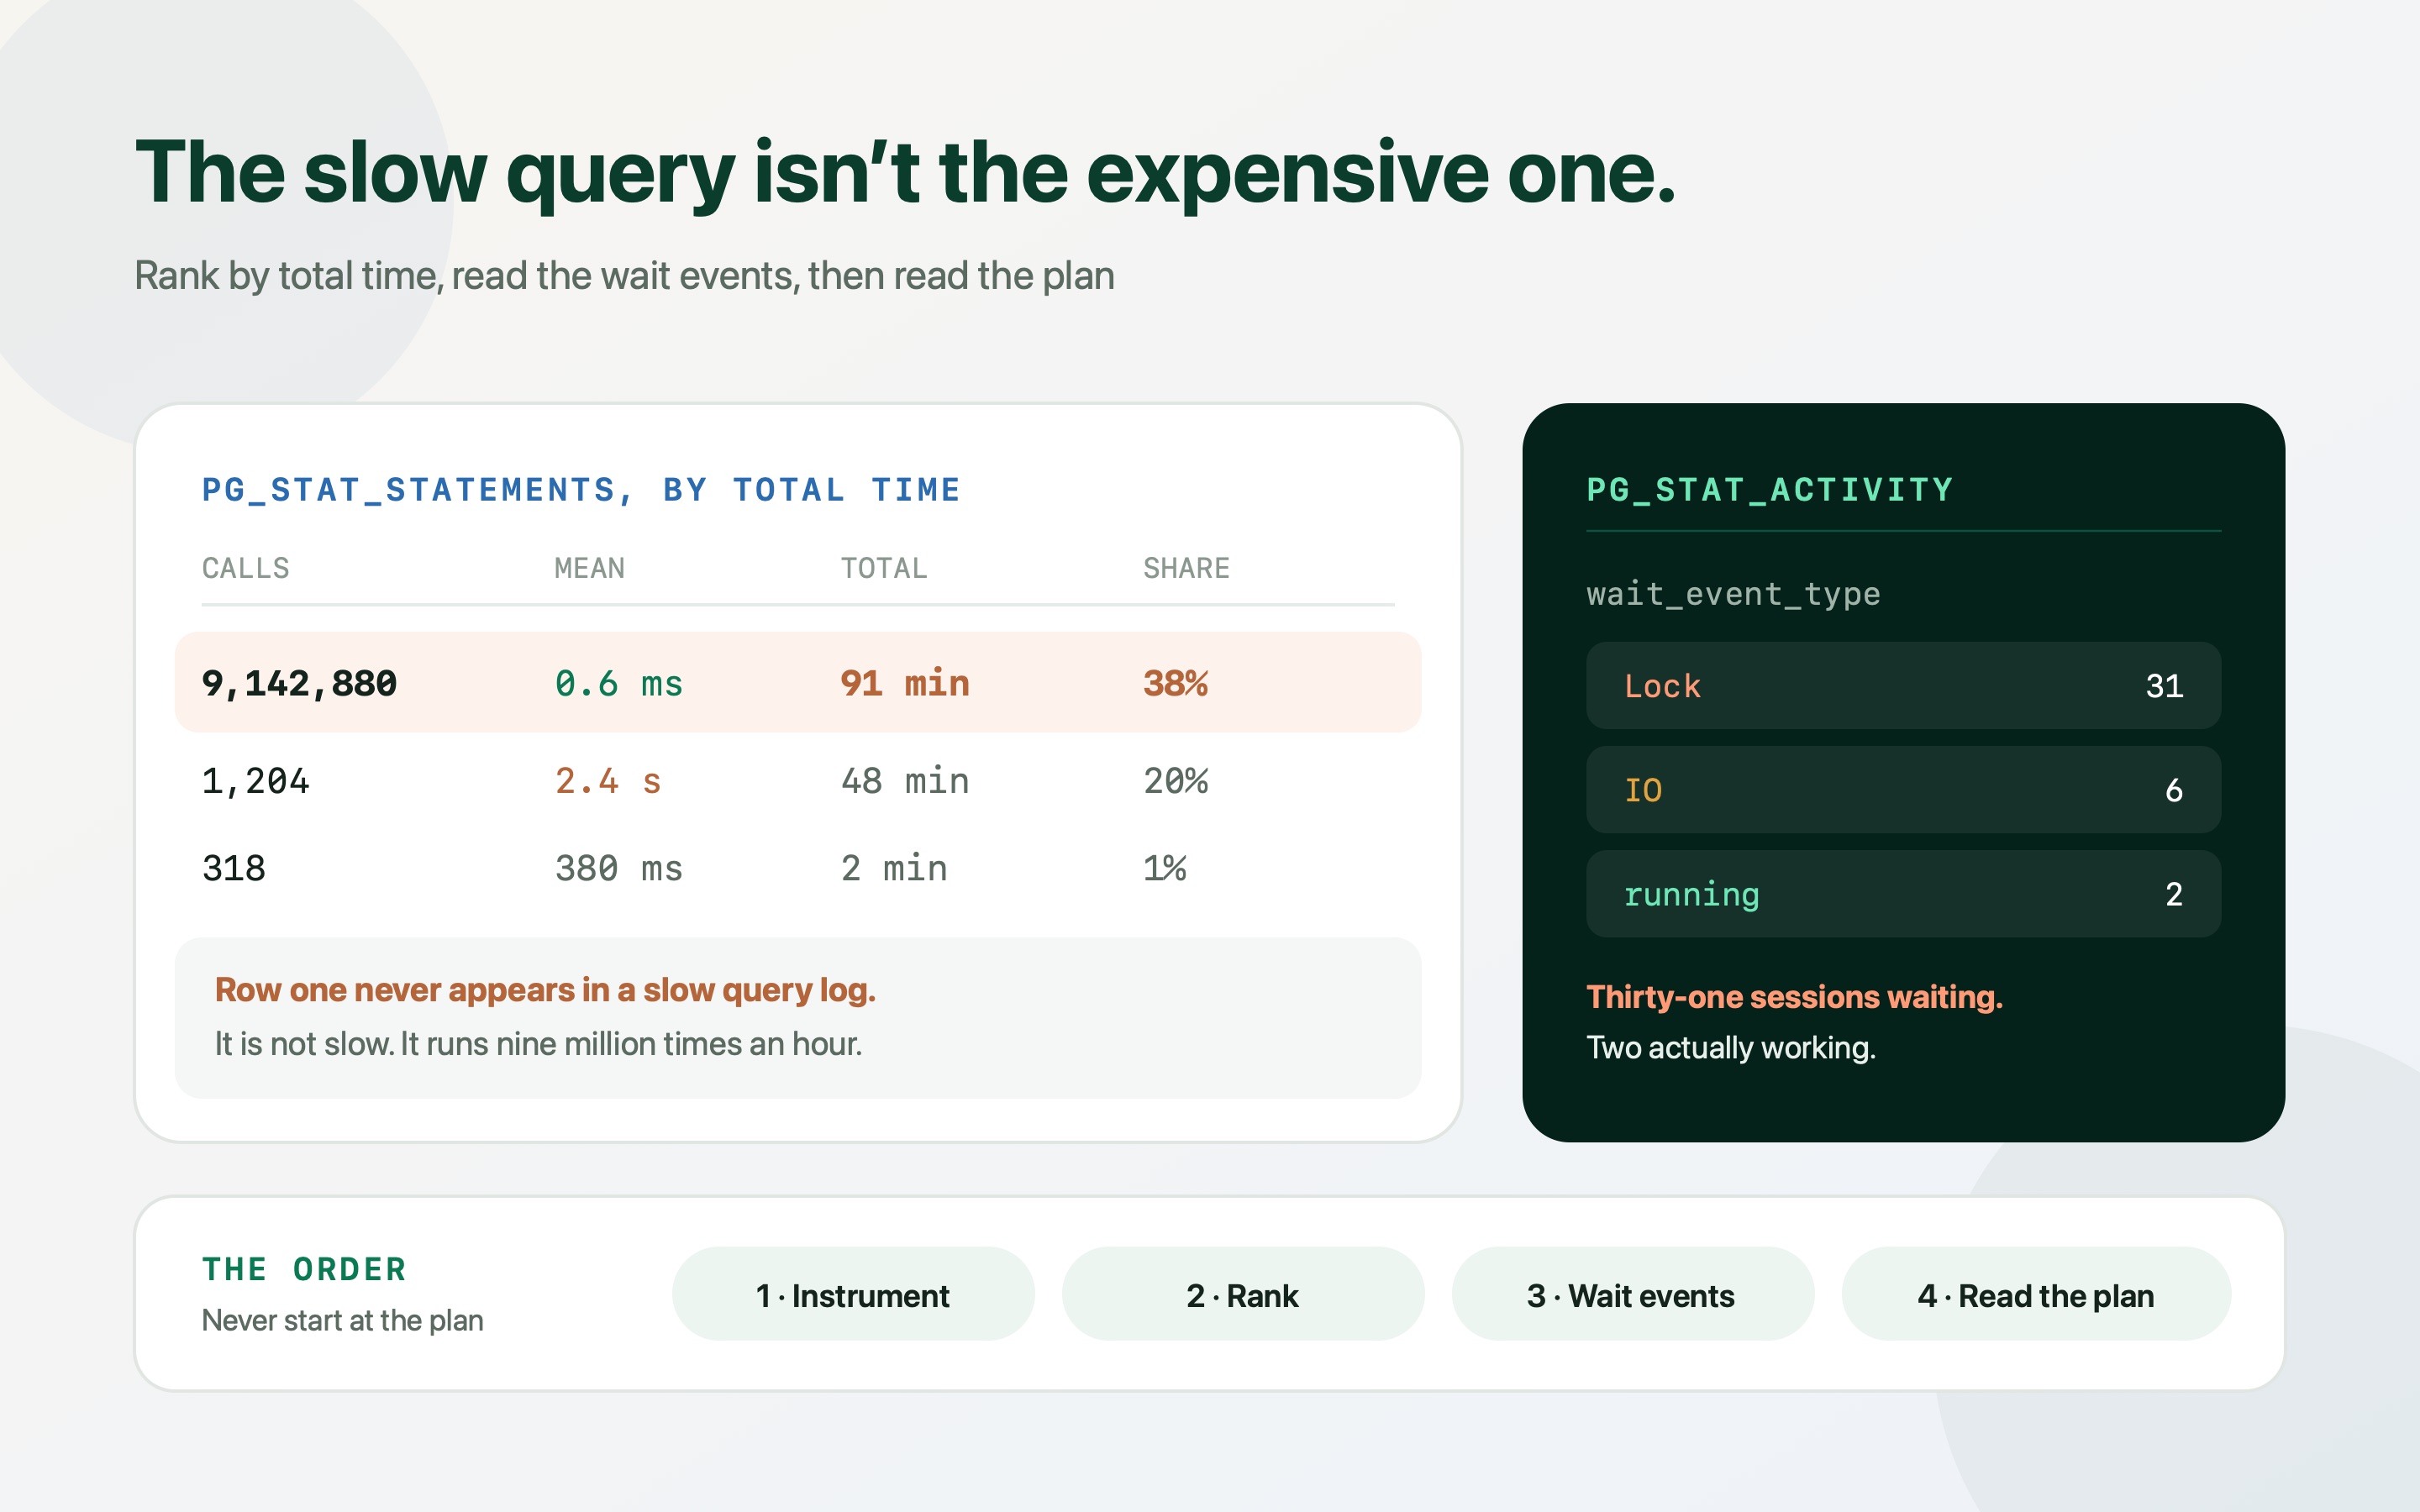
How to Diagnose Slow Postgres Queries in Production
Most teams debug slow Postgres by staring at a query someone complained about. Here's the diagnostic order that finds the real one: what to turn on, what to measure, how to read wait events, and the five shapes slow queries actually come in.
Read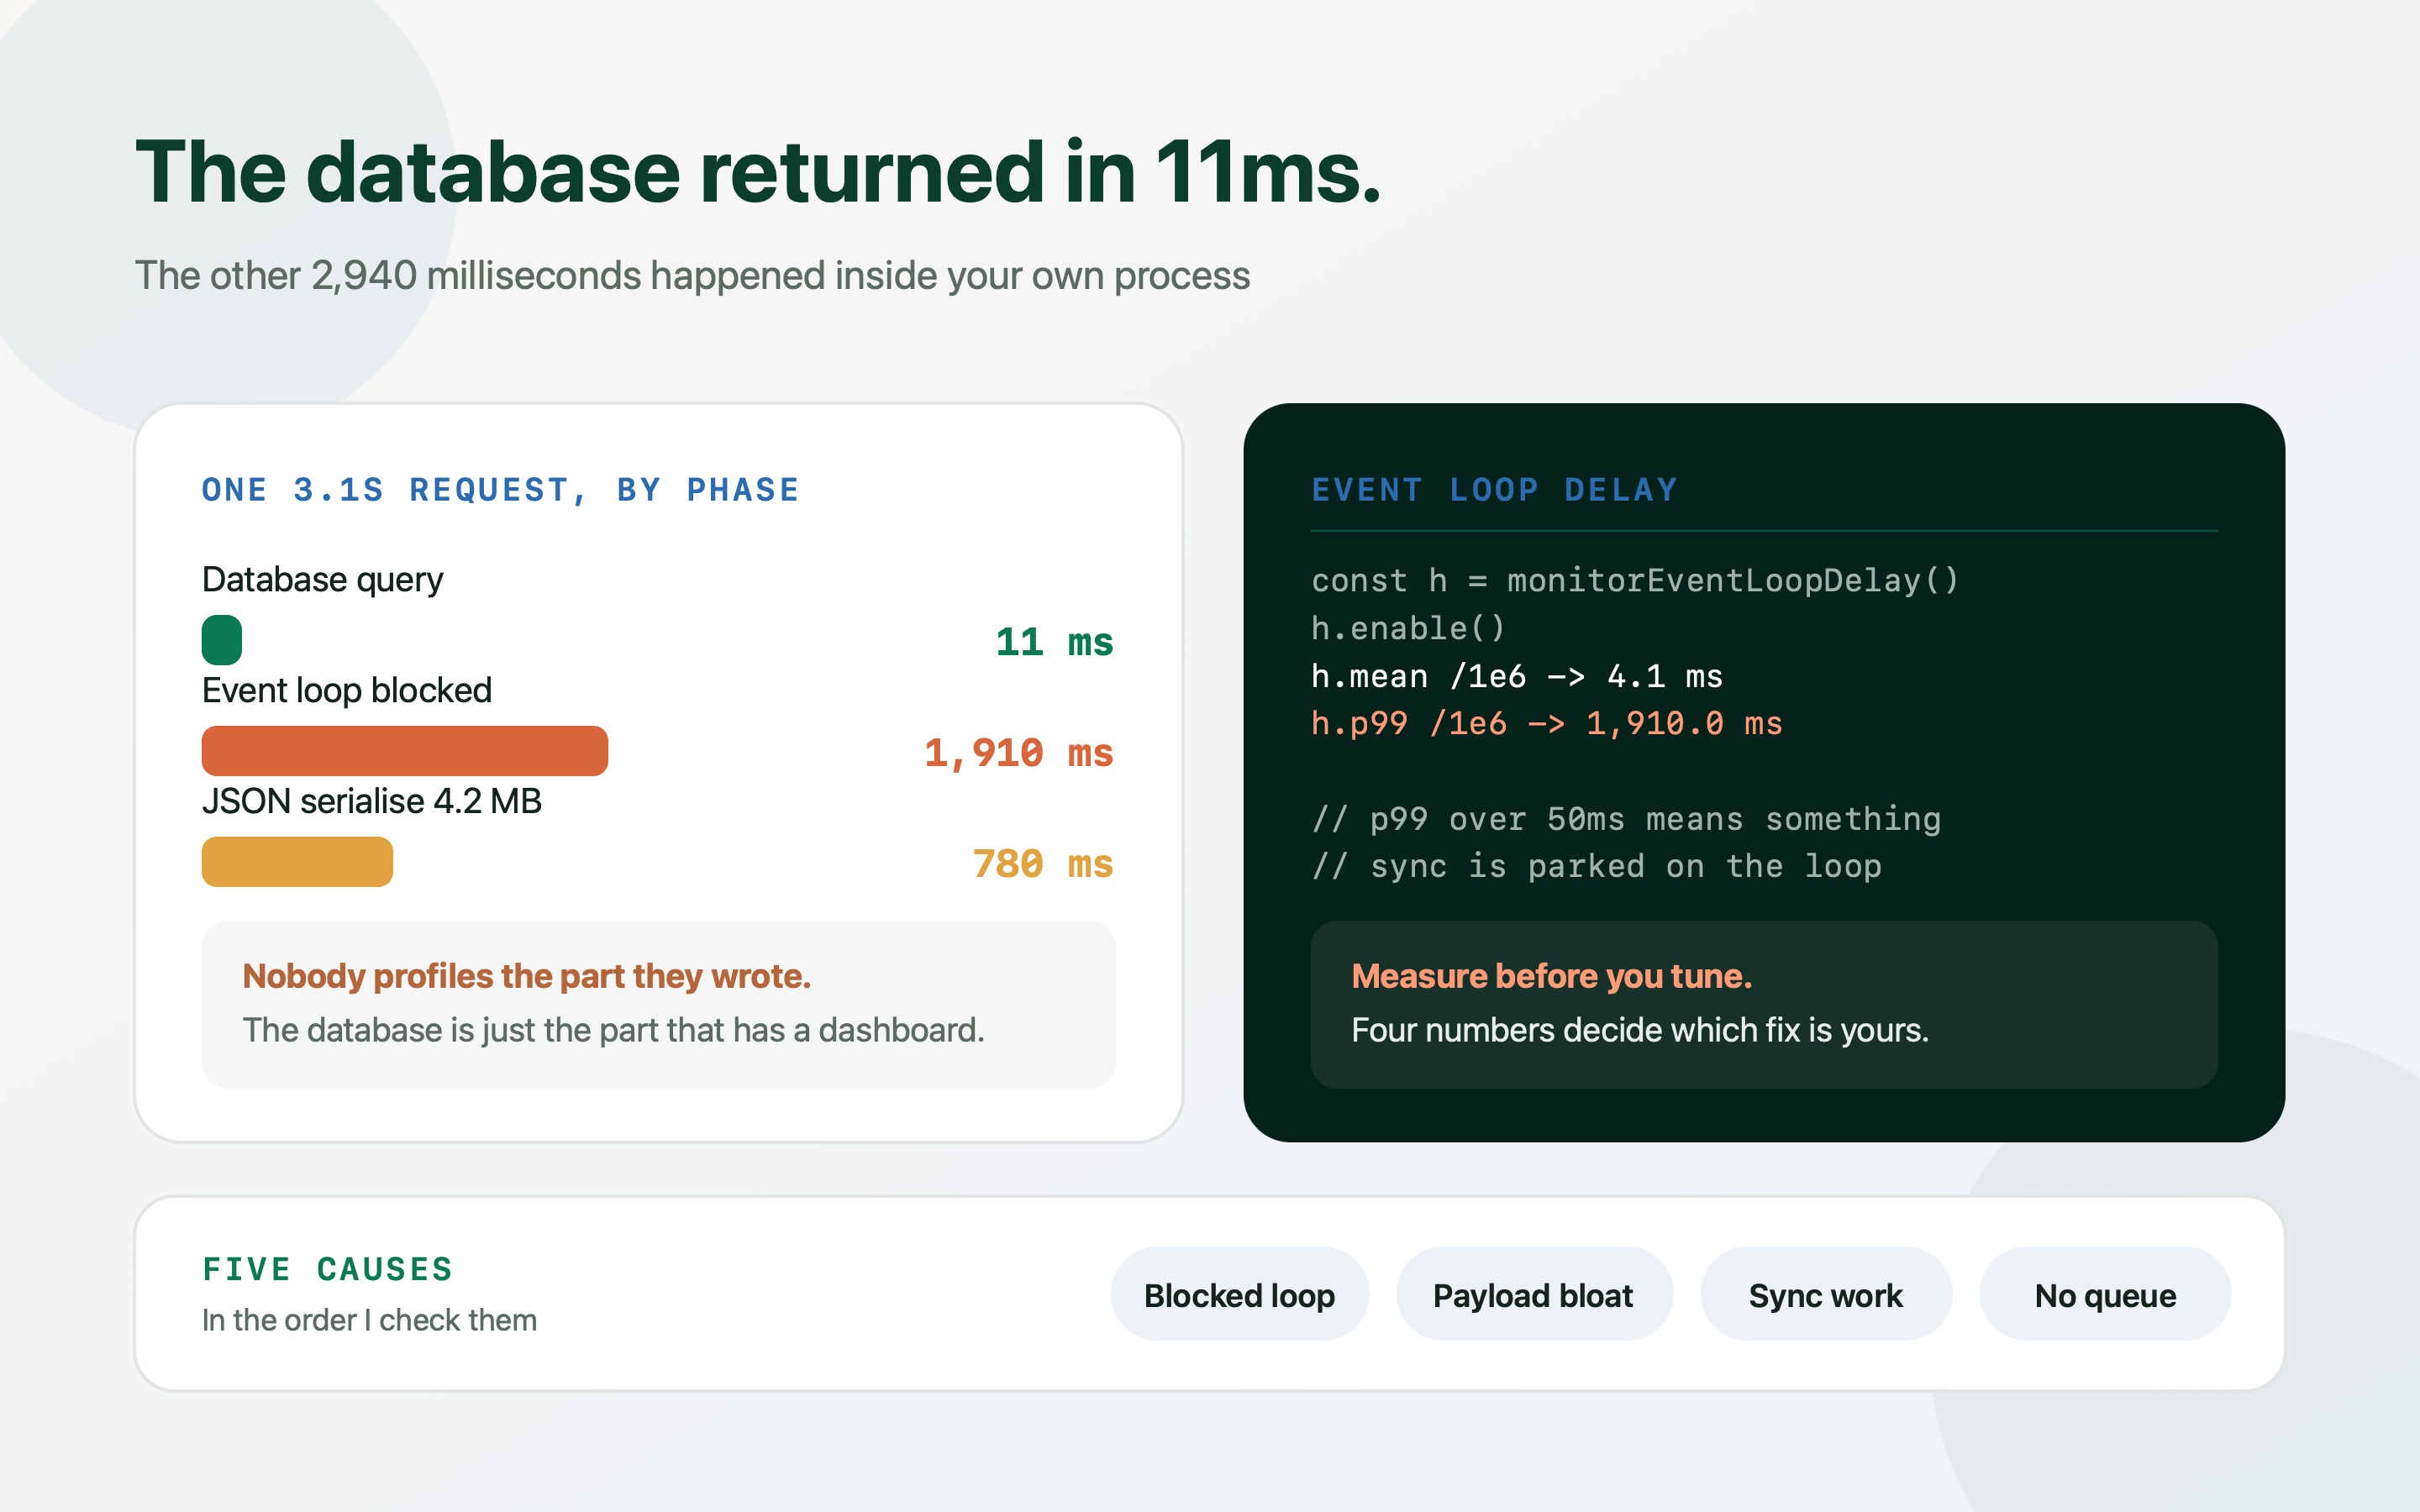
Why Your Node or Python API Takes 3 Seconds — And It Isn't the Database
Your dashboard takes three seconds and the slow query log is empty. Here's how to find the time: a blocked event loop, a four-megabyte payload, third-party calls inside the request, and two more nobody profiles.
Read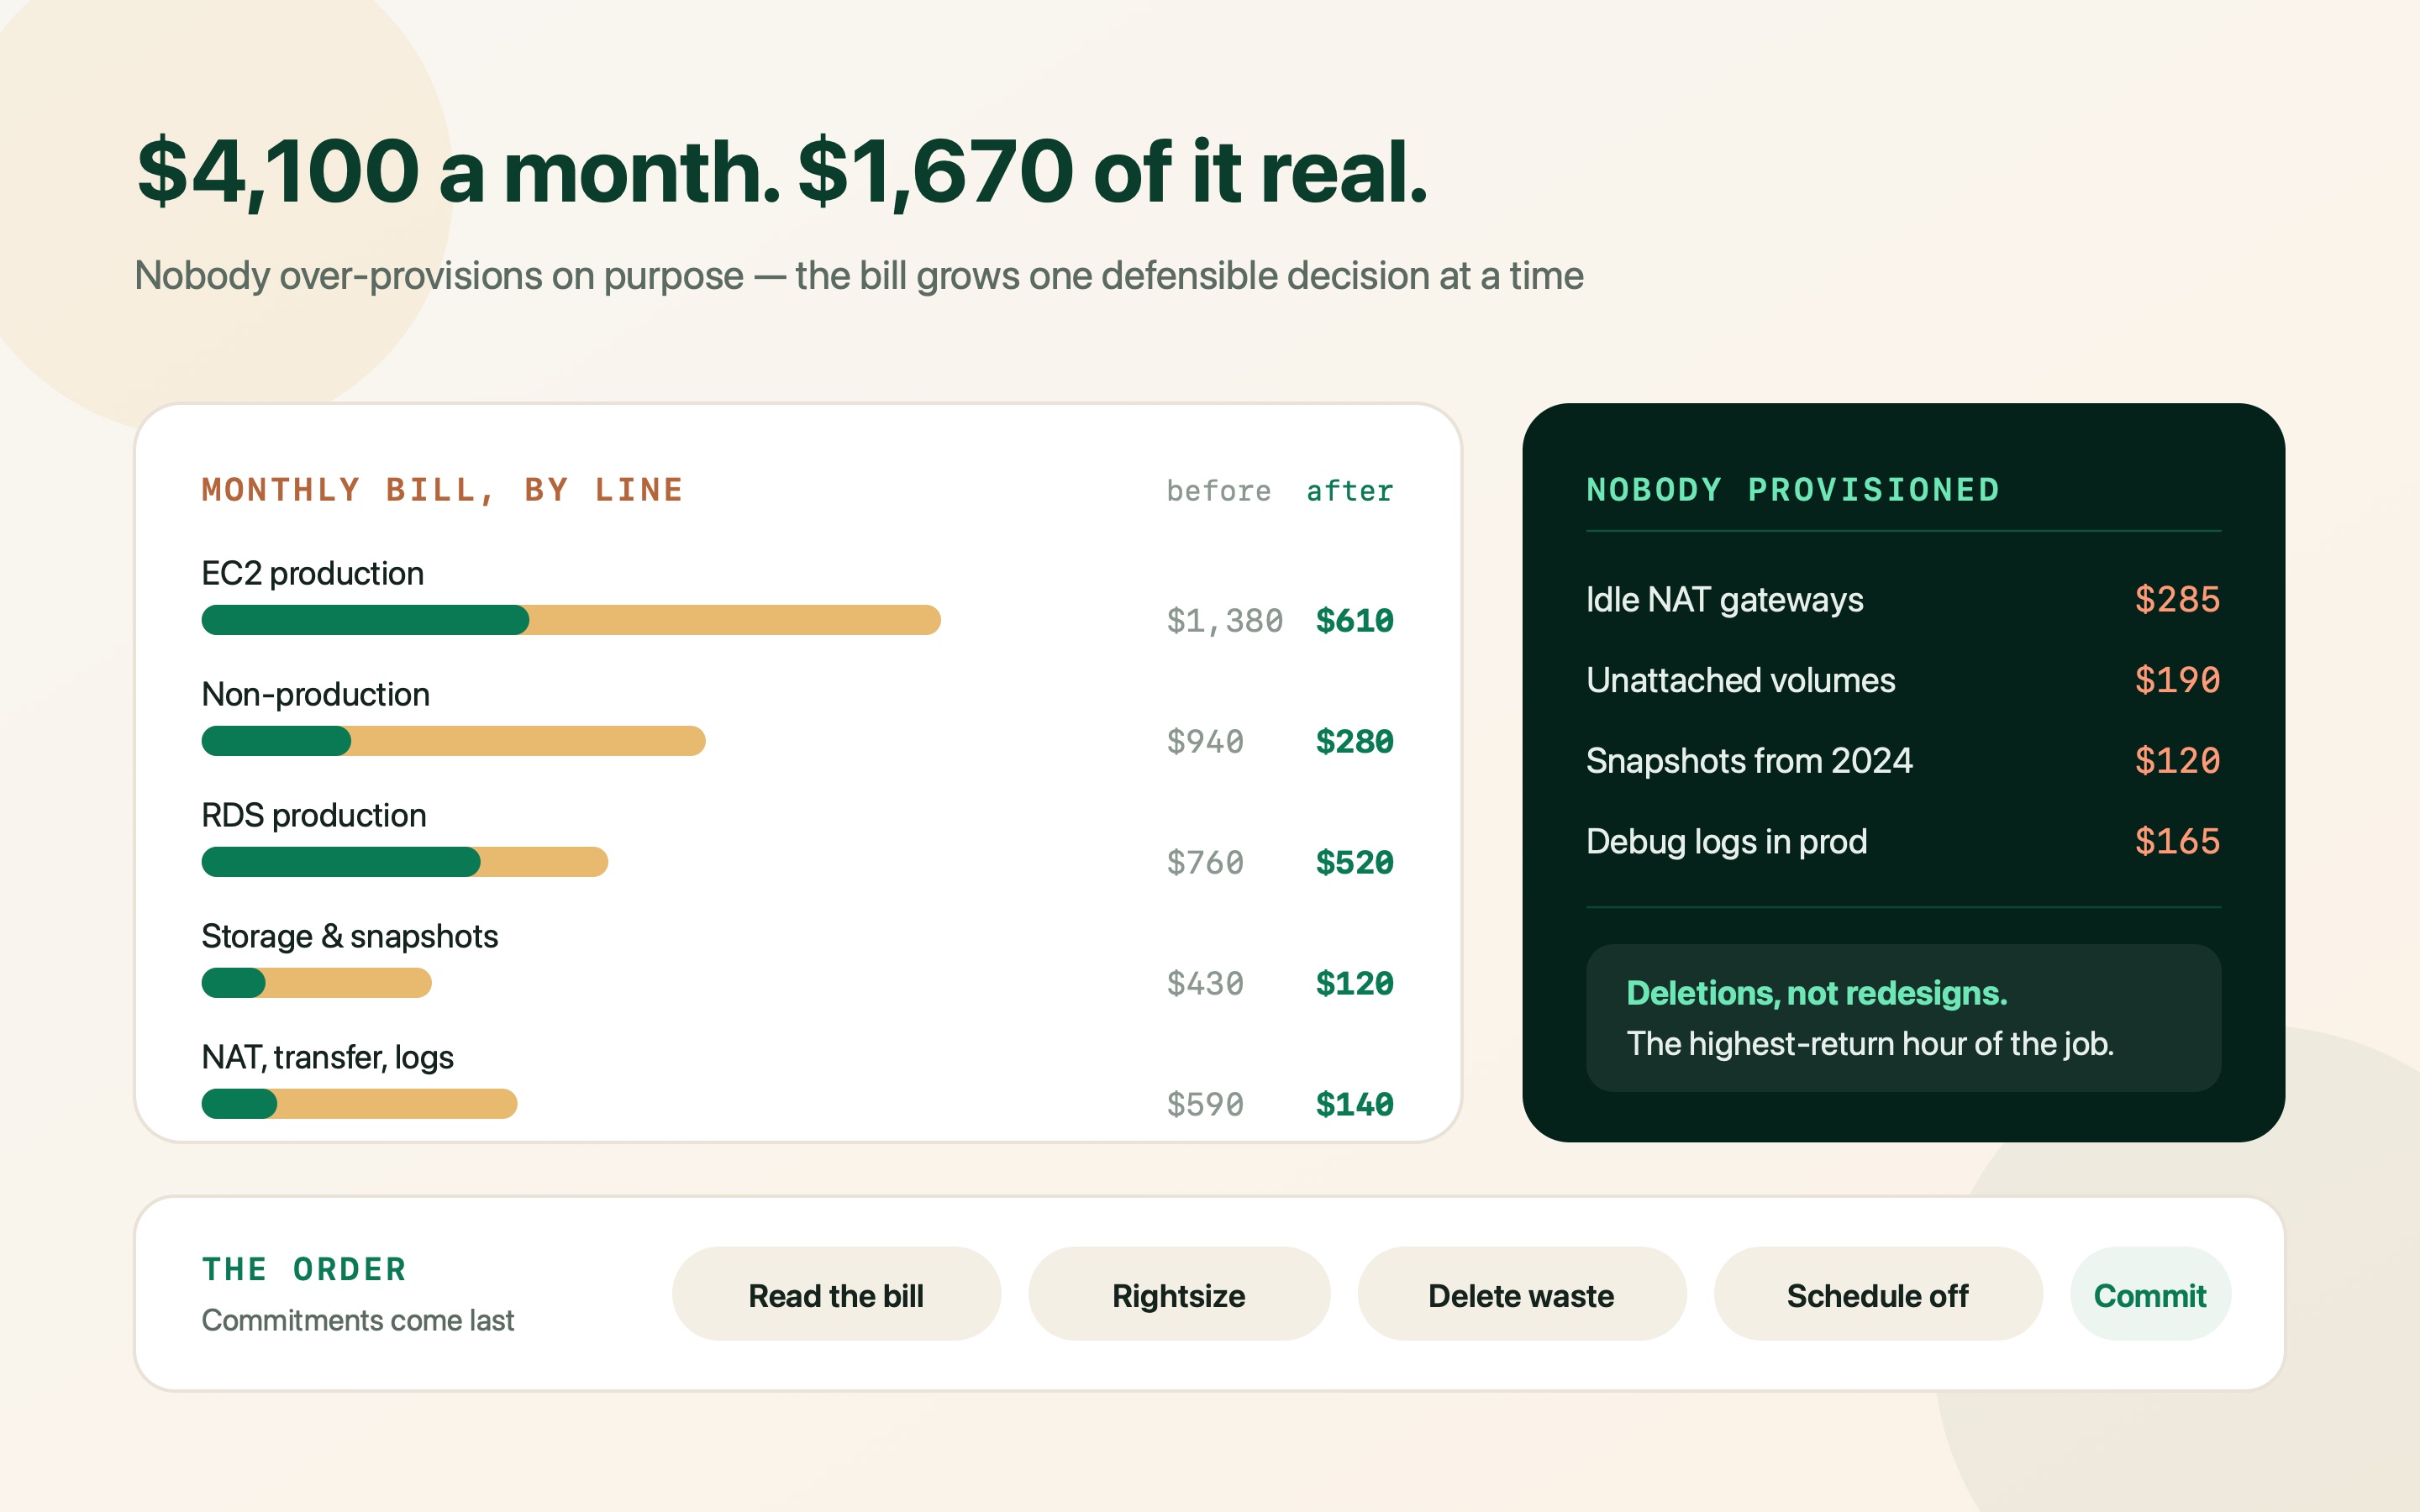
Reducing AWS EC2 and RDS Costs for Early-Stage SaaS
A $4,000/month AWS bill at seed stage is usually $1,400 of real workload and $2,600 of idle capacity, forgotten volumes, and NAT gateway charges. Here's the order I work through, with the commands to find each one.
Read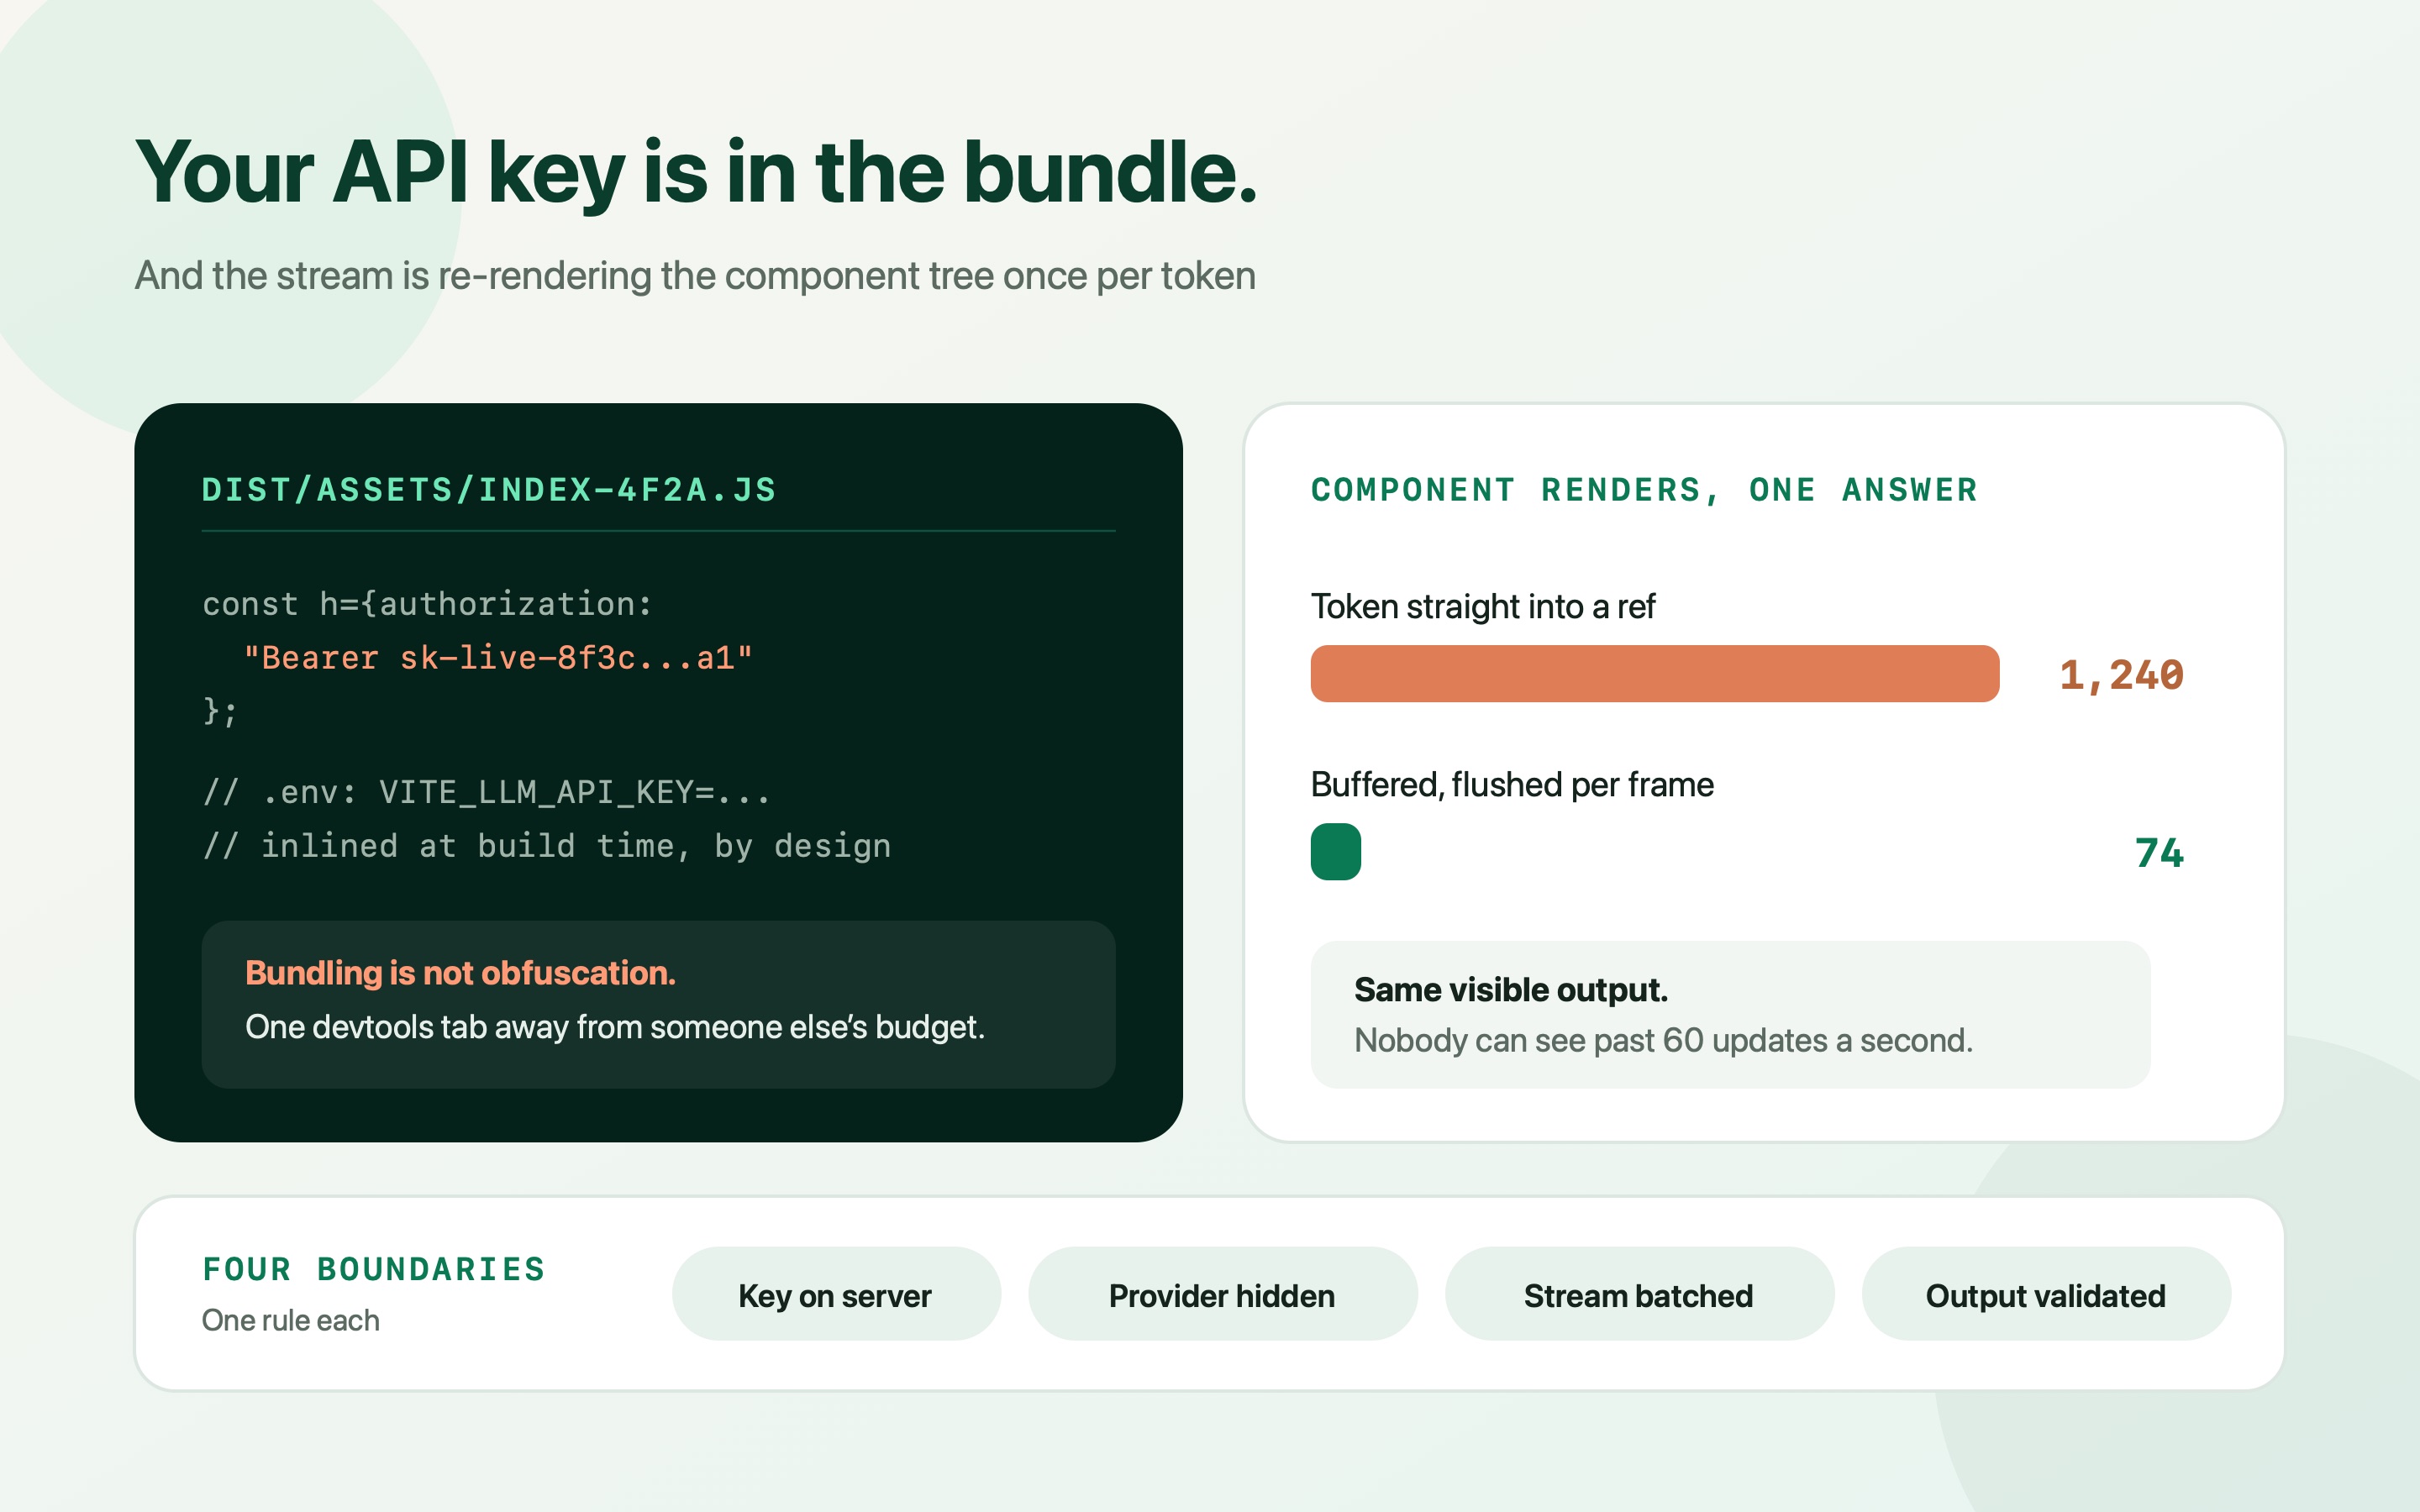
Integrating LLM APIs into Vue.js Applications Cleanly
Most Vue + LLM integrations fail the same four ways: the API key ships in the bundle, provider SDK calls sit inside components, streaming re-renders the tree a hundred times a second, and unvalidated model output lands straight in state. Here's the clean version, with code.
Read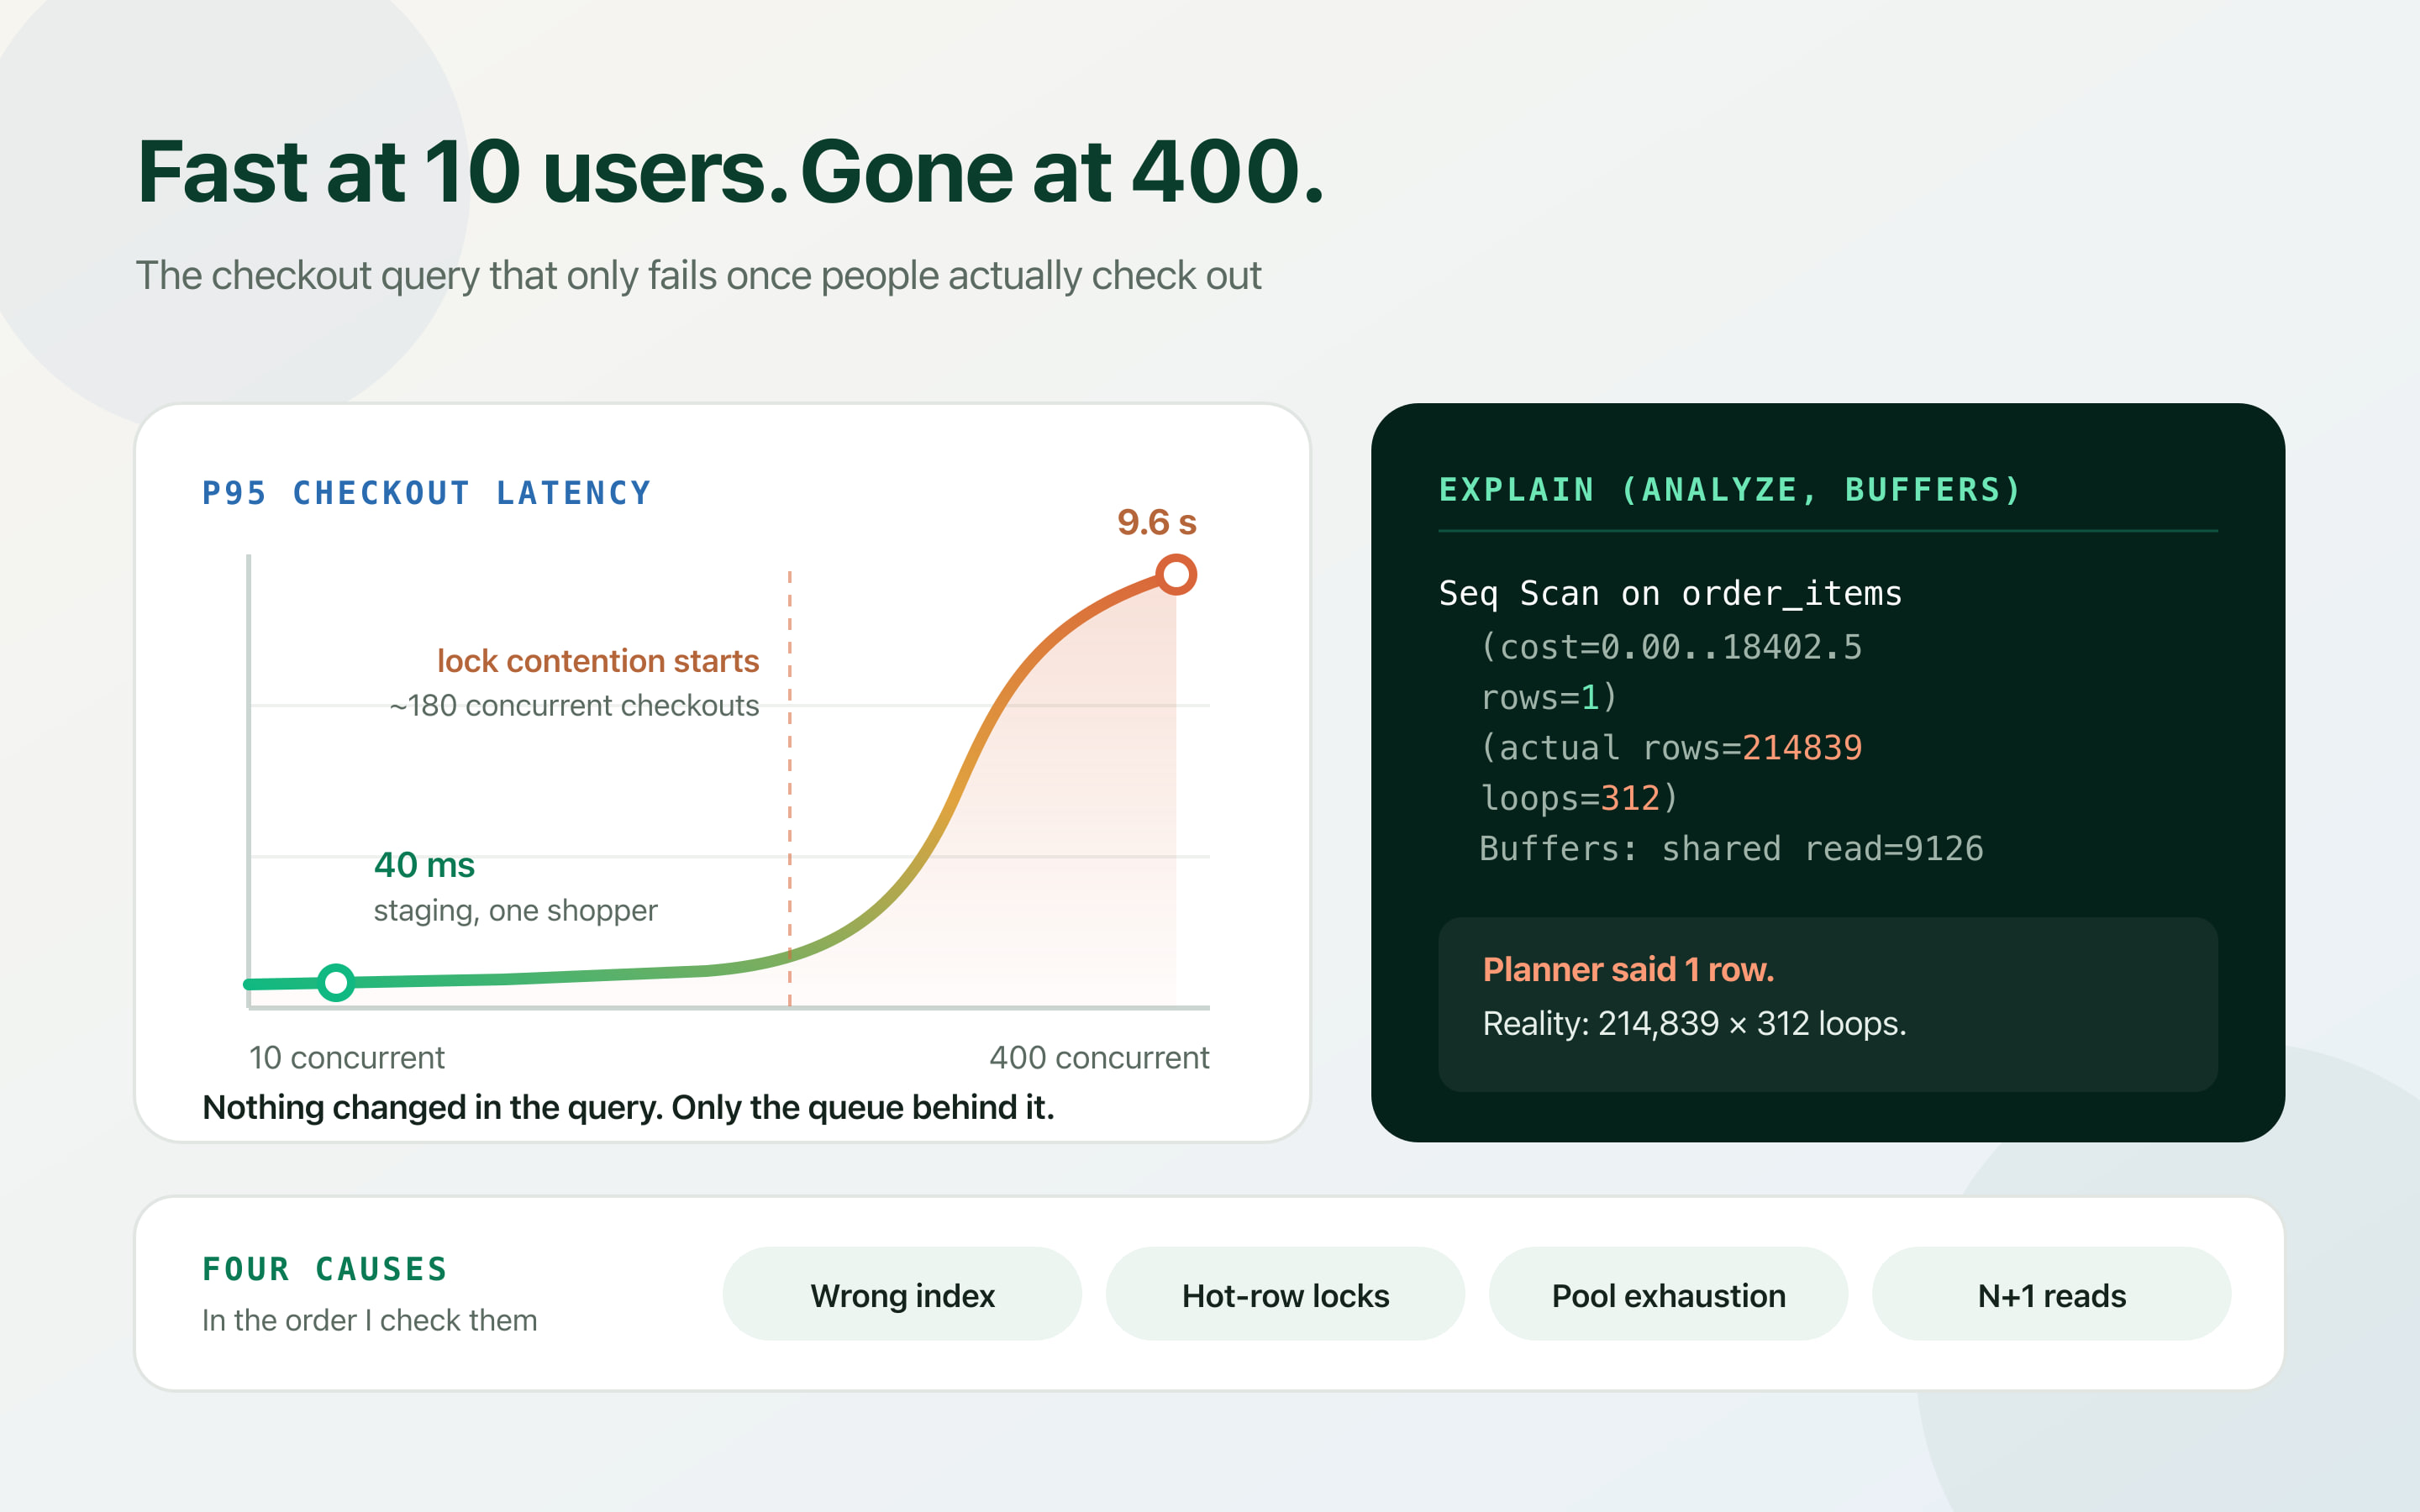
How to Fix Postgres Checkout Query Latency Under Load
Your checkout is fast until about 180 concurrent shoppers, then it falls off a cliff. Here's how to read the plan, find the lock window, and fix the four causes I actually find — in the order that pays off fastest.
Read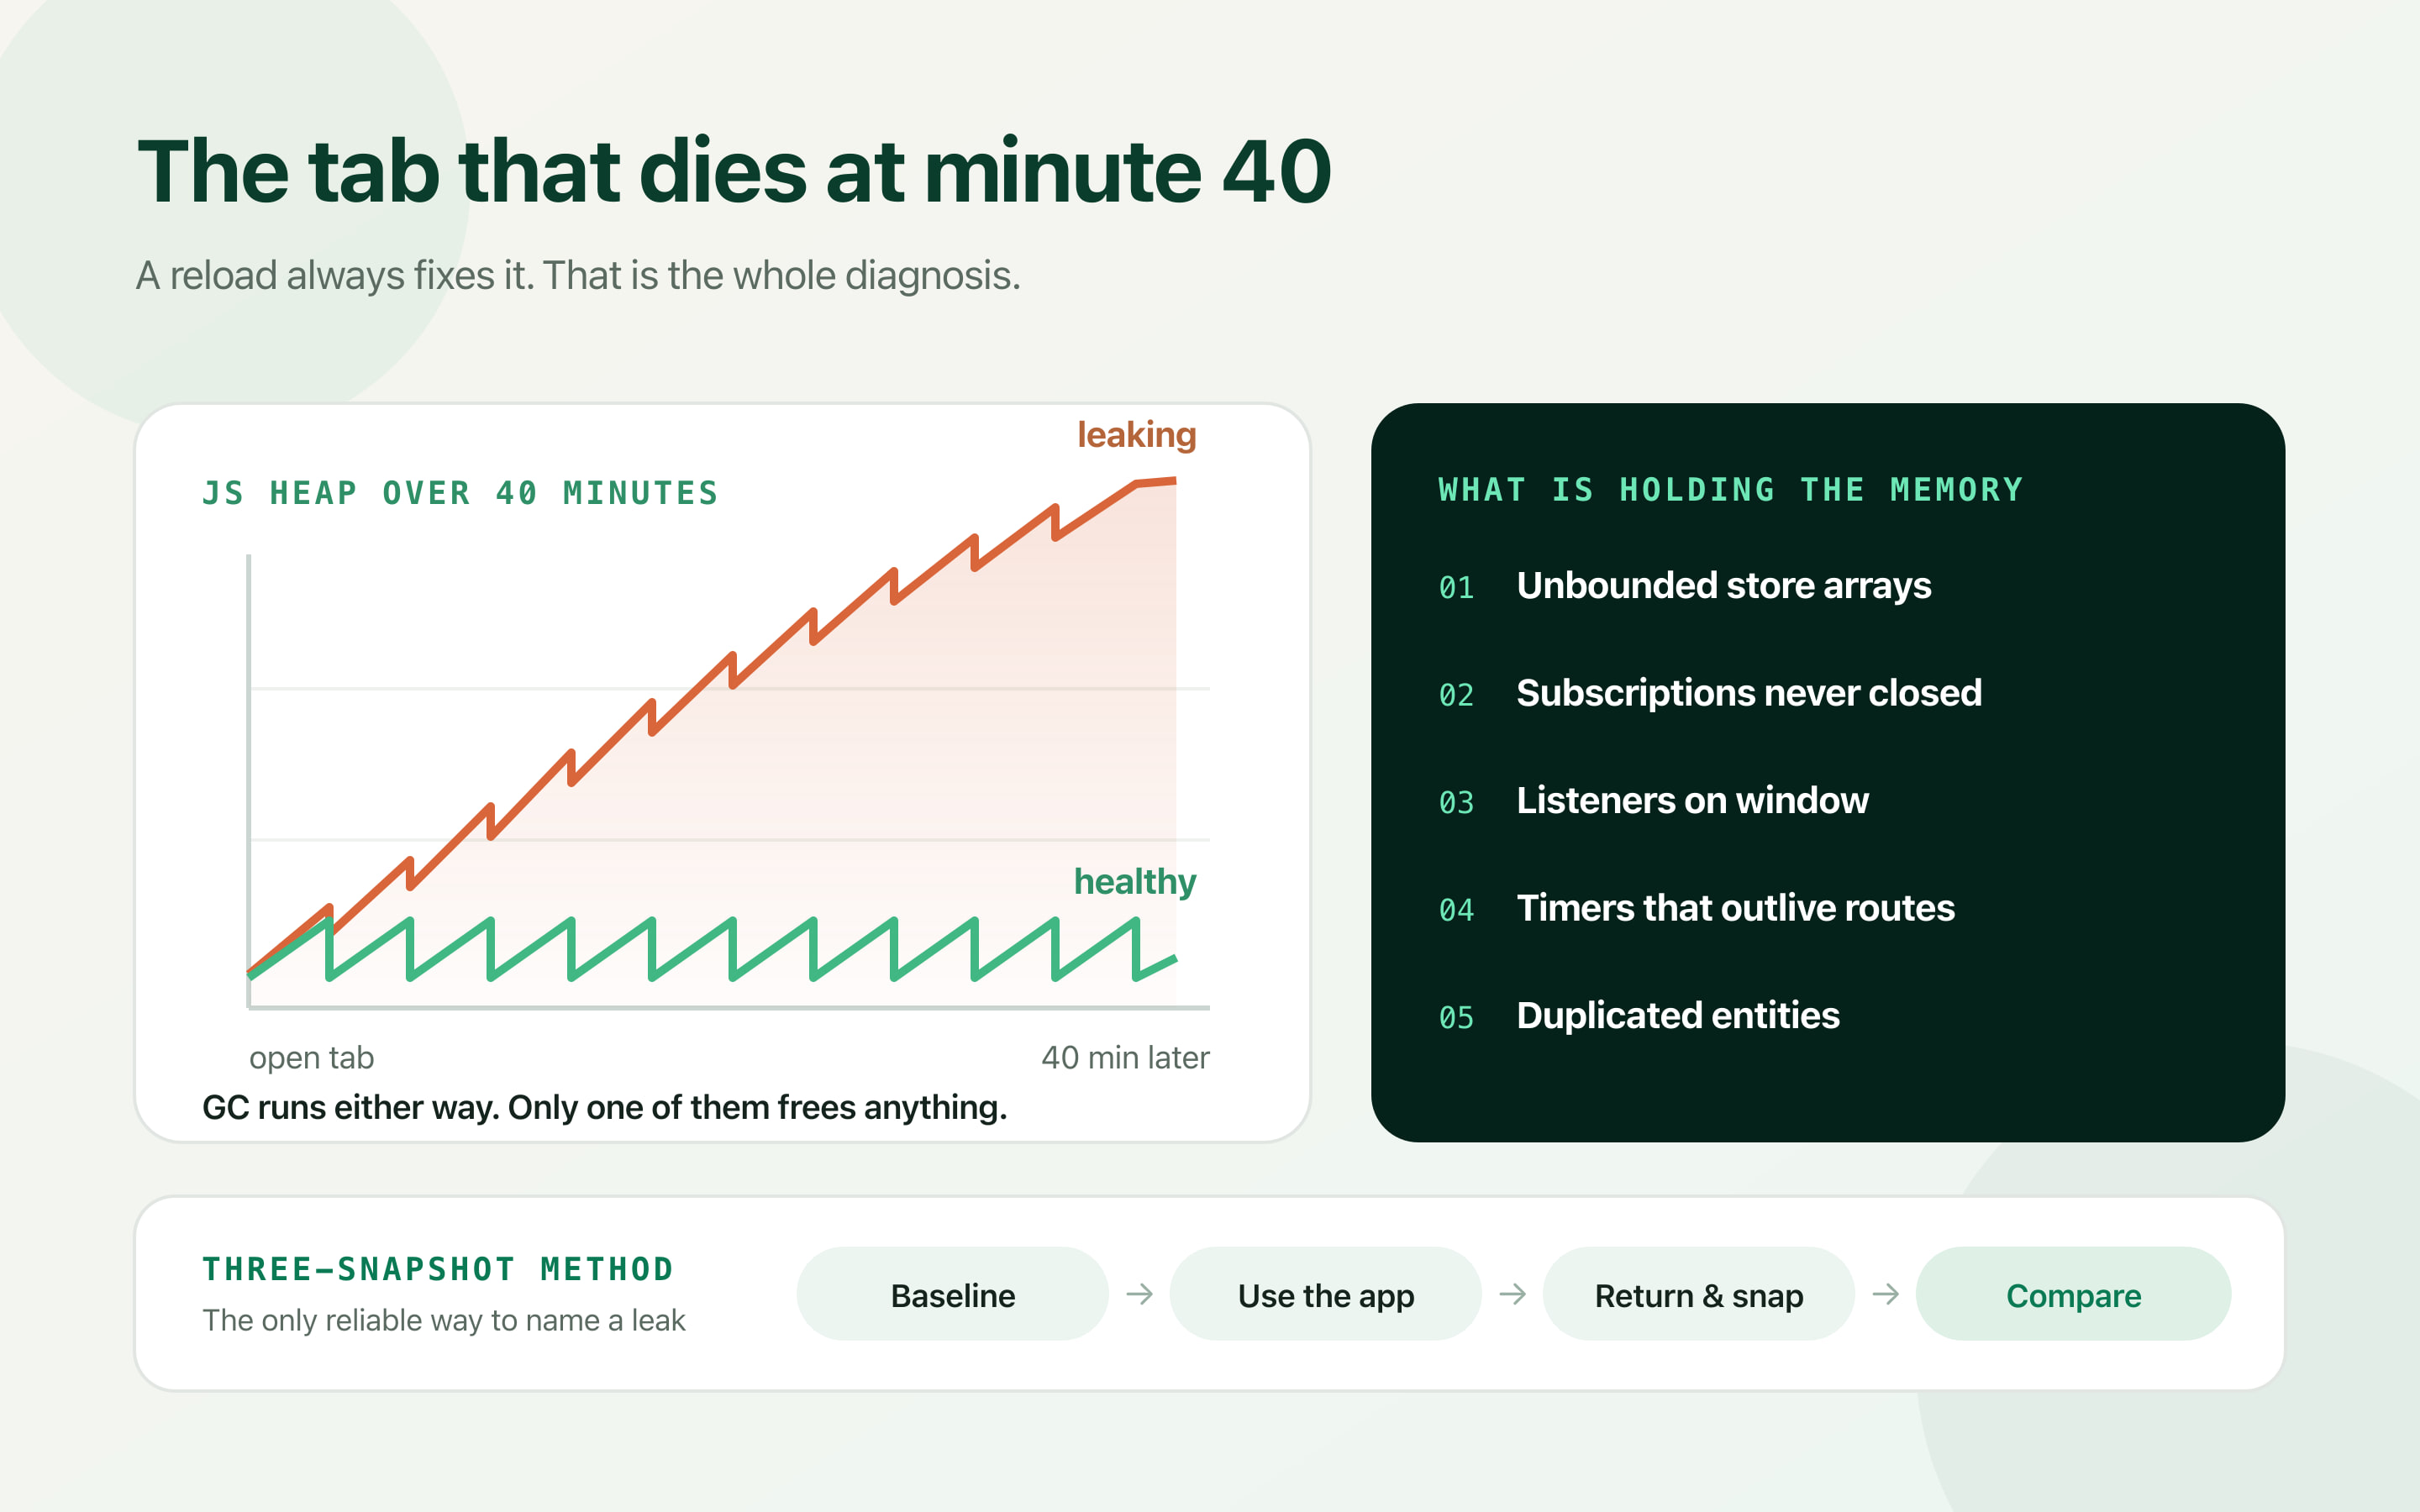
Debugging Memory Leaks in High-Frequency Vuex Applications
“It gets slow after a while, but a refresh fixes it.” That sentence is a complete diagnosis. Here's how to read a heap snapshot properly and the five retention patterns that cause almost every Vuex leak.
Read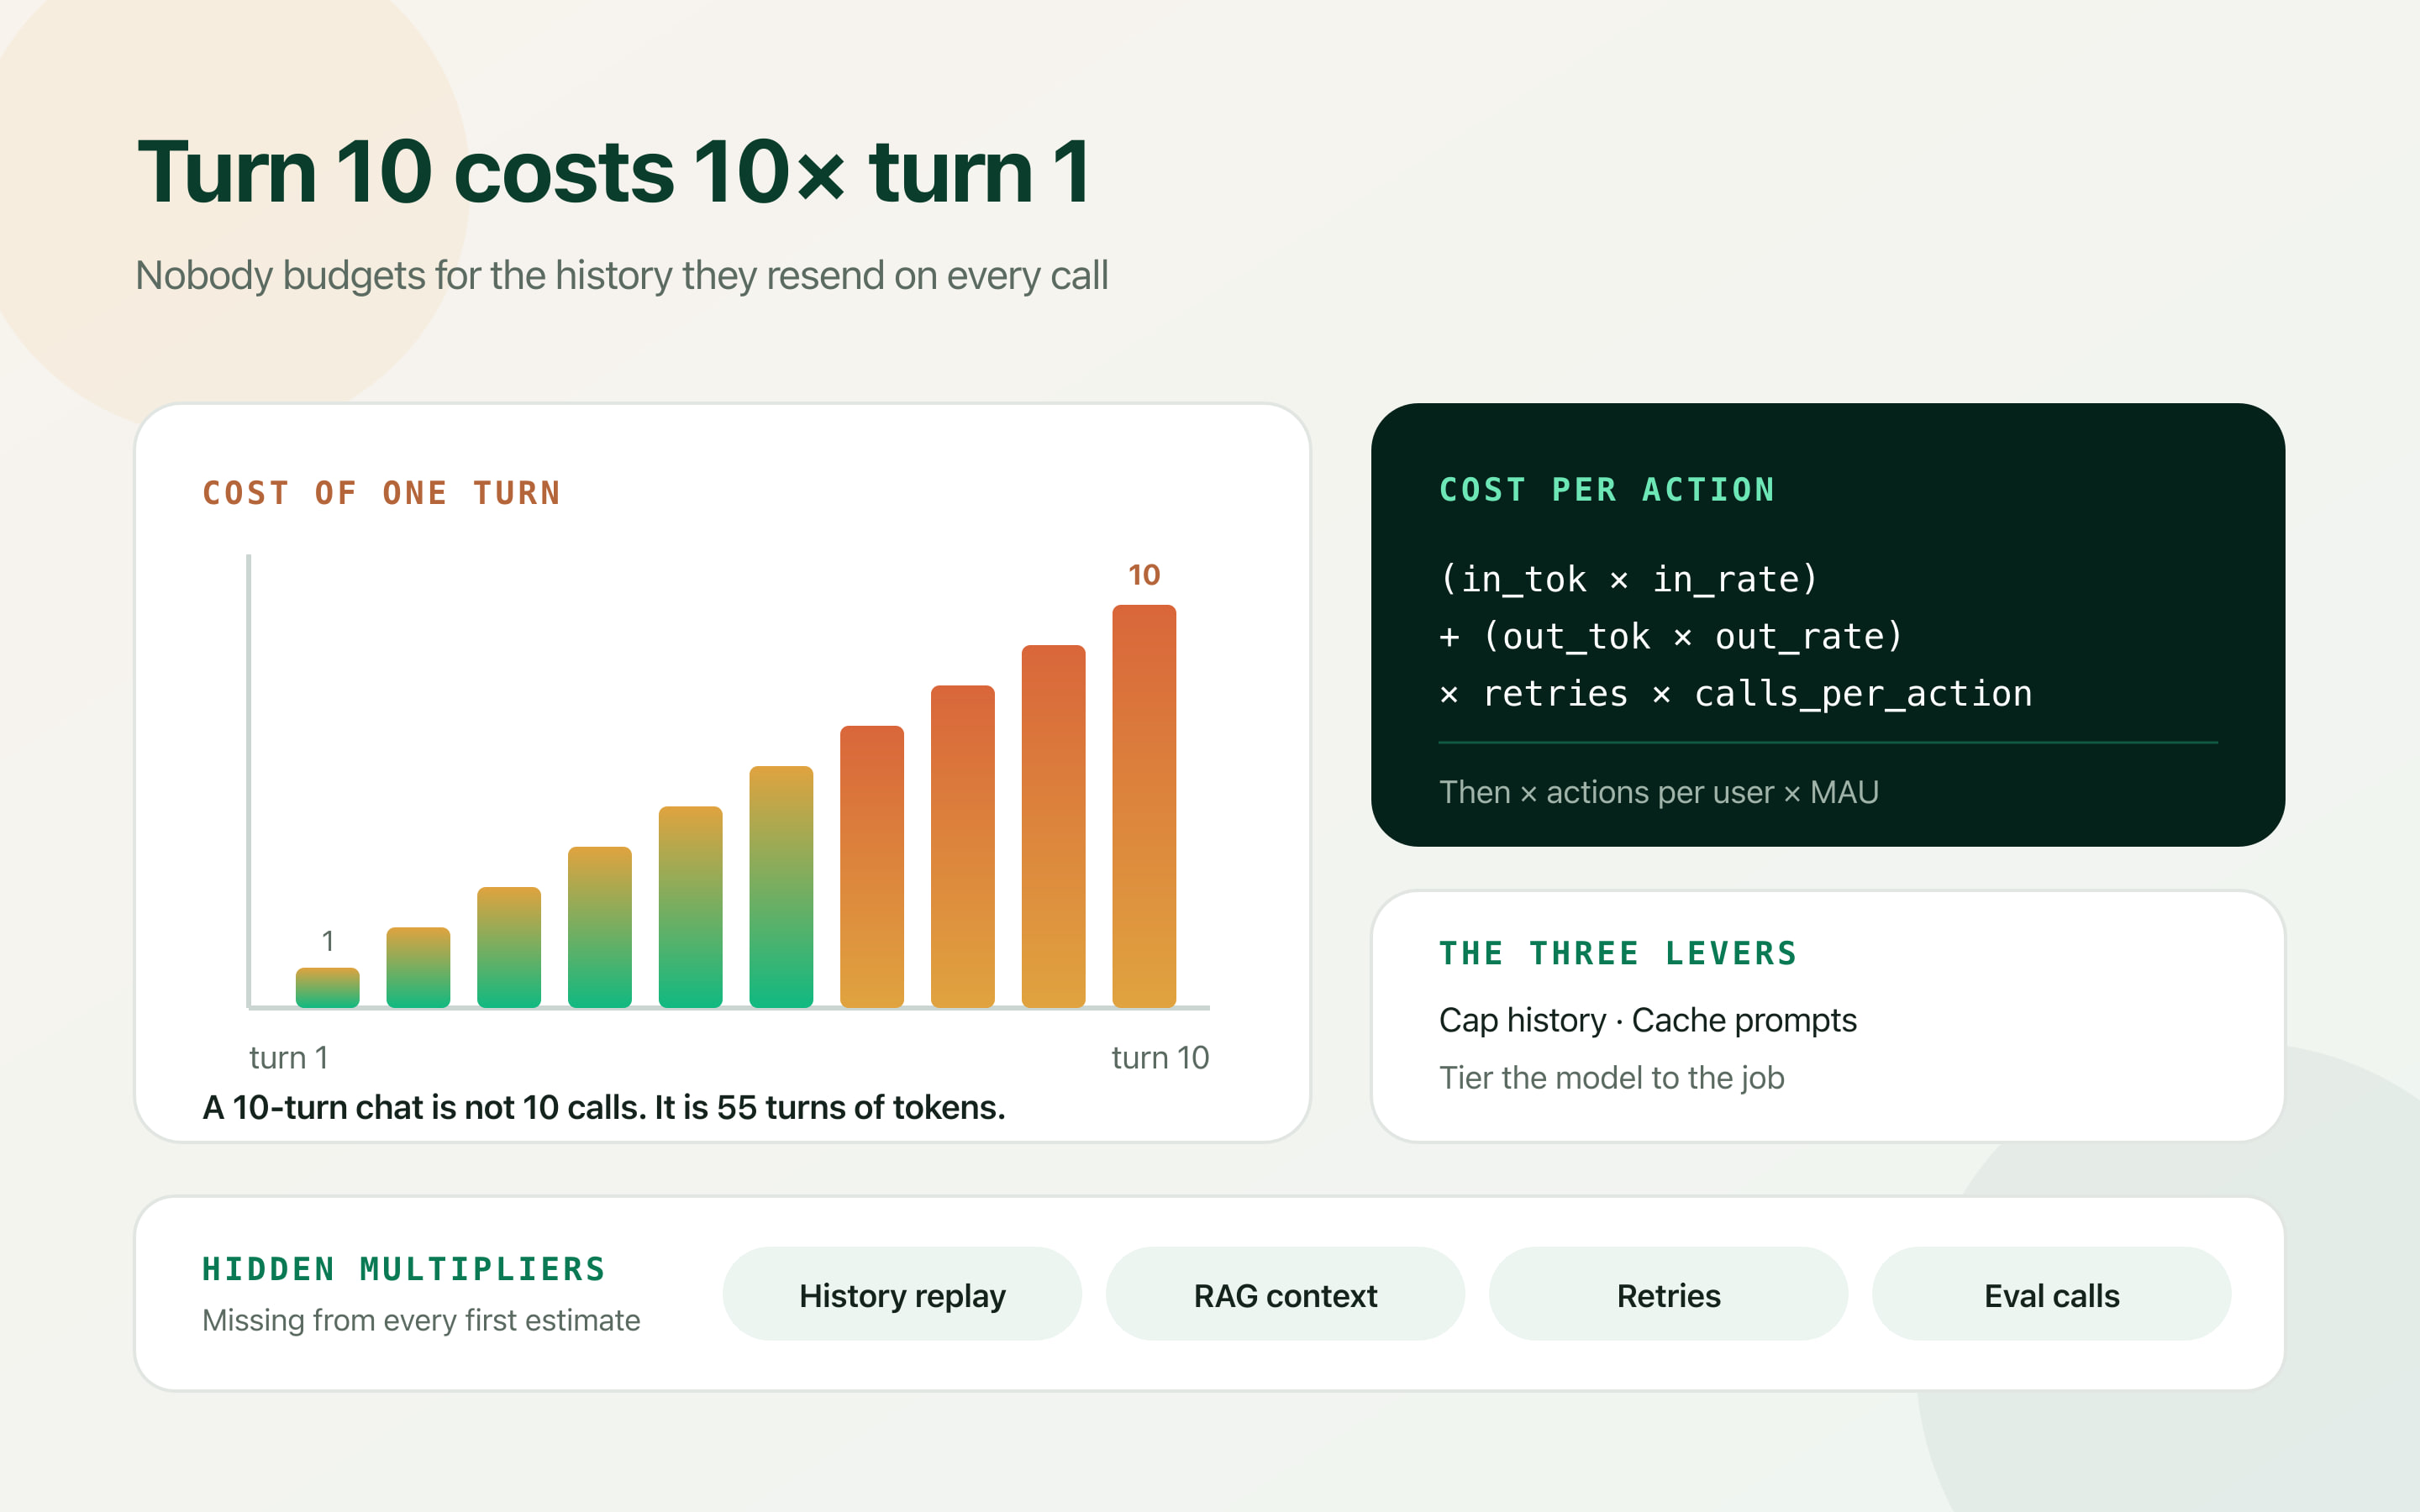
A Cost Estimation Model for Production OpenAI API Integrations
Most AI budgets are built by dividing a token price by a guess. Here's the model I use instead — cost per completed action, the quadratic history problem, and the three levers that actually move the bill.
Read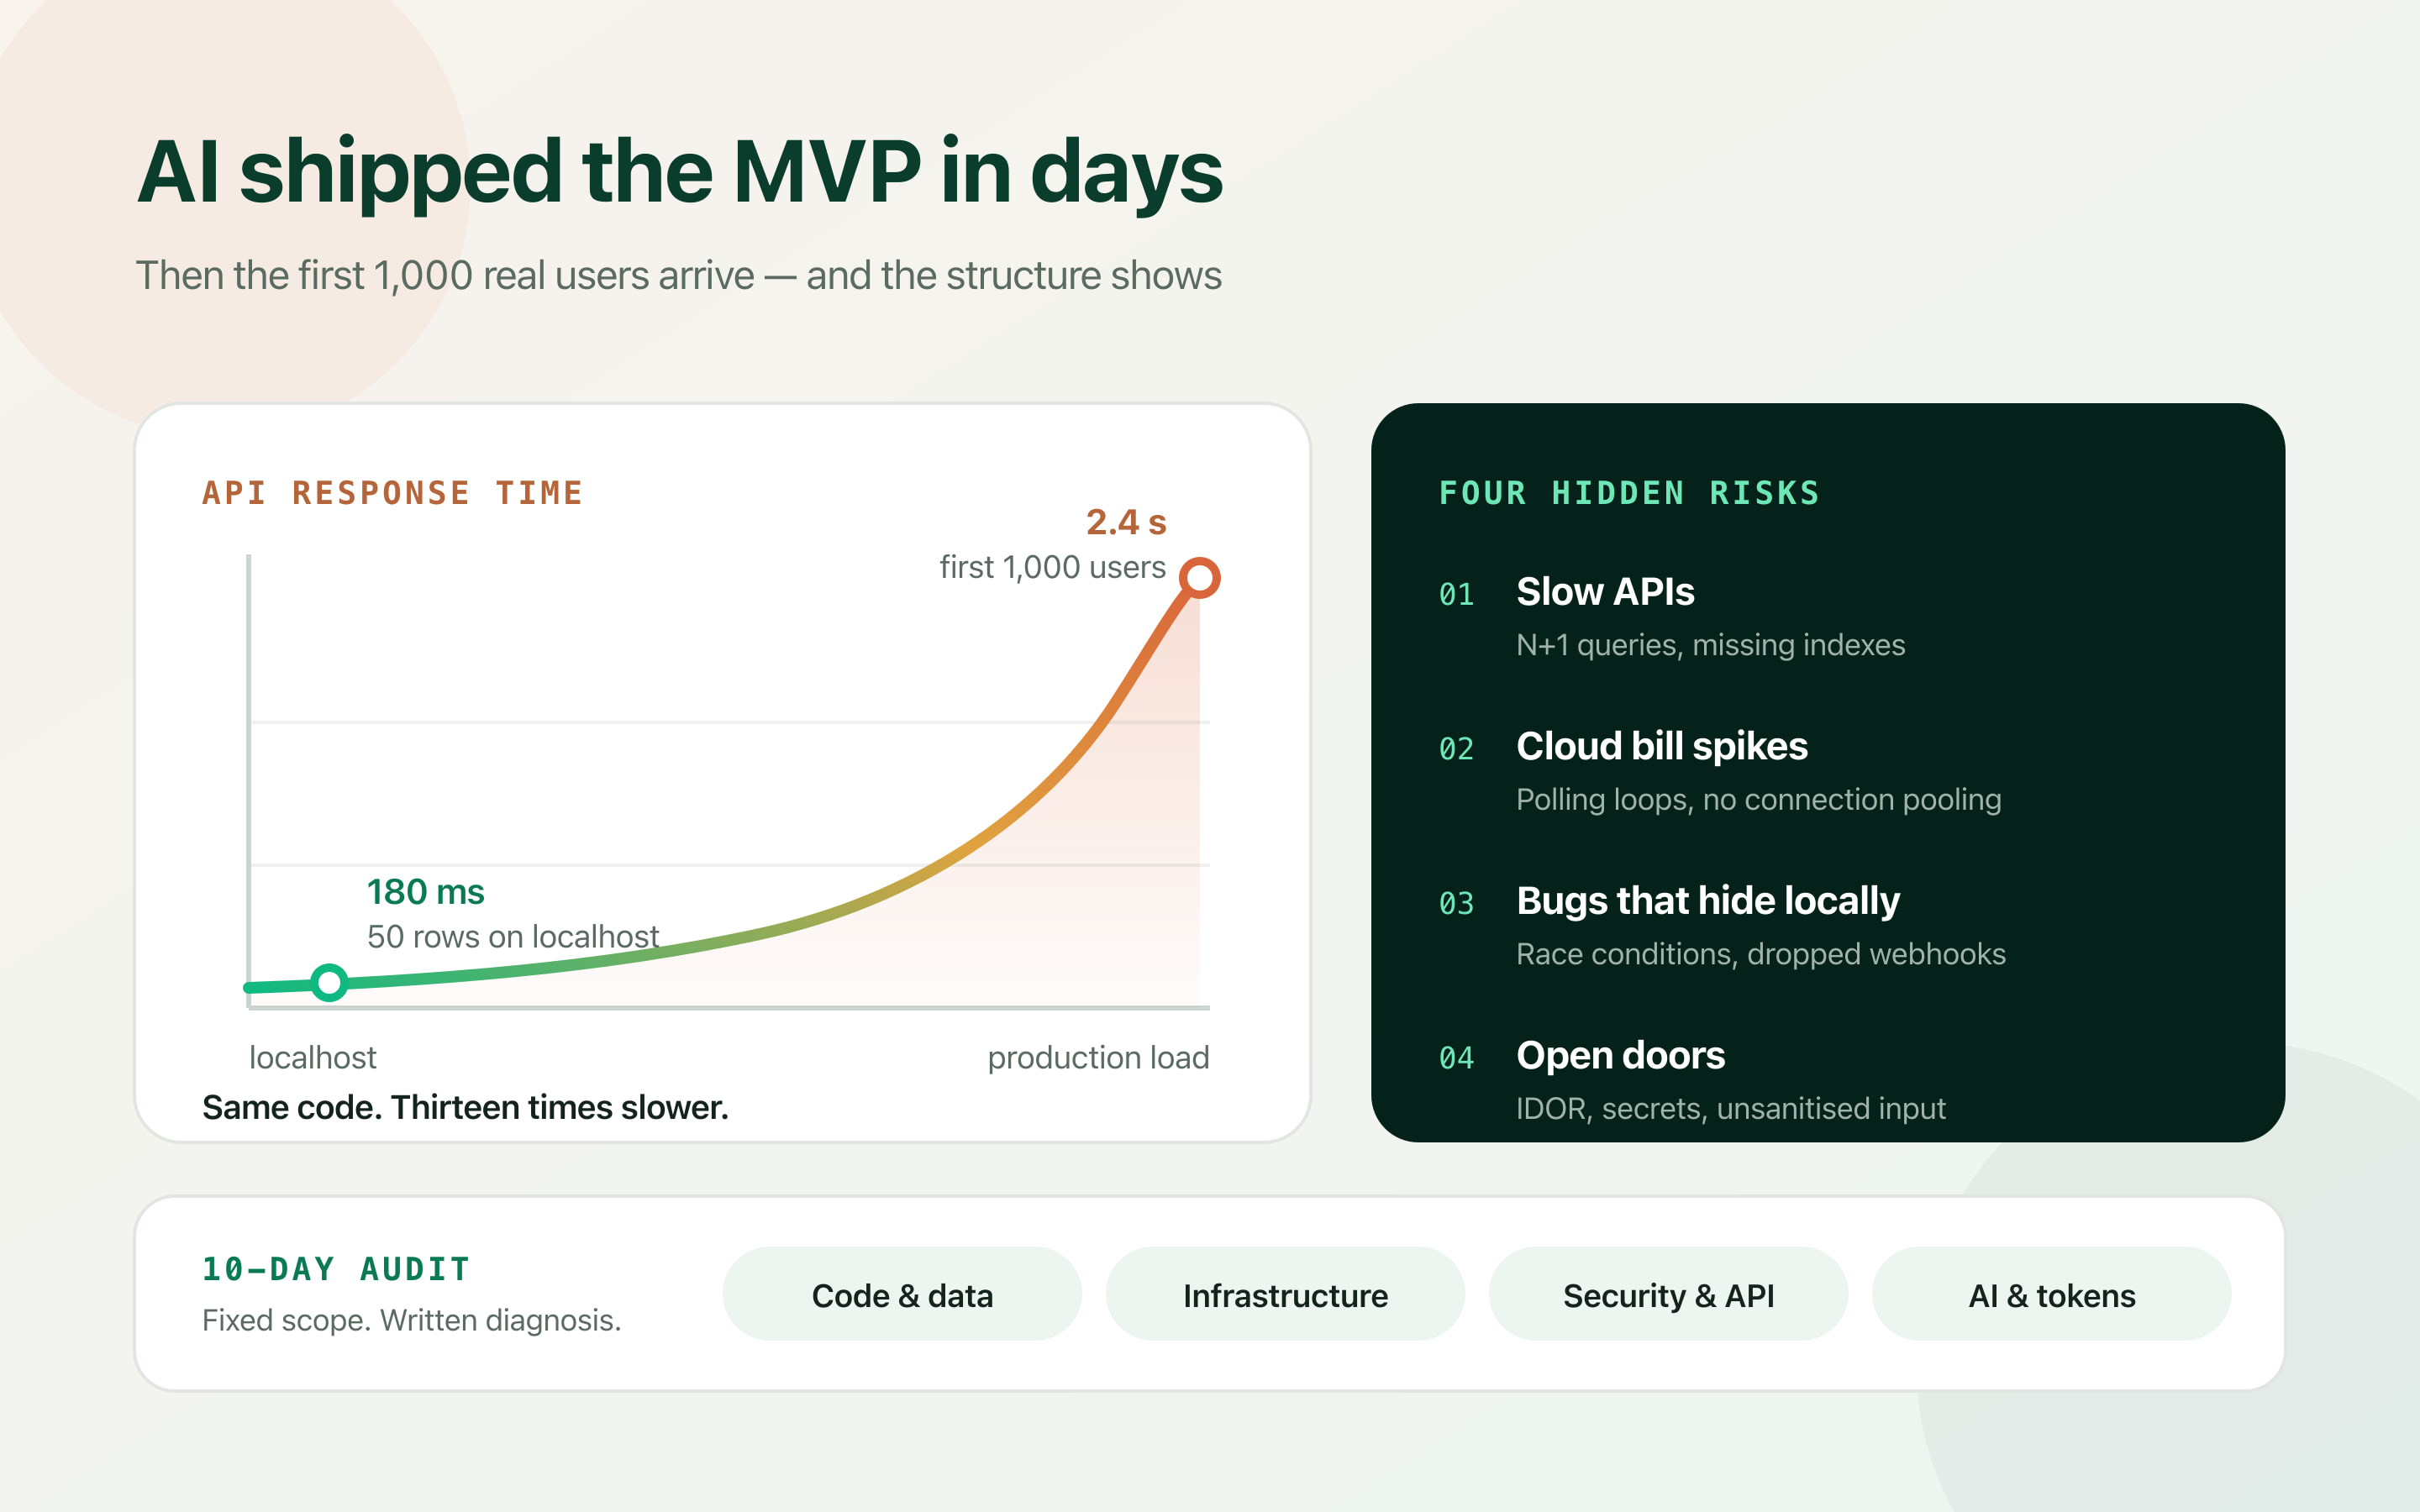
Just Built Your MVP with AI? Why You Need a Codebase Audit Before Scaling
Cursor, Claude Code and Copilot get a founder to launch in days. They also leave N+1 queries, unbounded polling, IDOR holes and race conditions behind. Here’s what breaks at 1,000 users and how to find it first.
Read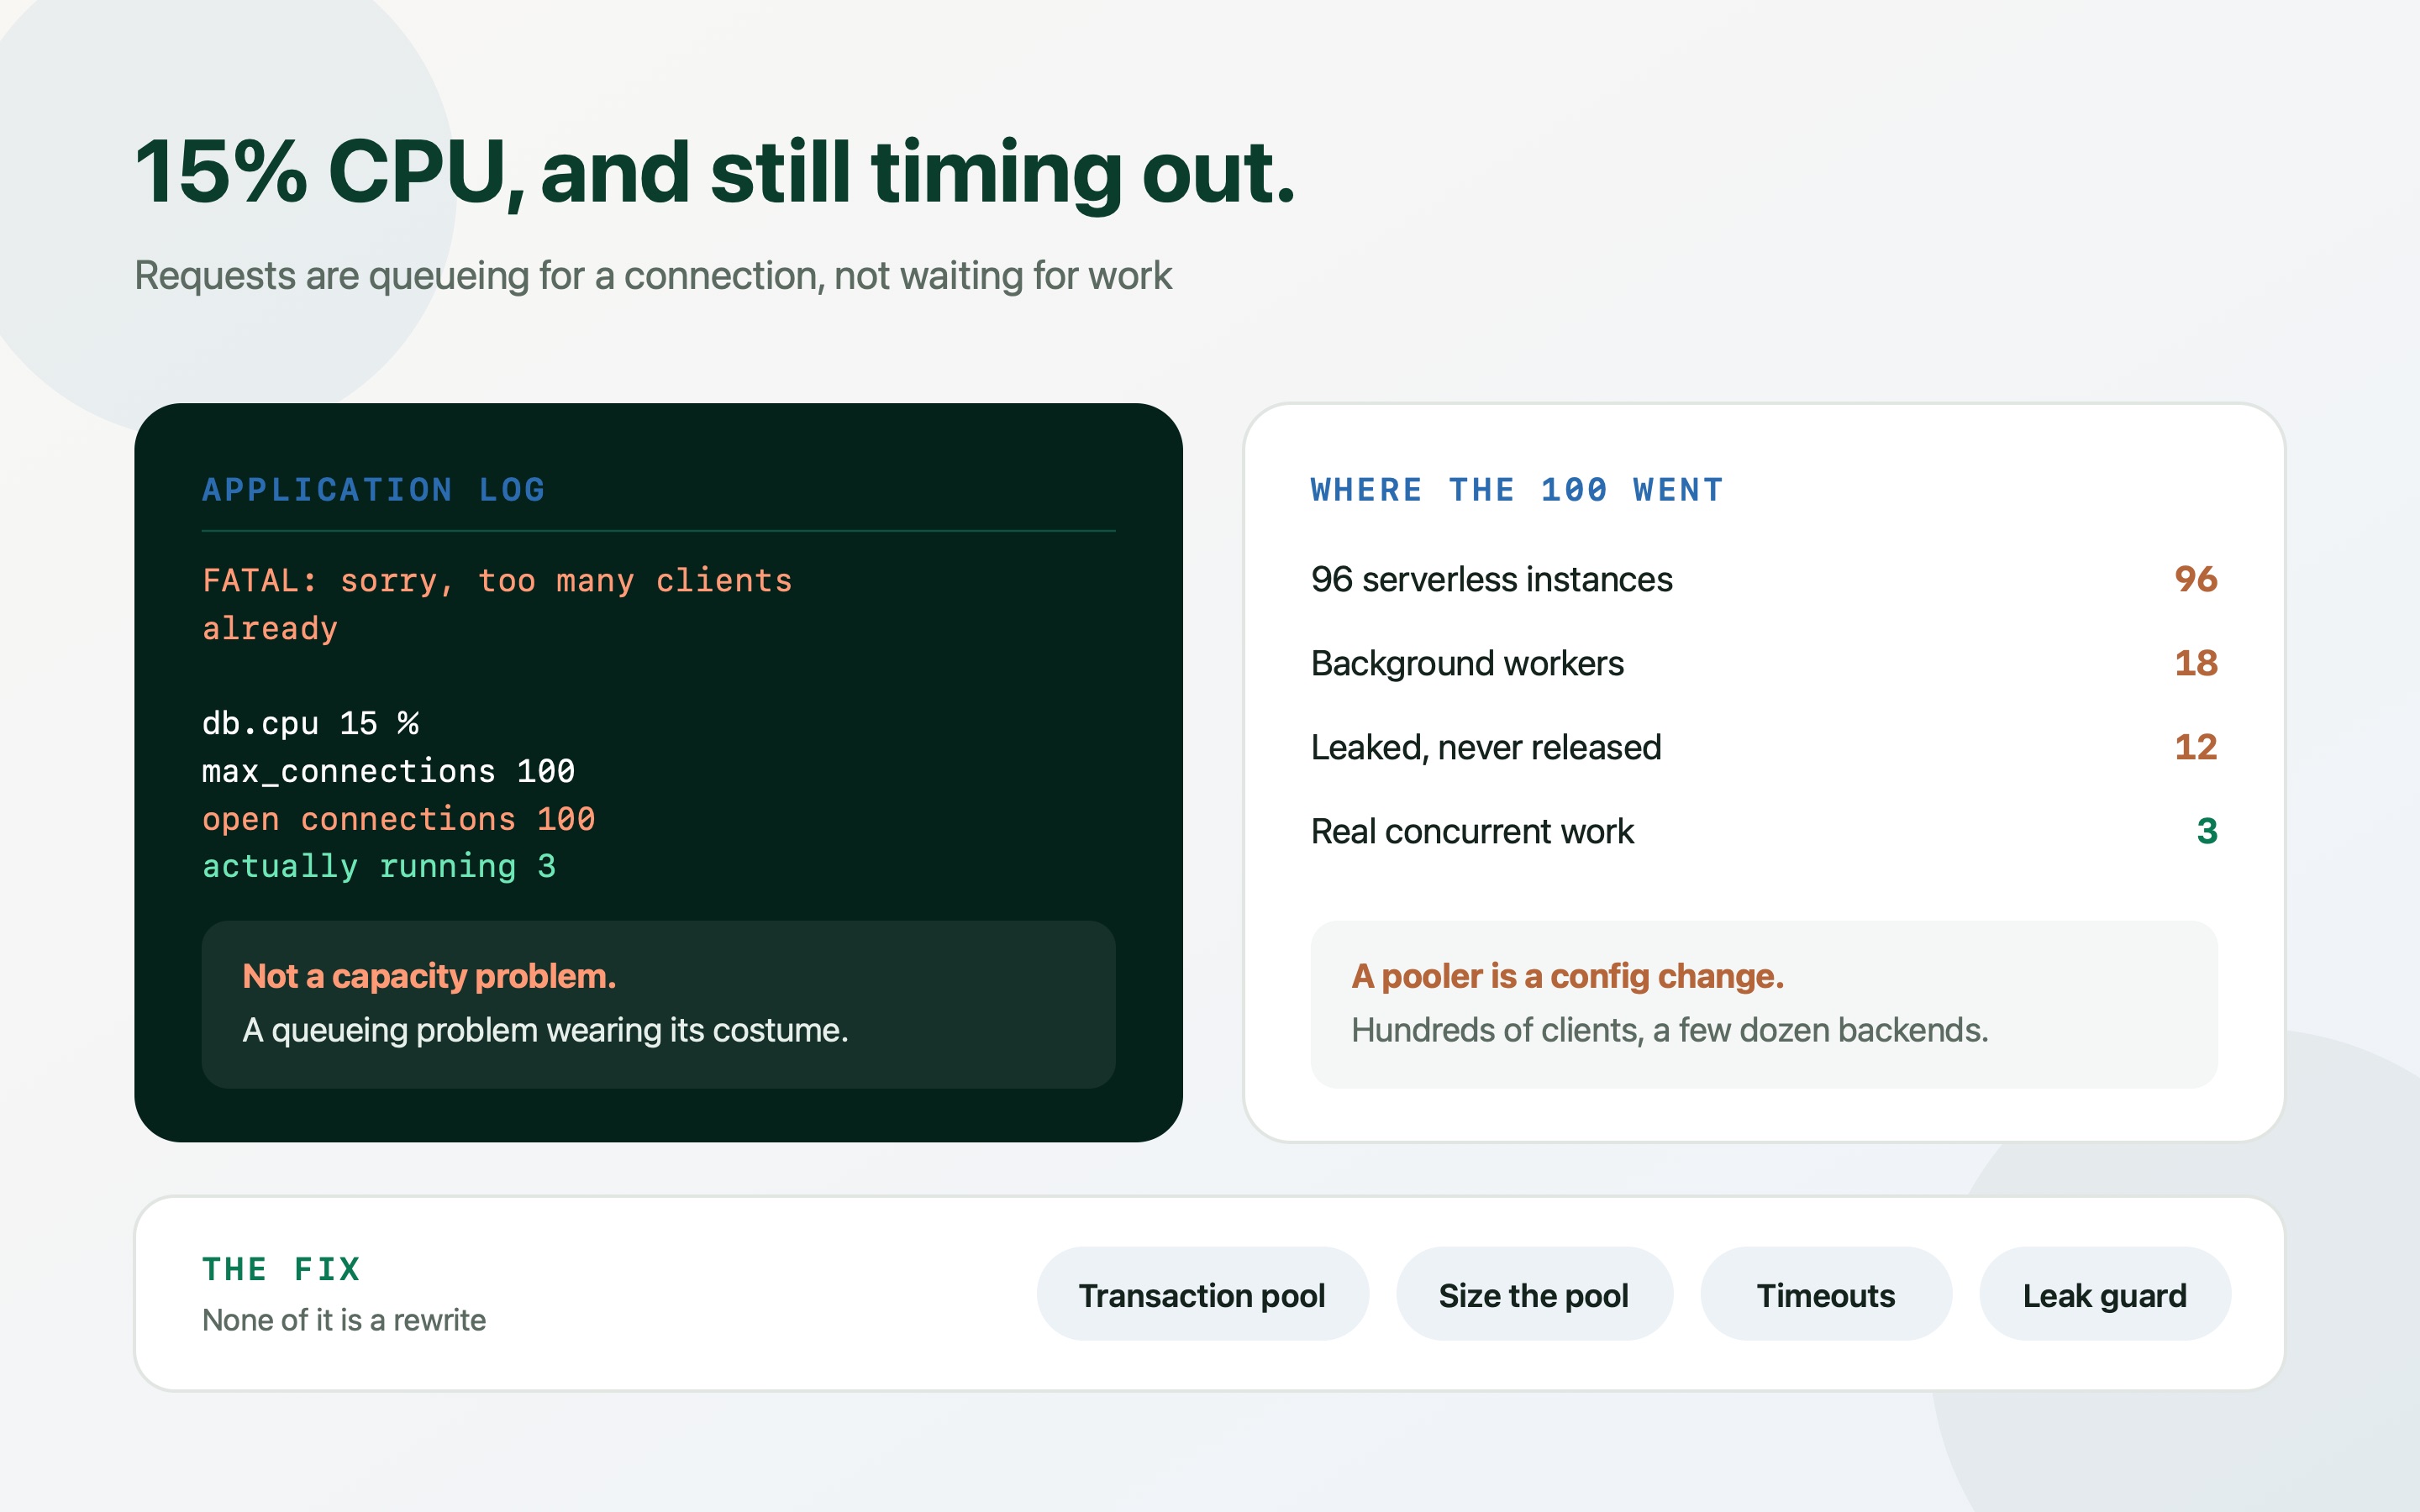
How to Eliminate Database Connection Exhaustion at Scale
Month-end hits and the database starts refusing connections while sitting at 15% CPU. Here's where the connections actually went, how to size the pool properly, and the PgBouncer settings that survive transaction mode.
Read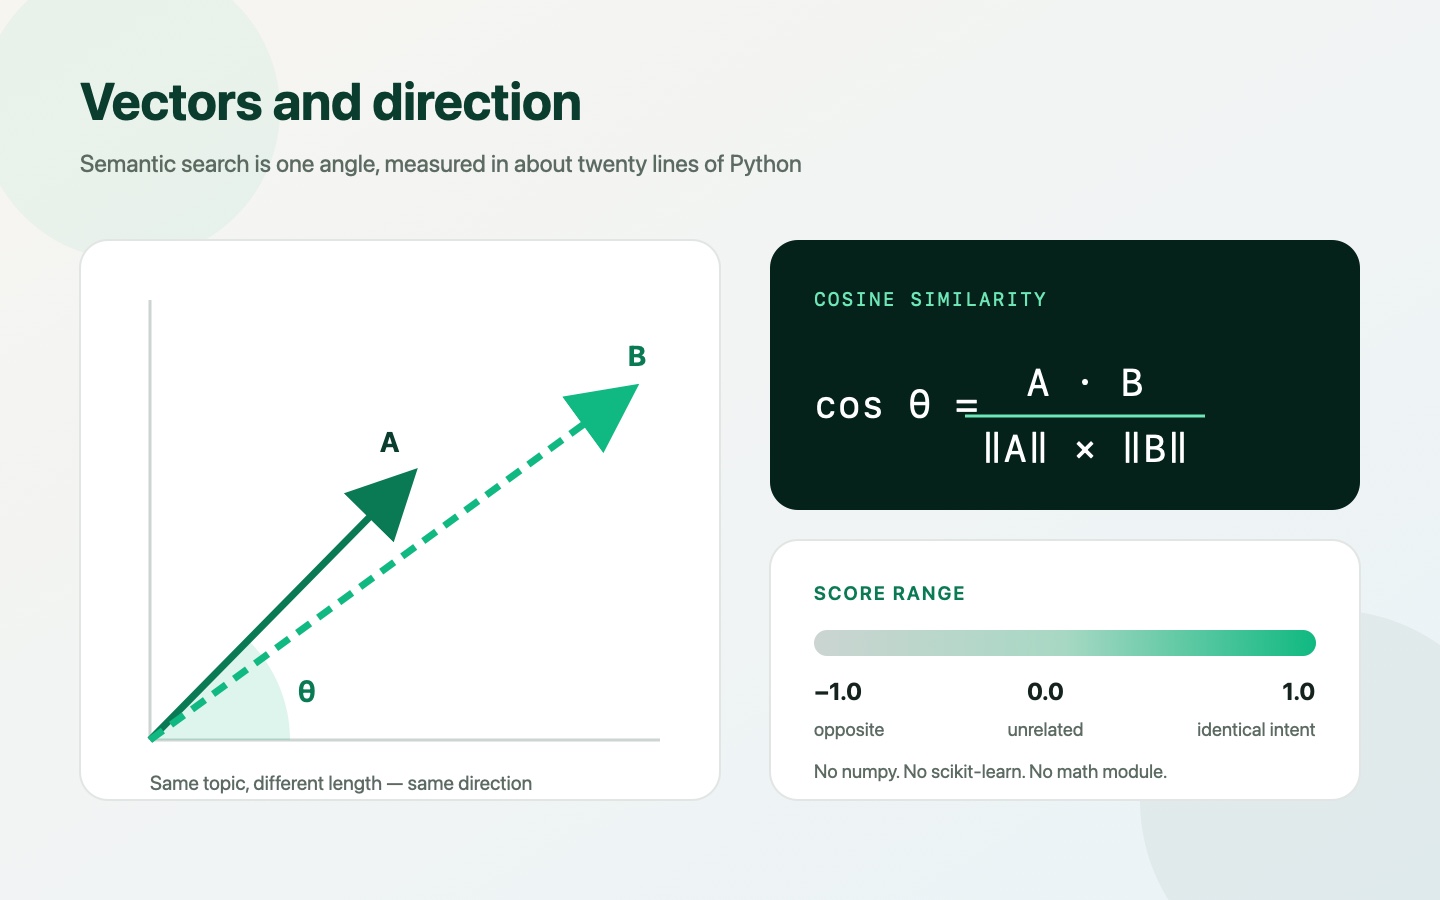
Why Your Next AI Application Doesn’t Need Heavy Math — Just Vectors and Direction
Most founders treat vector search like dark magic and pay for managed infrastructure before understanding how their data is queried. Here’s the whole mechanism, implemented from first principles in about 20 lines of Python.
Read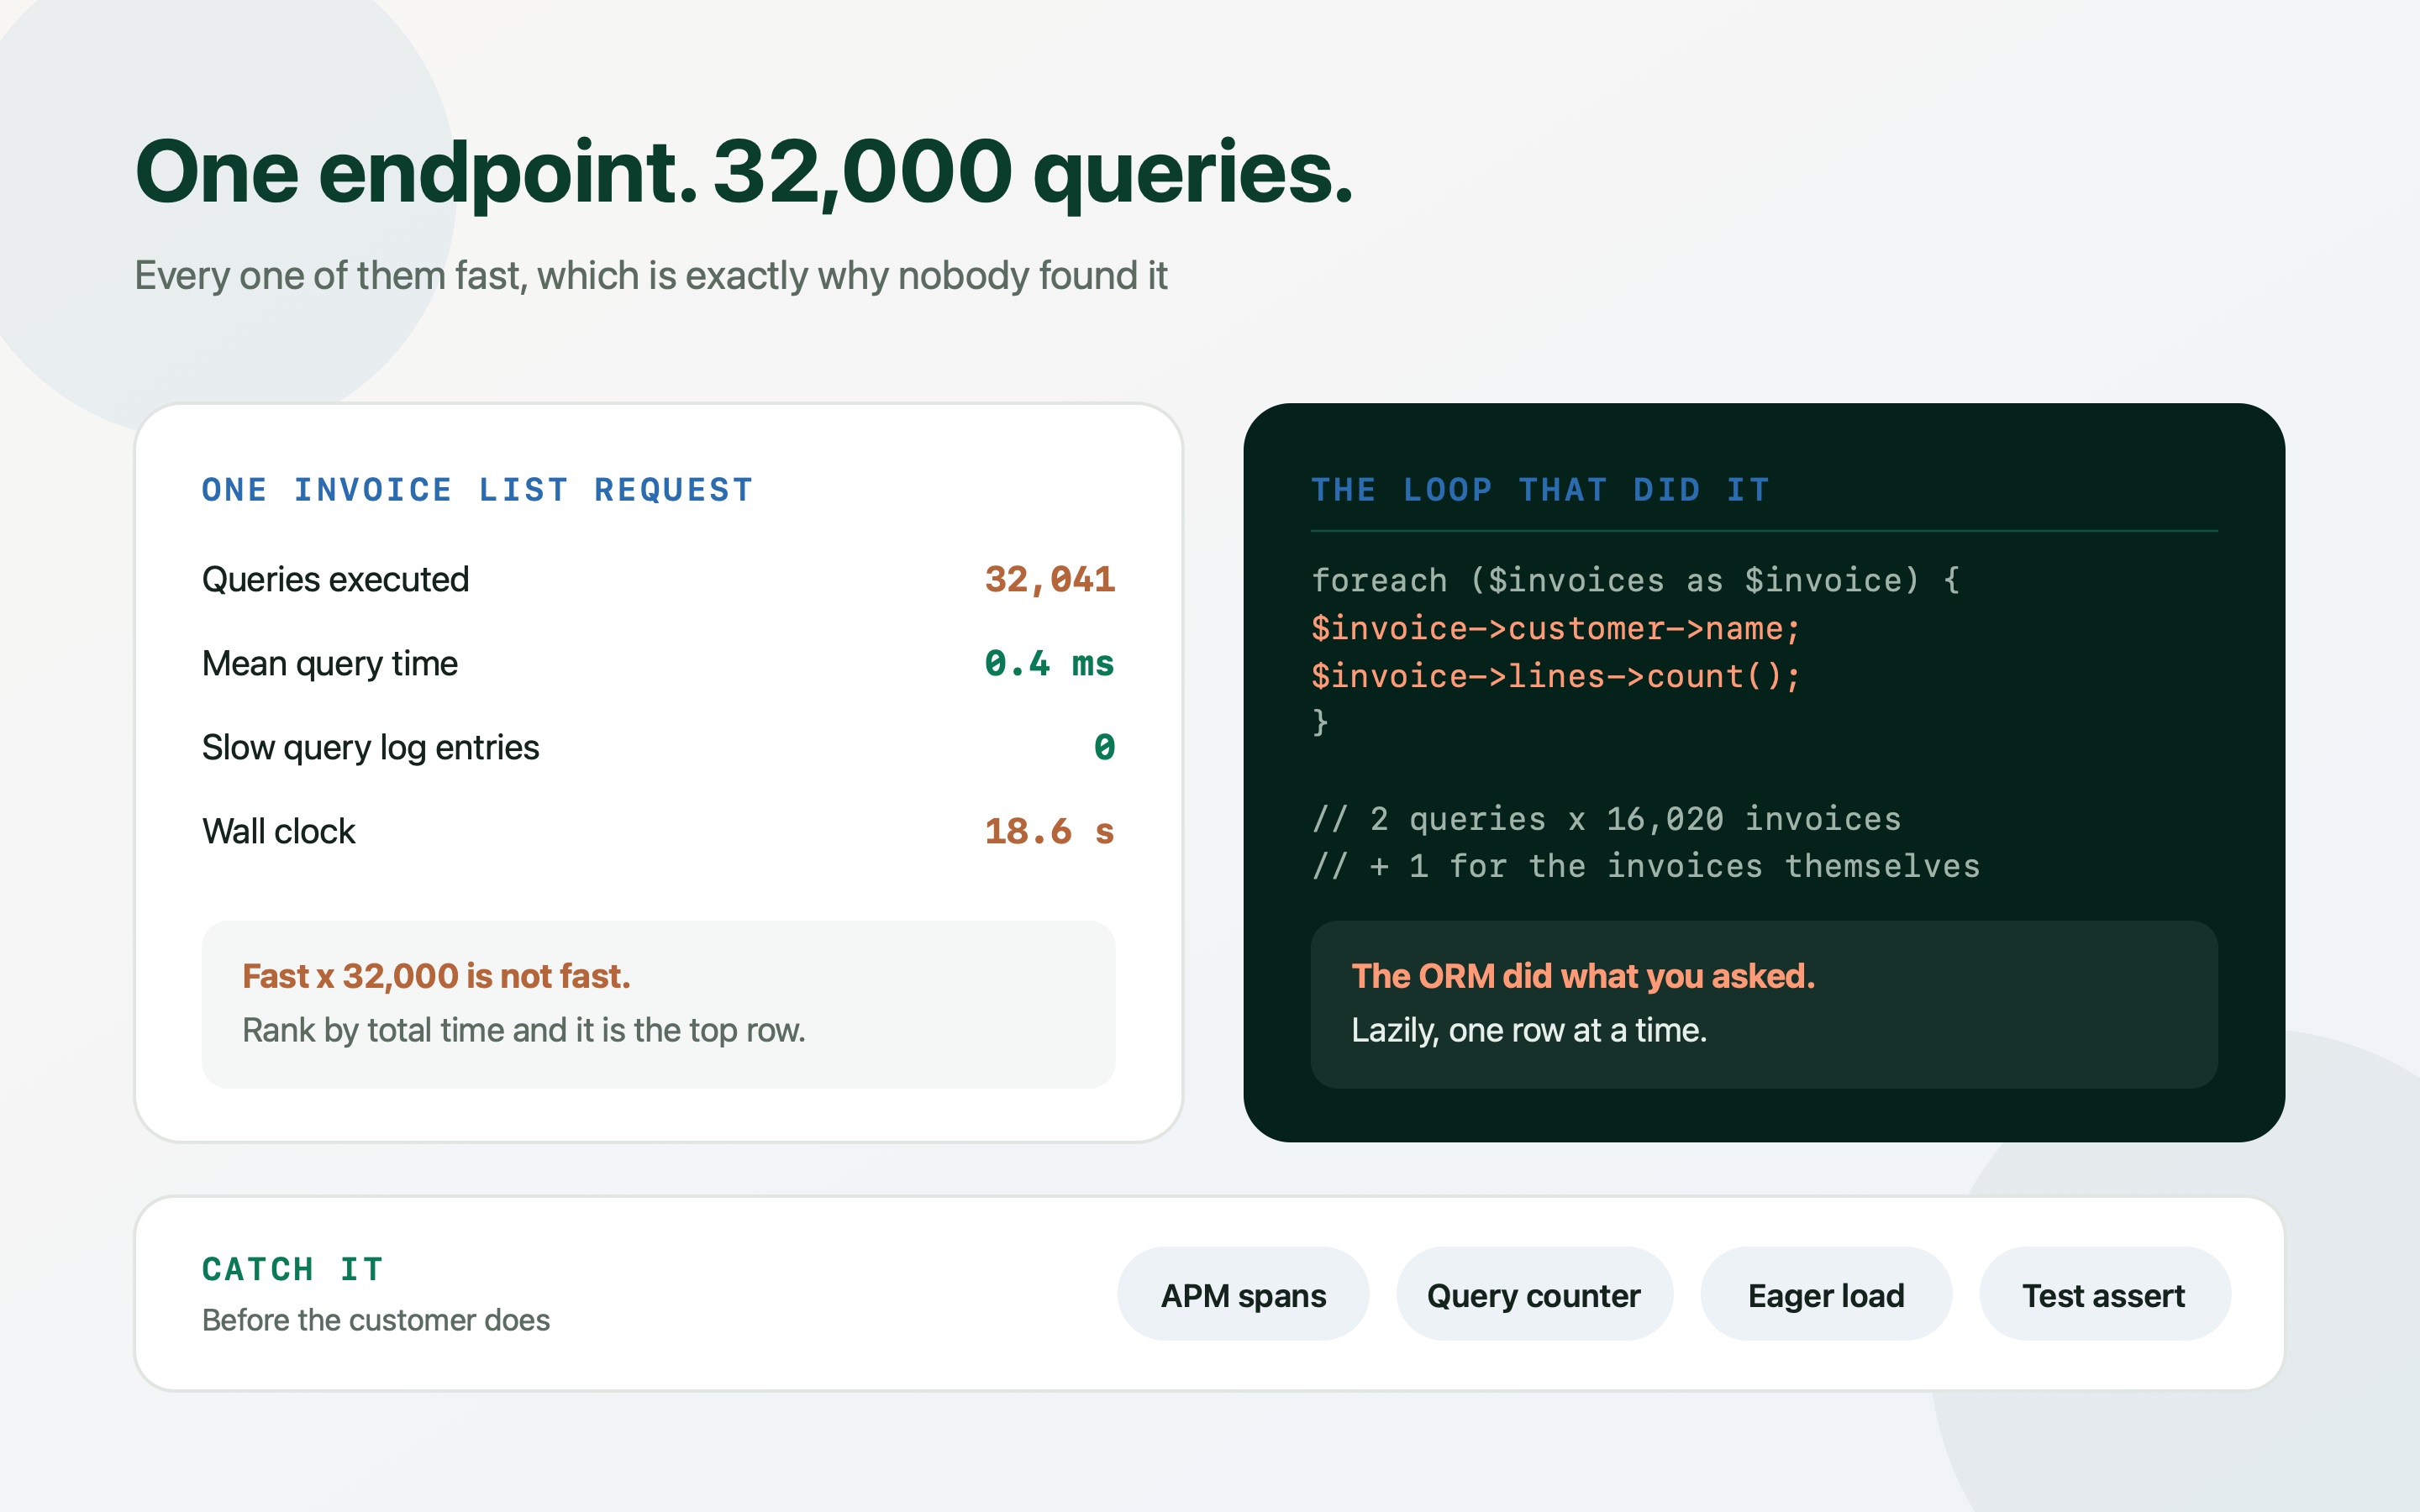
The N+1 Query Problem in Production: 32,000 Extra Calls in One Endpoint
An invoice list that took 18 seconds for large tenants and 200ms for everyone else. The cause was two lines in a loop and 32,041 individually fast queries — here's how to find yours and stop the next one in CI.
Read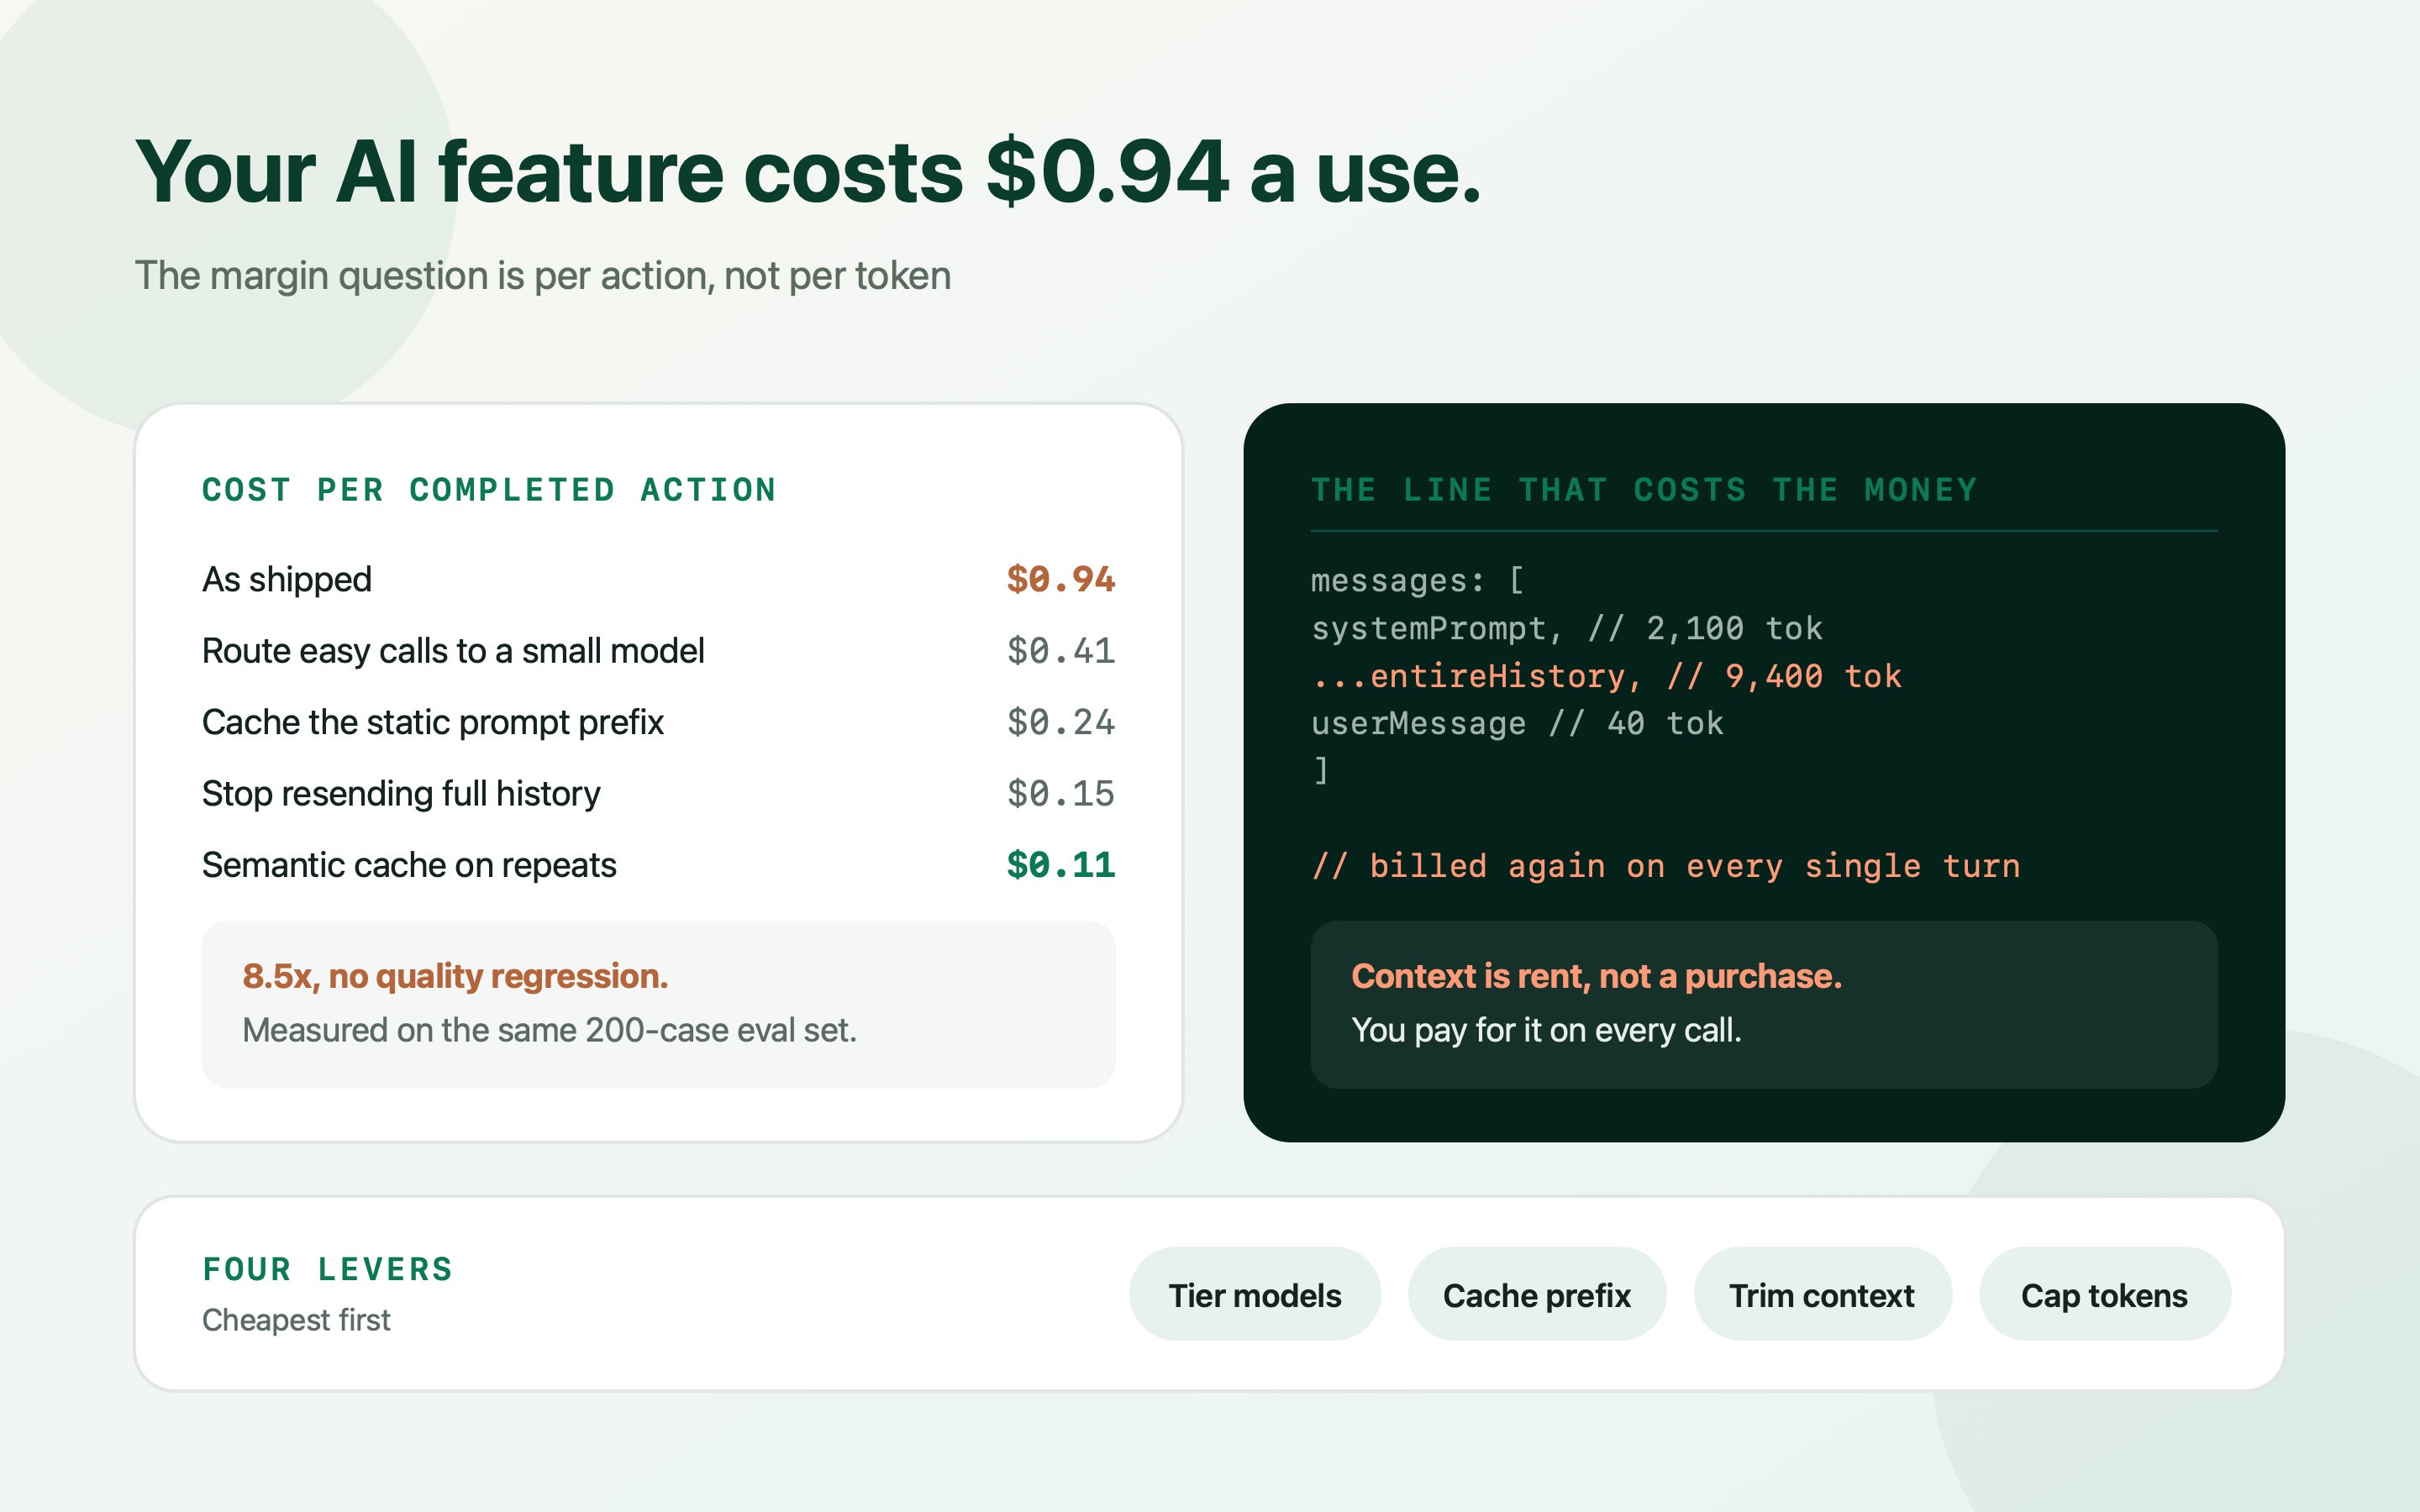
The Hidden Cost per Call: Architecting LLM Features That Don't Eat Your Margins
An AI feature that costs $0.94 per use has a pricing problem before it has a product problem. Five architectural levers — routing, prompt caching, context hygiene, semantic caching and output limits — measured on the same eval set.
Read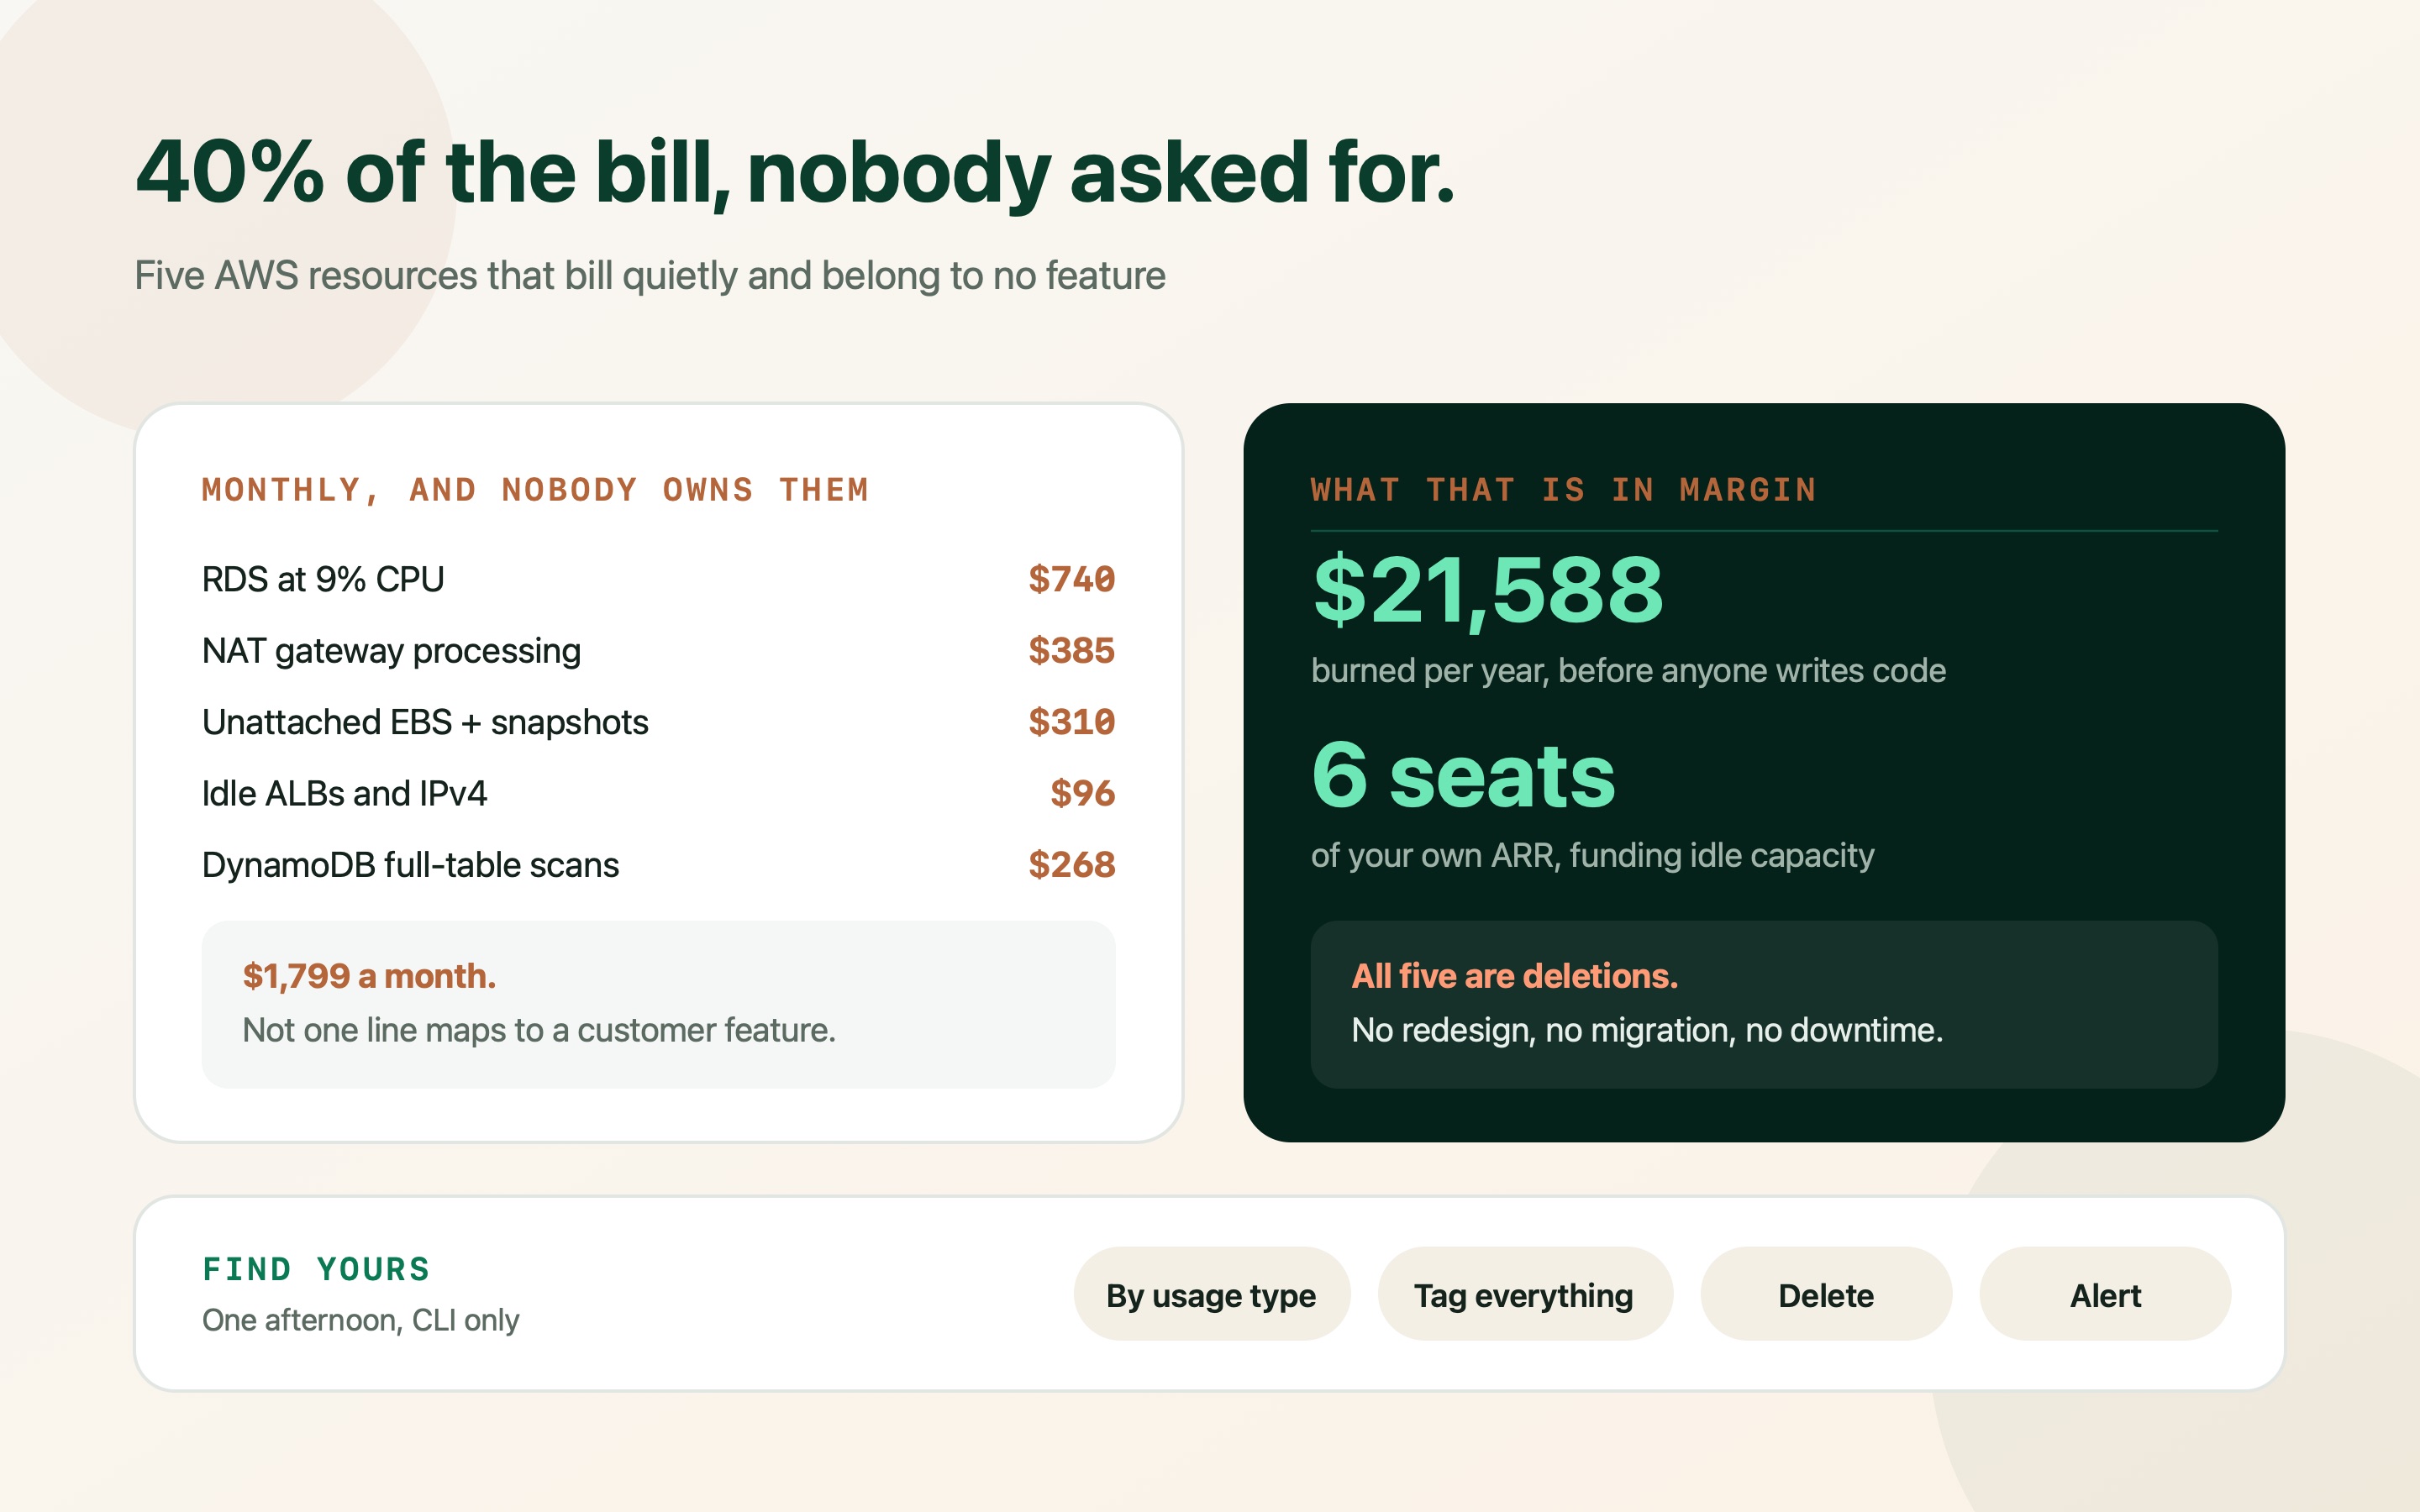
The Silent Cloud Sinks: 5 AWS Resources Burning 40% of Your SaaS Margin
Written for founders reading an AWS bill they did not expect. Five resources that charge for existing rather than working, what each one is in plain English, and the exact commands to find yours this afternoon.
Read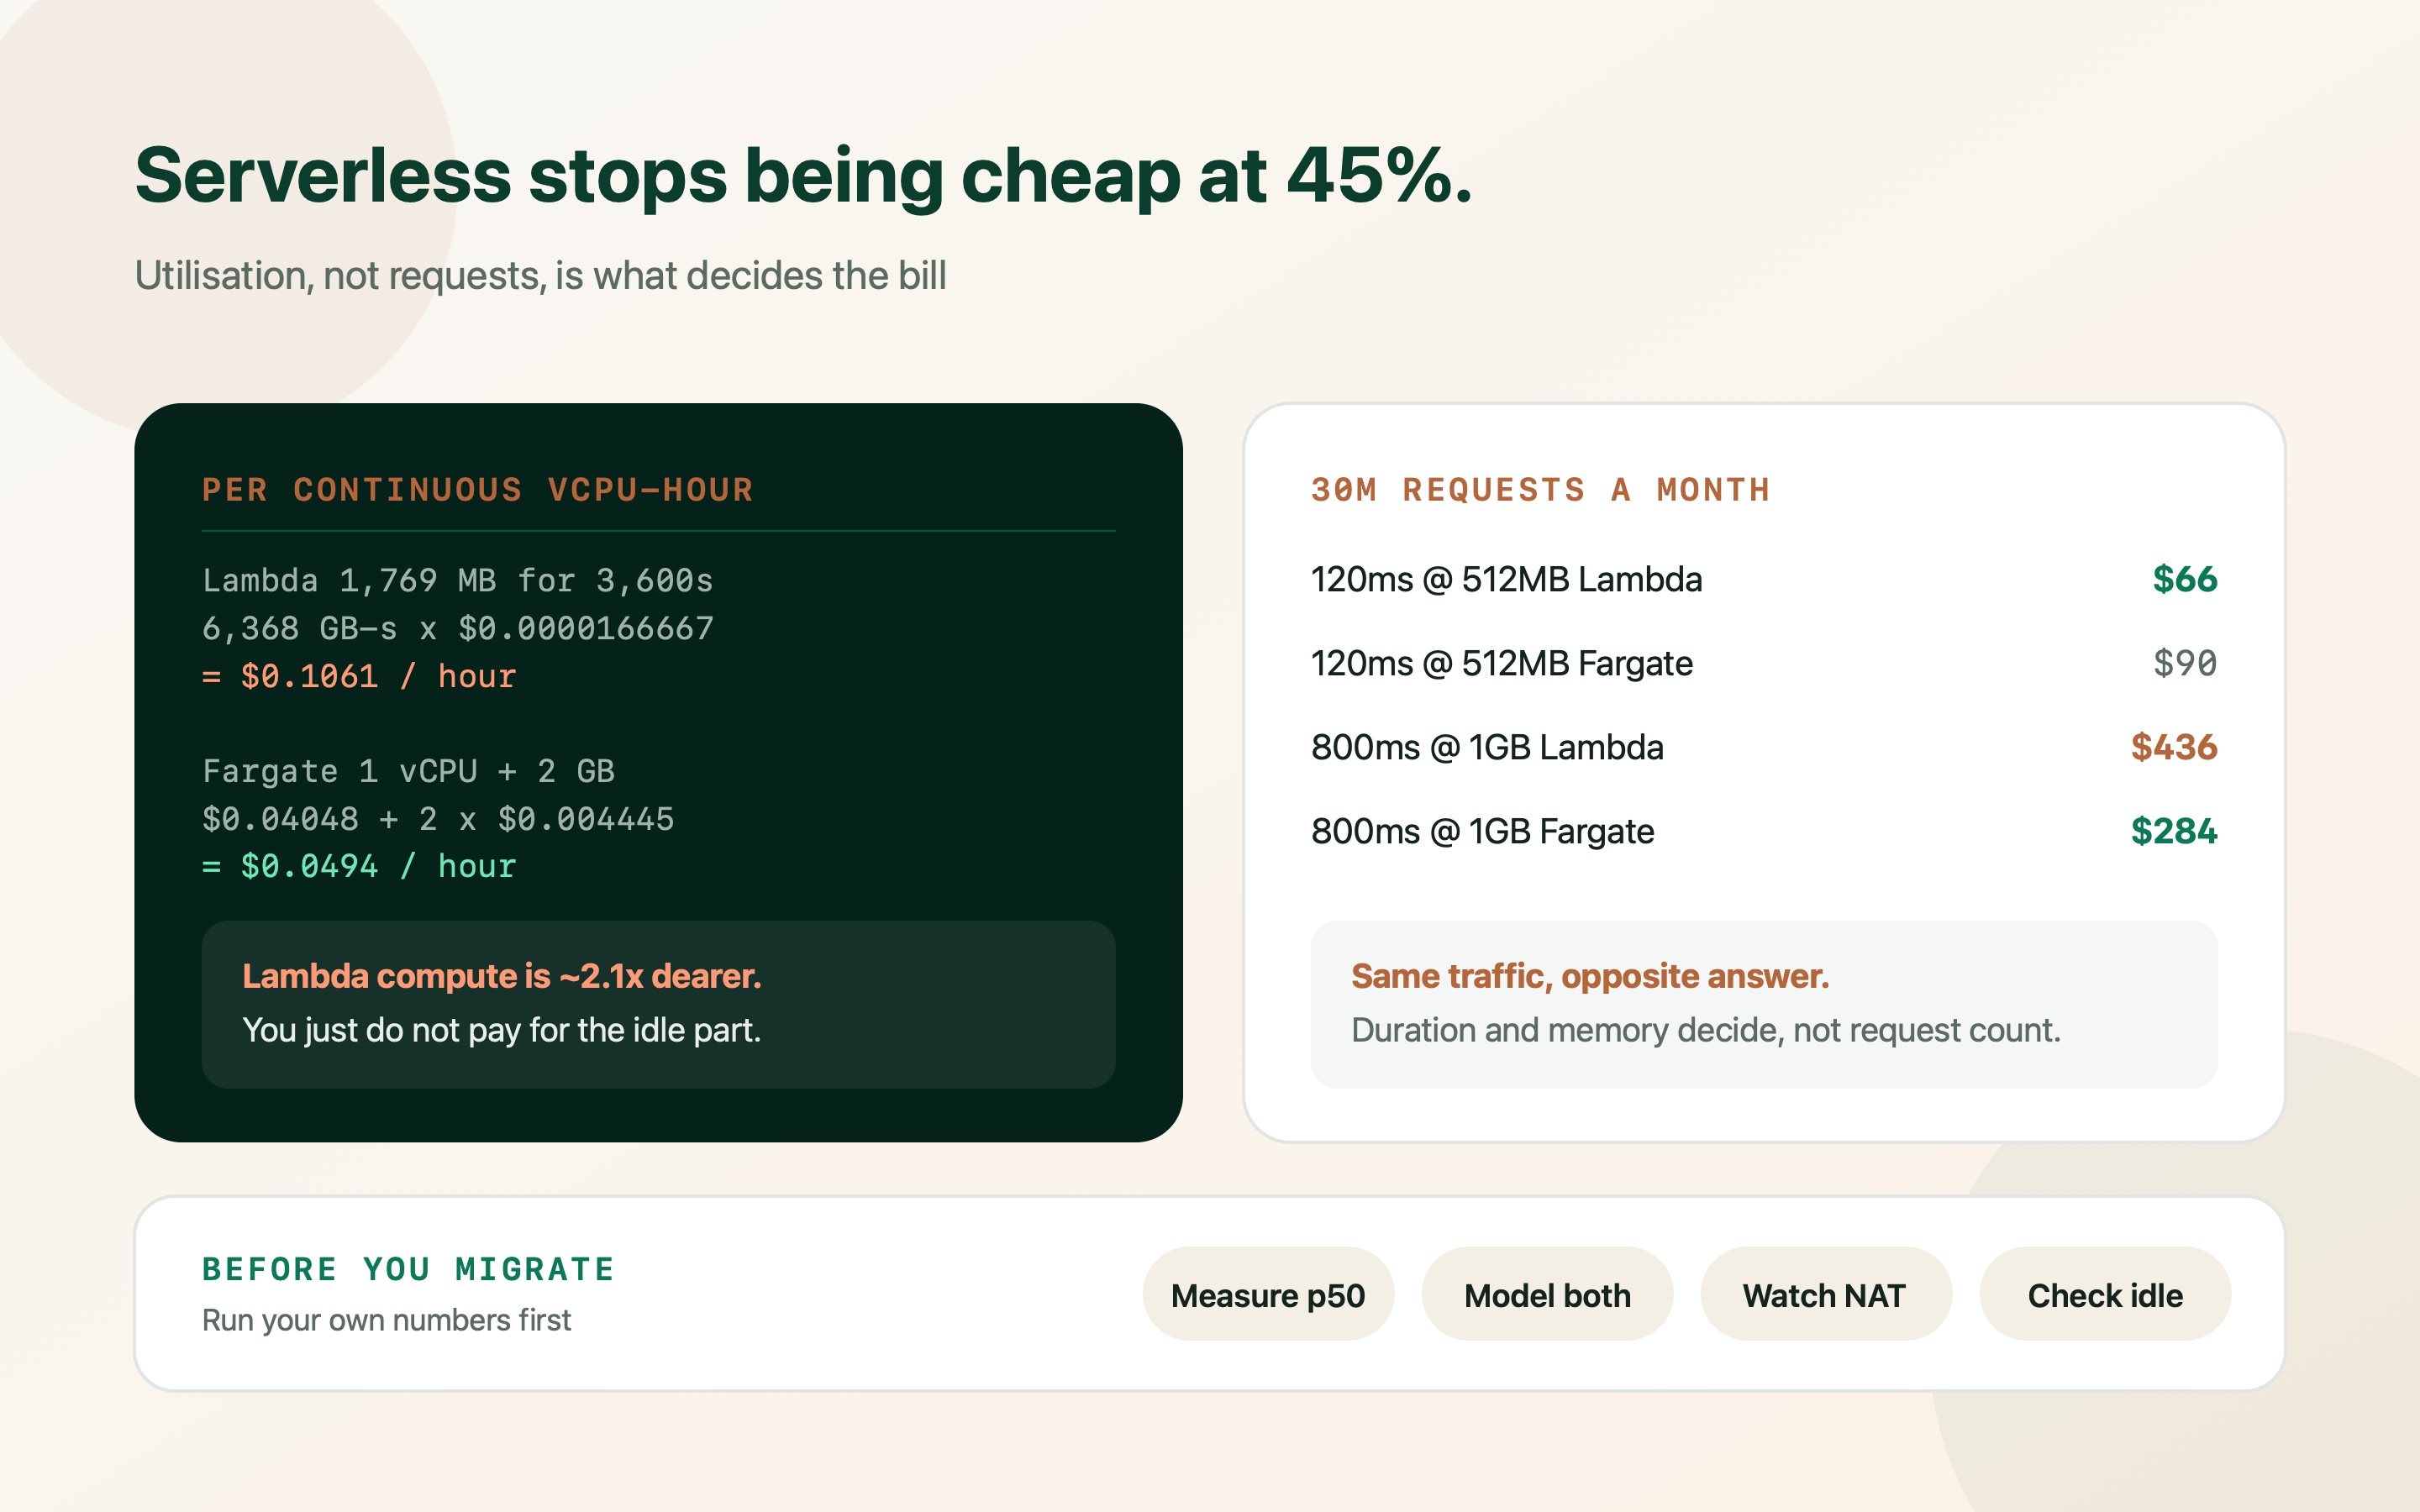
Why Serverless Isn't Always Cheaper: A Real Cost Comparison for Growing SaaS
Same 30M requests a month, opposite answers. Here's the arithmetic behind Lambda versus Fargate, the break-even utilisation, the charges the calculators leave out, and how to model your own workload before migrating anything.
Read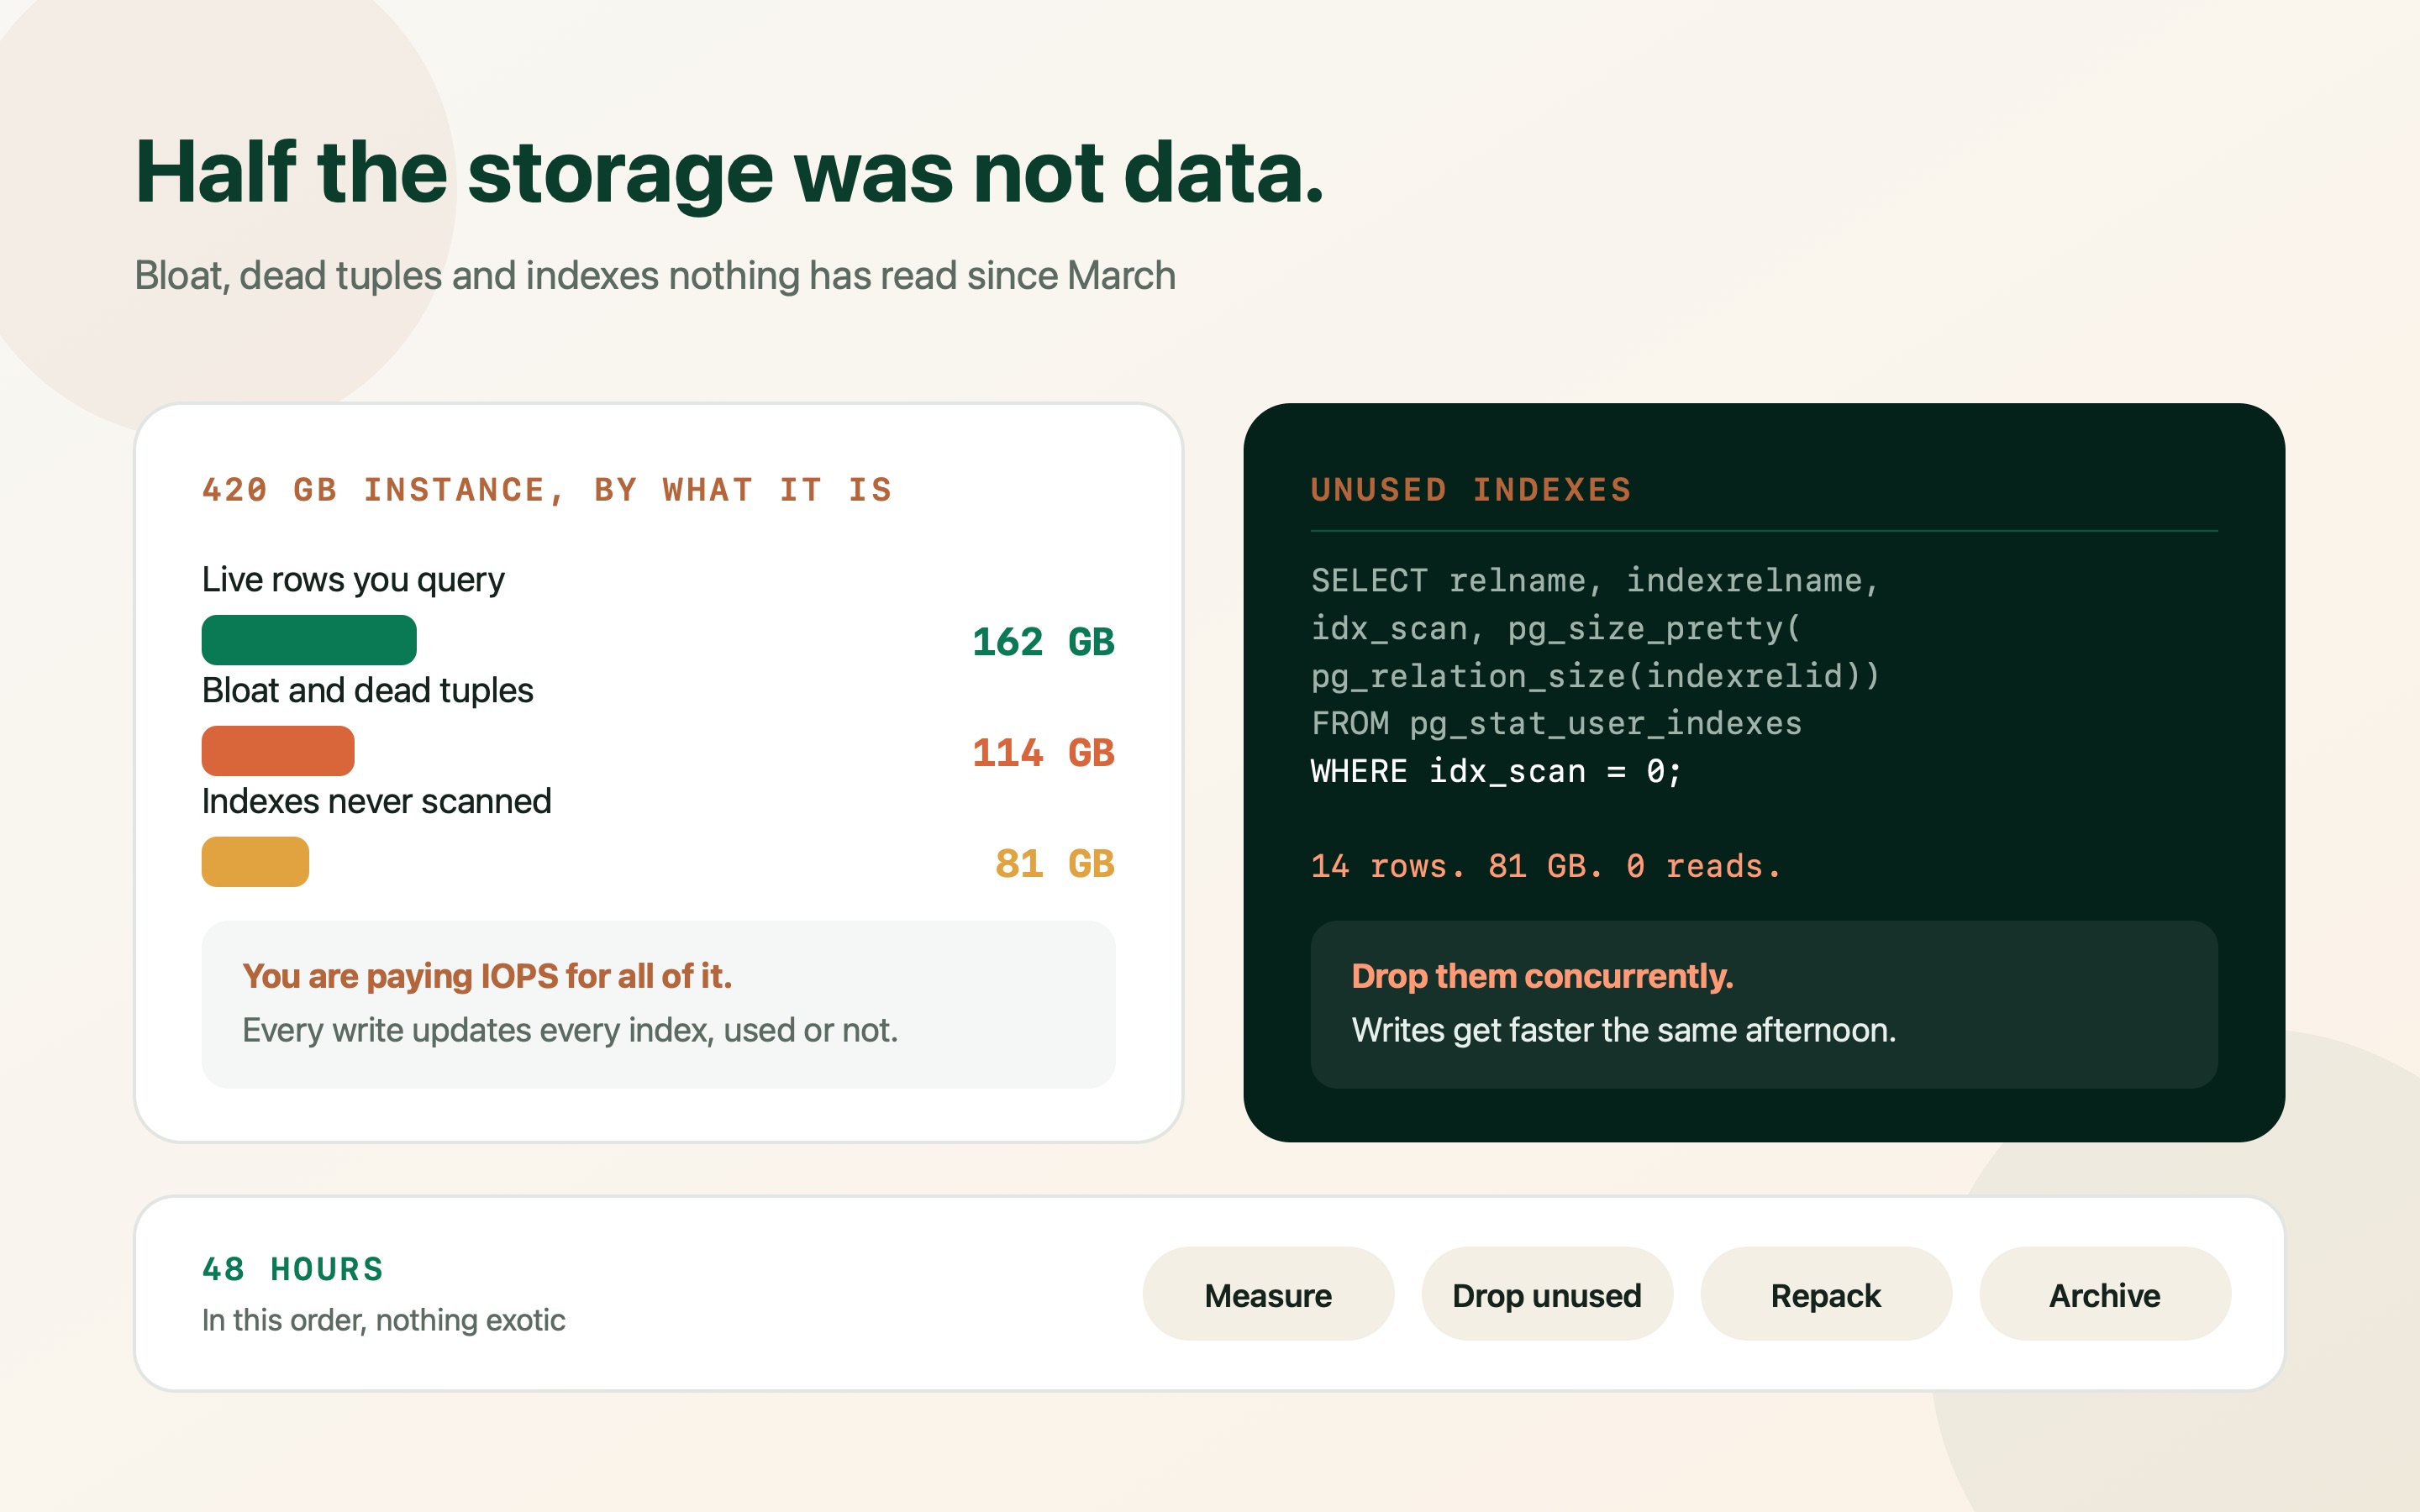
How to Halve Your PostgreSQL Storage and IOPS Costs in 48 Hours
420GB of database, 162GB of it actually queried. Here's the order that reclaims the rest: find the size, drop unread indexes, repack the bloat, archive cold rows — then resize the disk, not before.
Read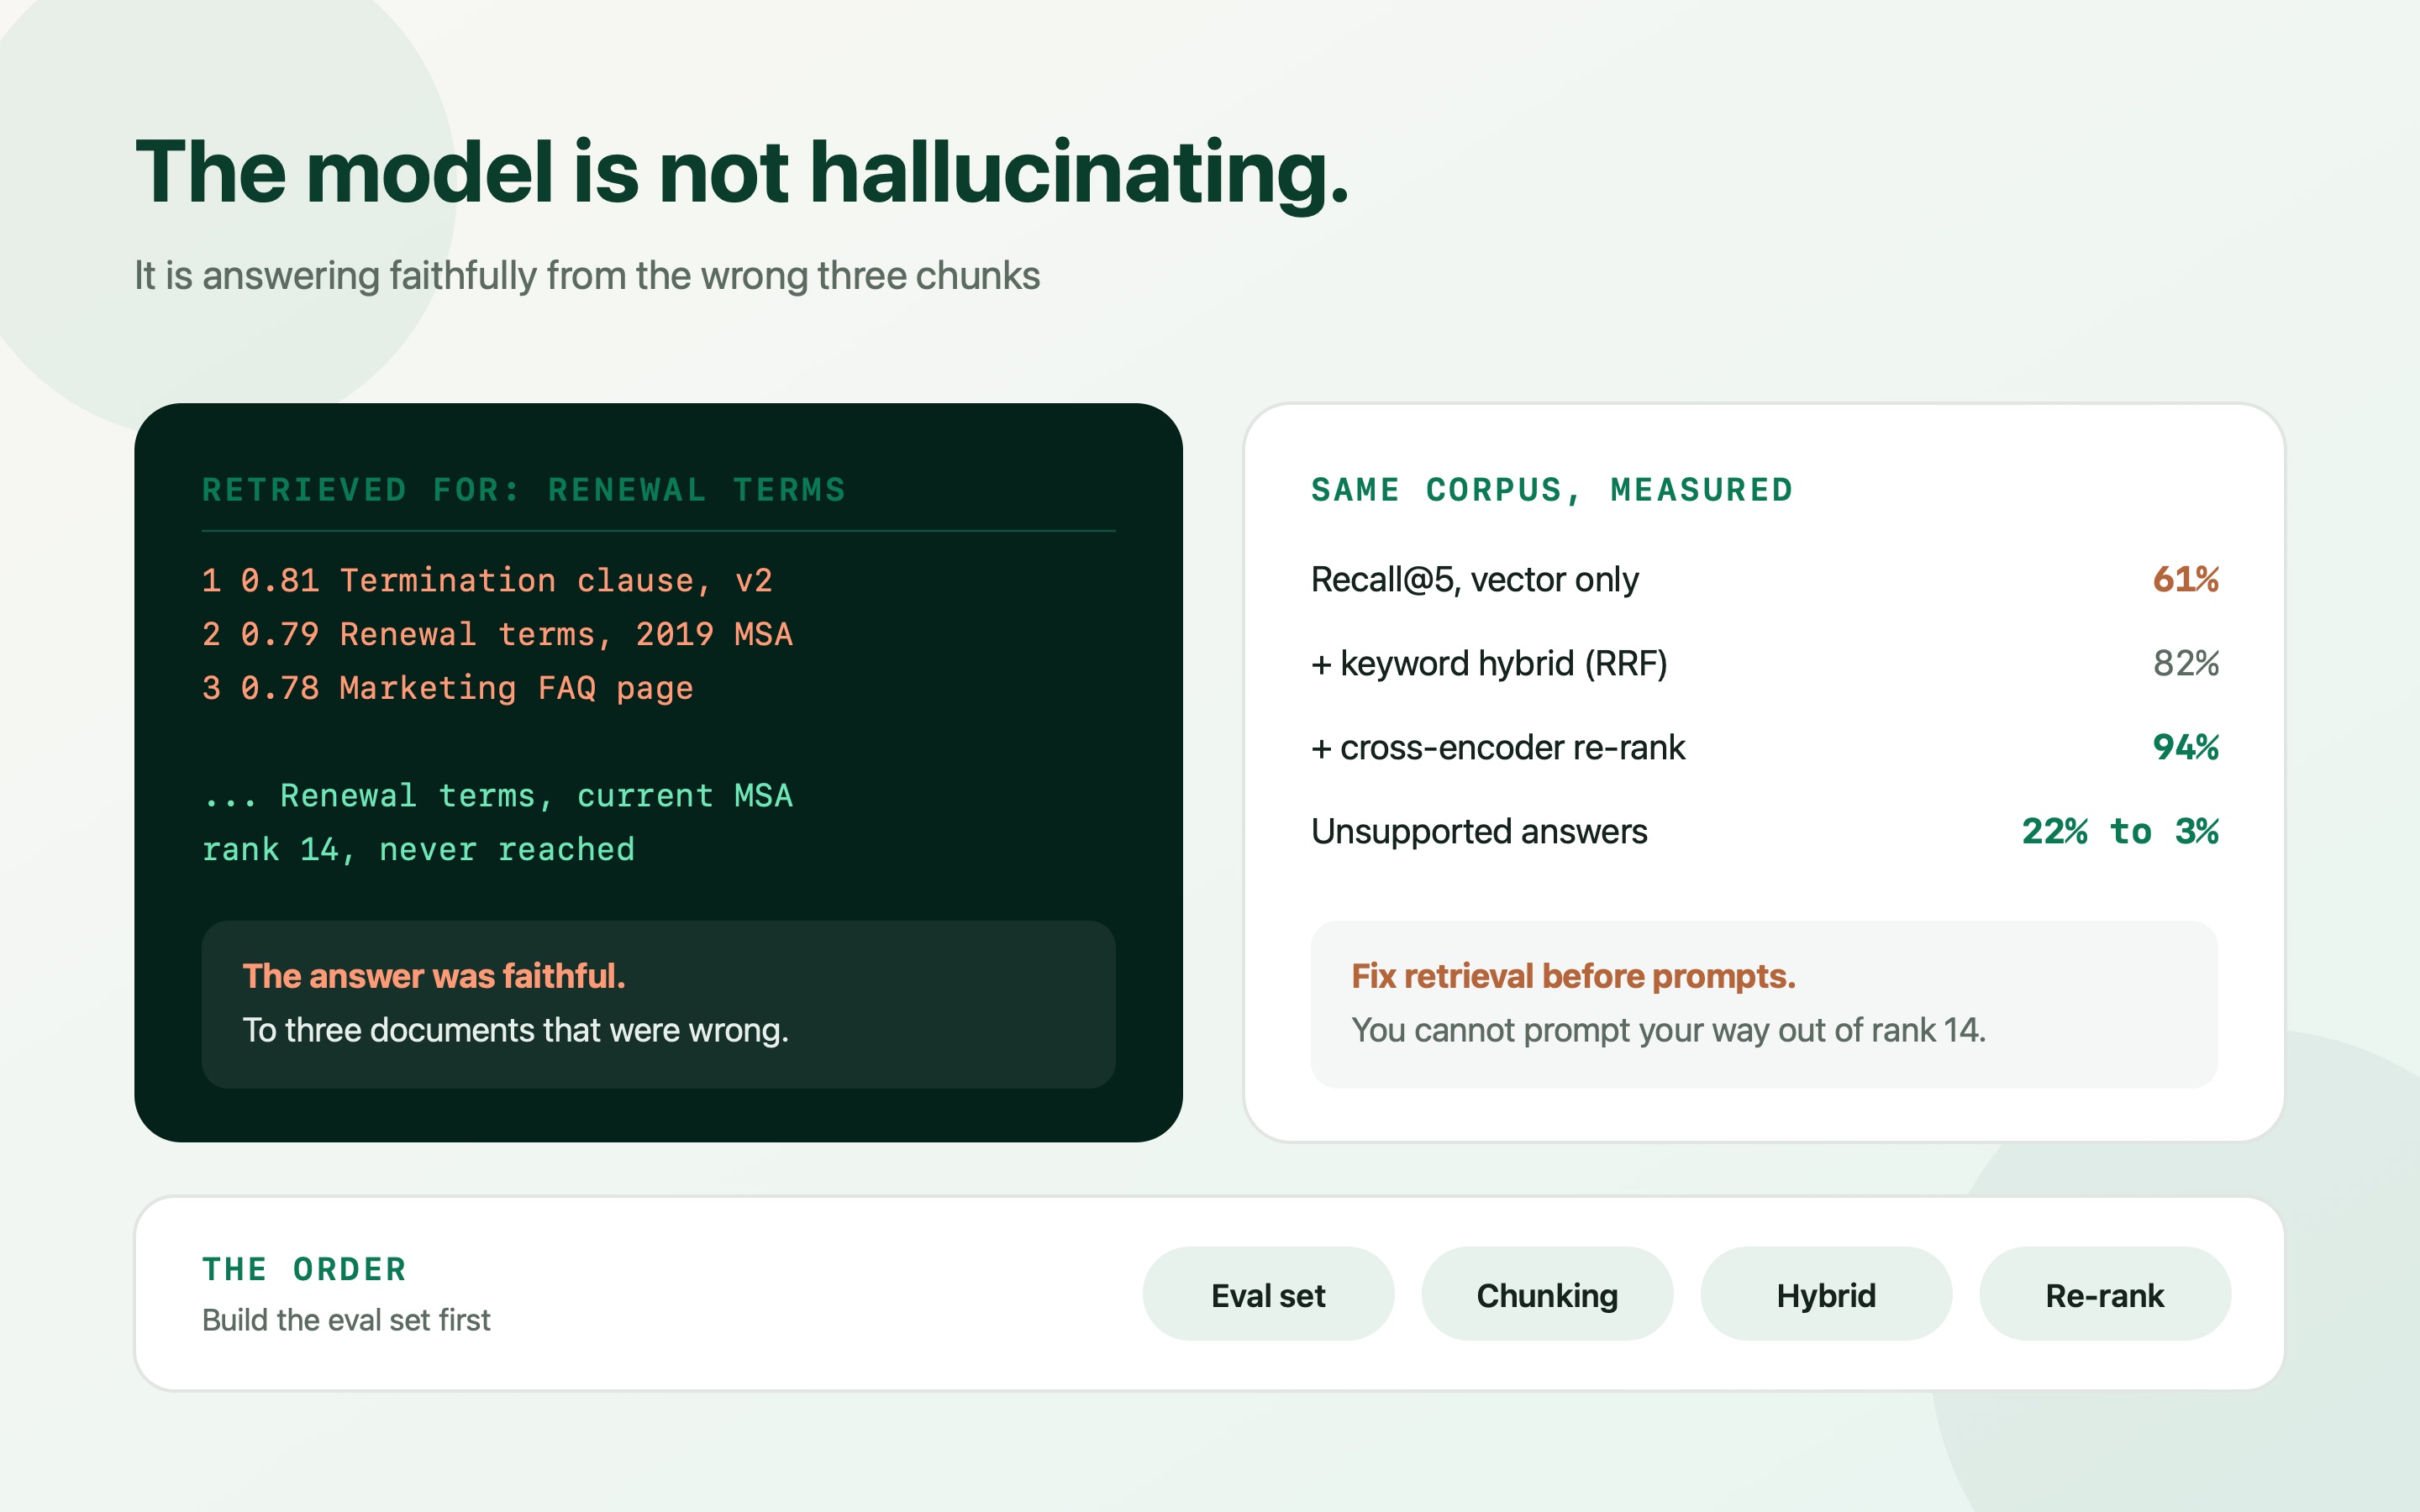
Why Your RAG Pipeline Hallucinates on Production Data (And How to Fix It)
Your RAG demo was perfect and production is wrong a fifth of the time. Here's why: chunking that cuts clauses in half, vector search that misses exact terms, no re-ranking, and no way for the system to say 'I don't know'.
Read
A Founder Almost Paid $20,000 for a Rewrite. We Fixed It in 10 Days for $3,500.
Before you throw away working software, get a neutral architecture audit. Unindexed queries, sync workloads, and zero caching looked like a $20k rewrite — and weren't.
Read
AI Integration: How to Add LLMs to Legacy Laravel Monoliths (Without Tech Debt)
When clients ask to add AI to 8-year-old Laravel monoliths, the fear is tech debt. Here's how to integrate LLMs with async queues, an AI gateway, and strict JSON contracts — without a rewrite.
Read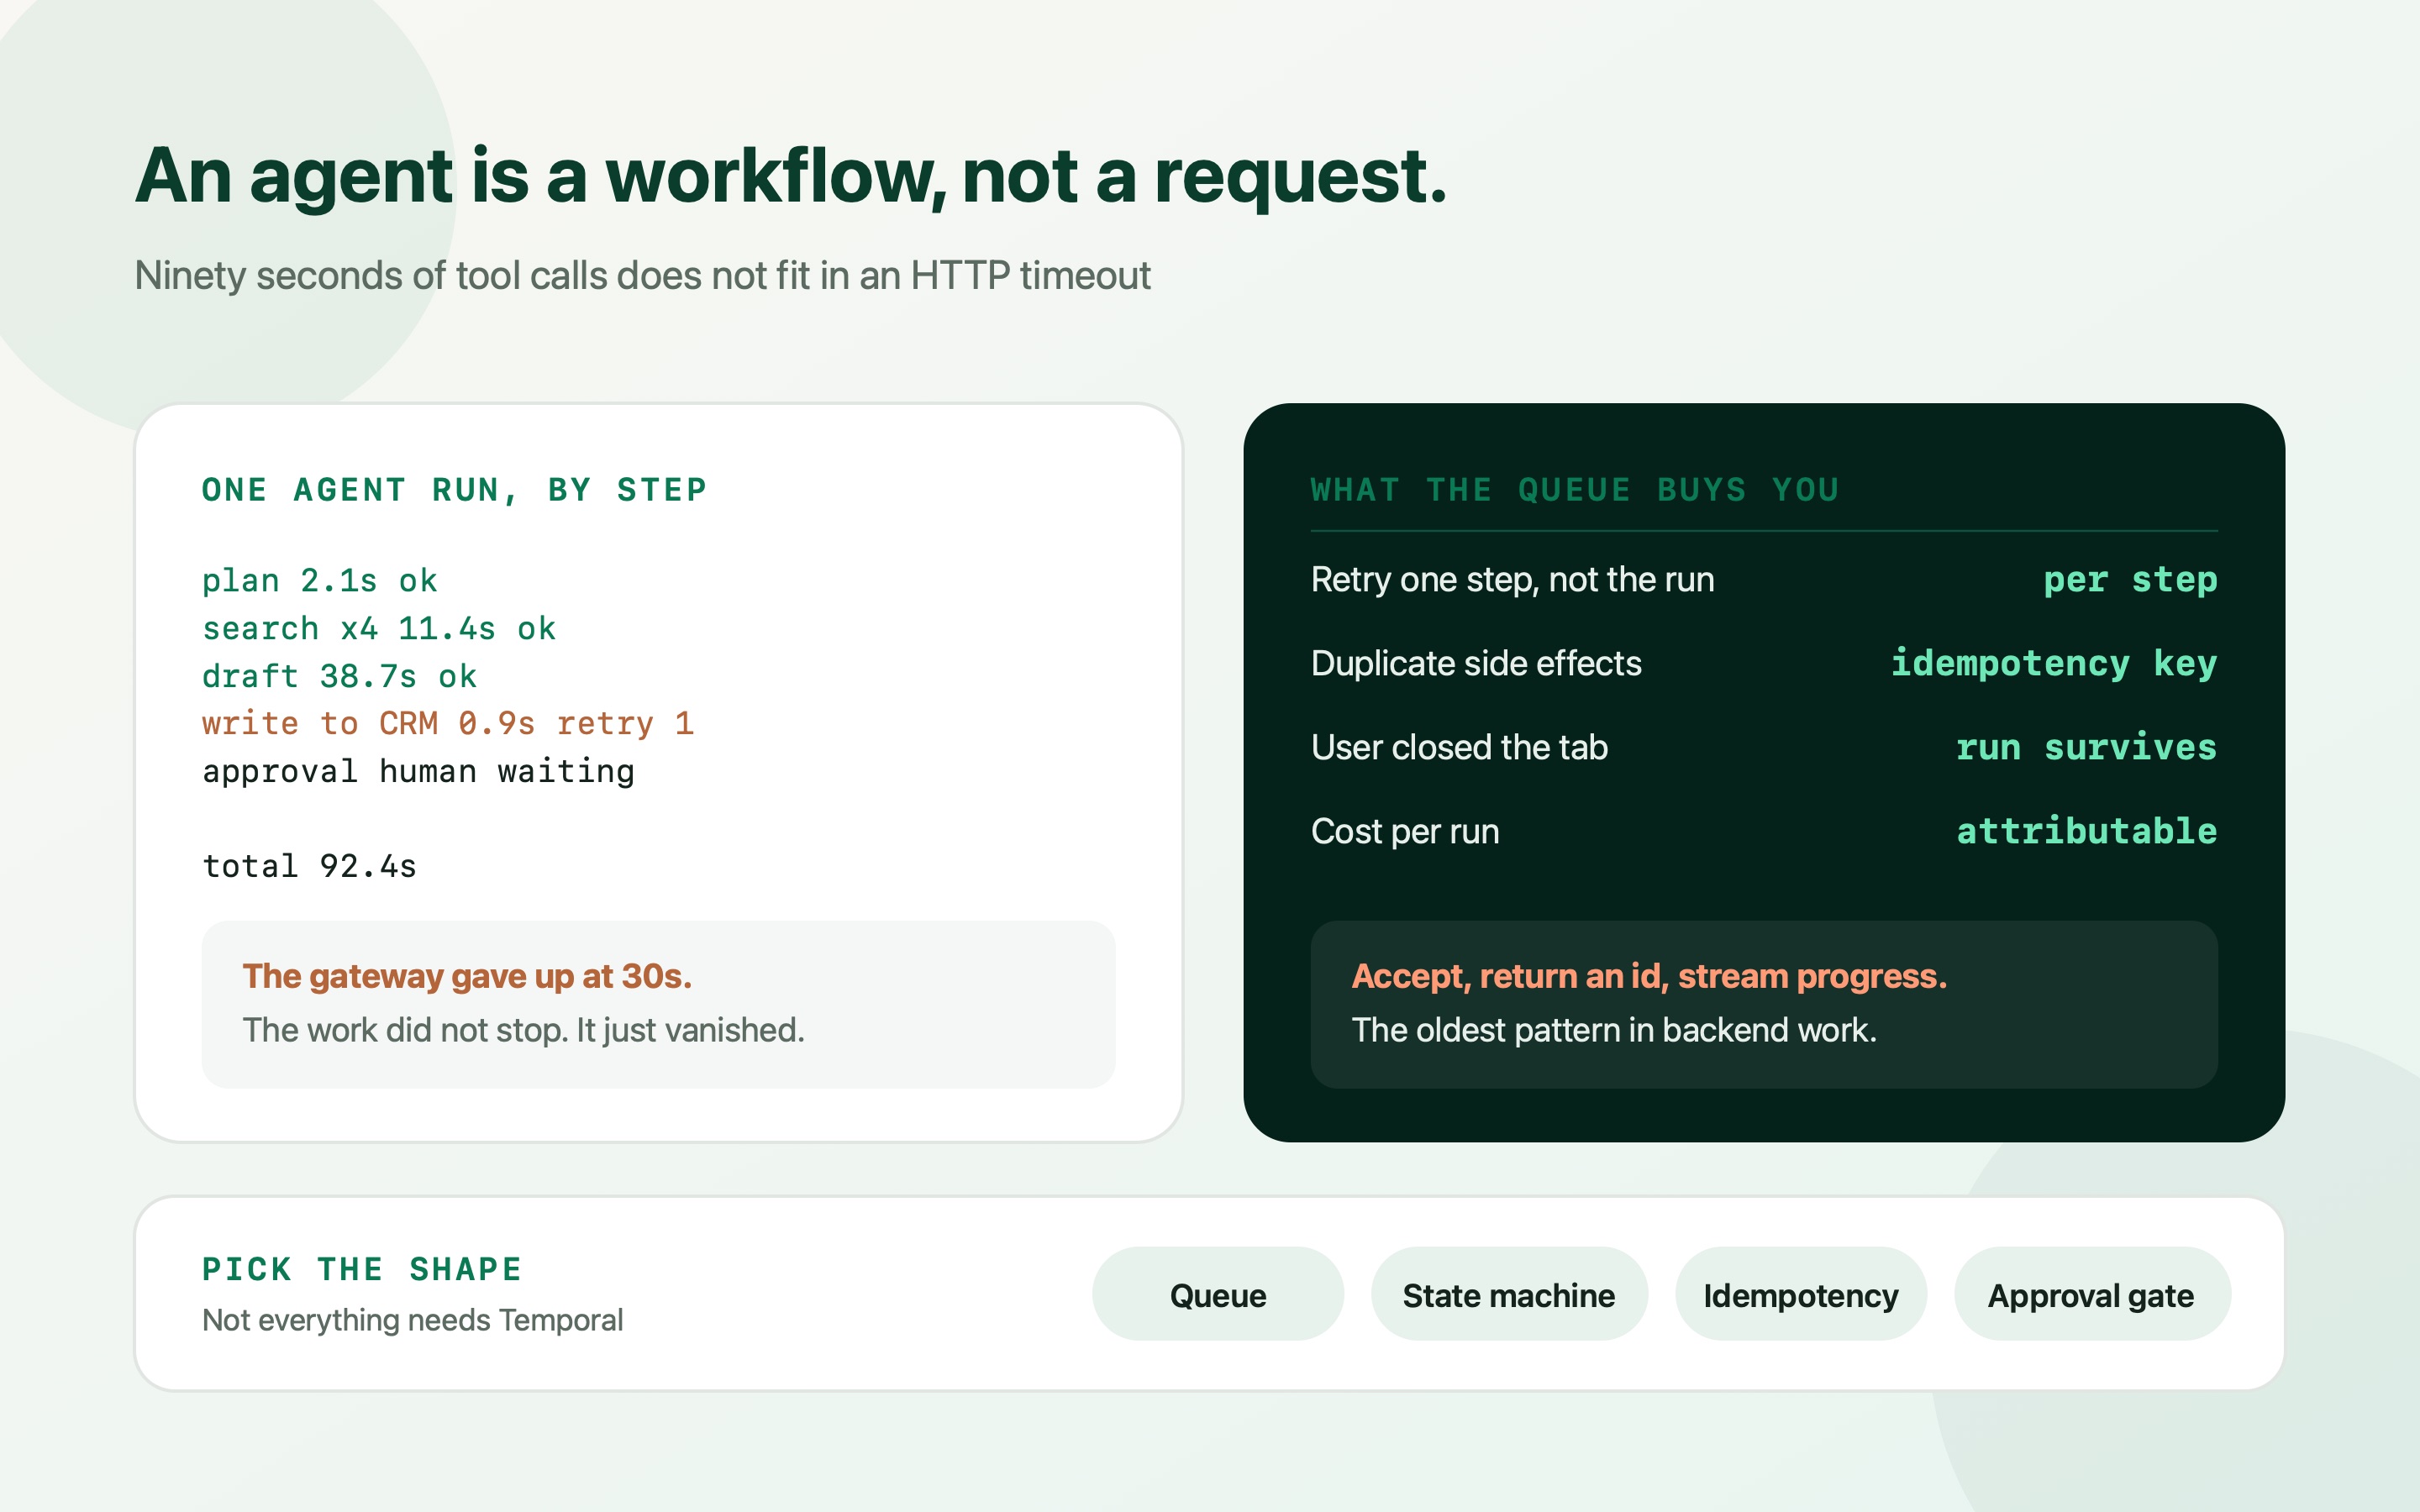
Building AI Features That Act, Not Just Chat: Reliable Async AI Workers
Your agent works in the notebook and times out in production at thirty seconds. Here's the architecture that survives: accept and return an id, run steps on a queue, make every write idempotent, and put a human gate where it matters.
Read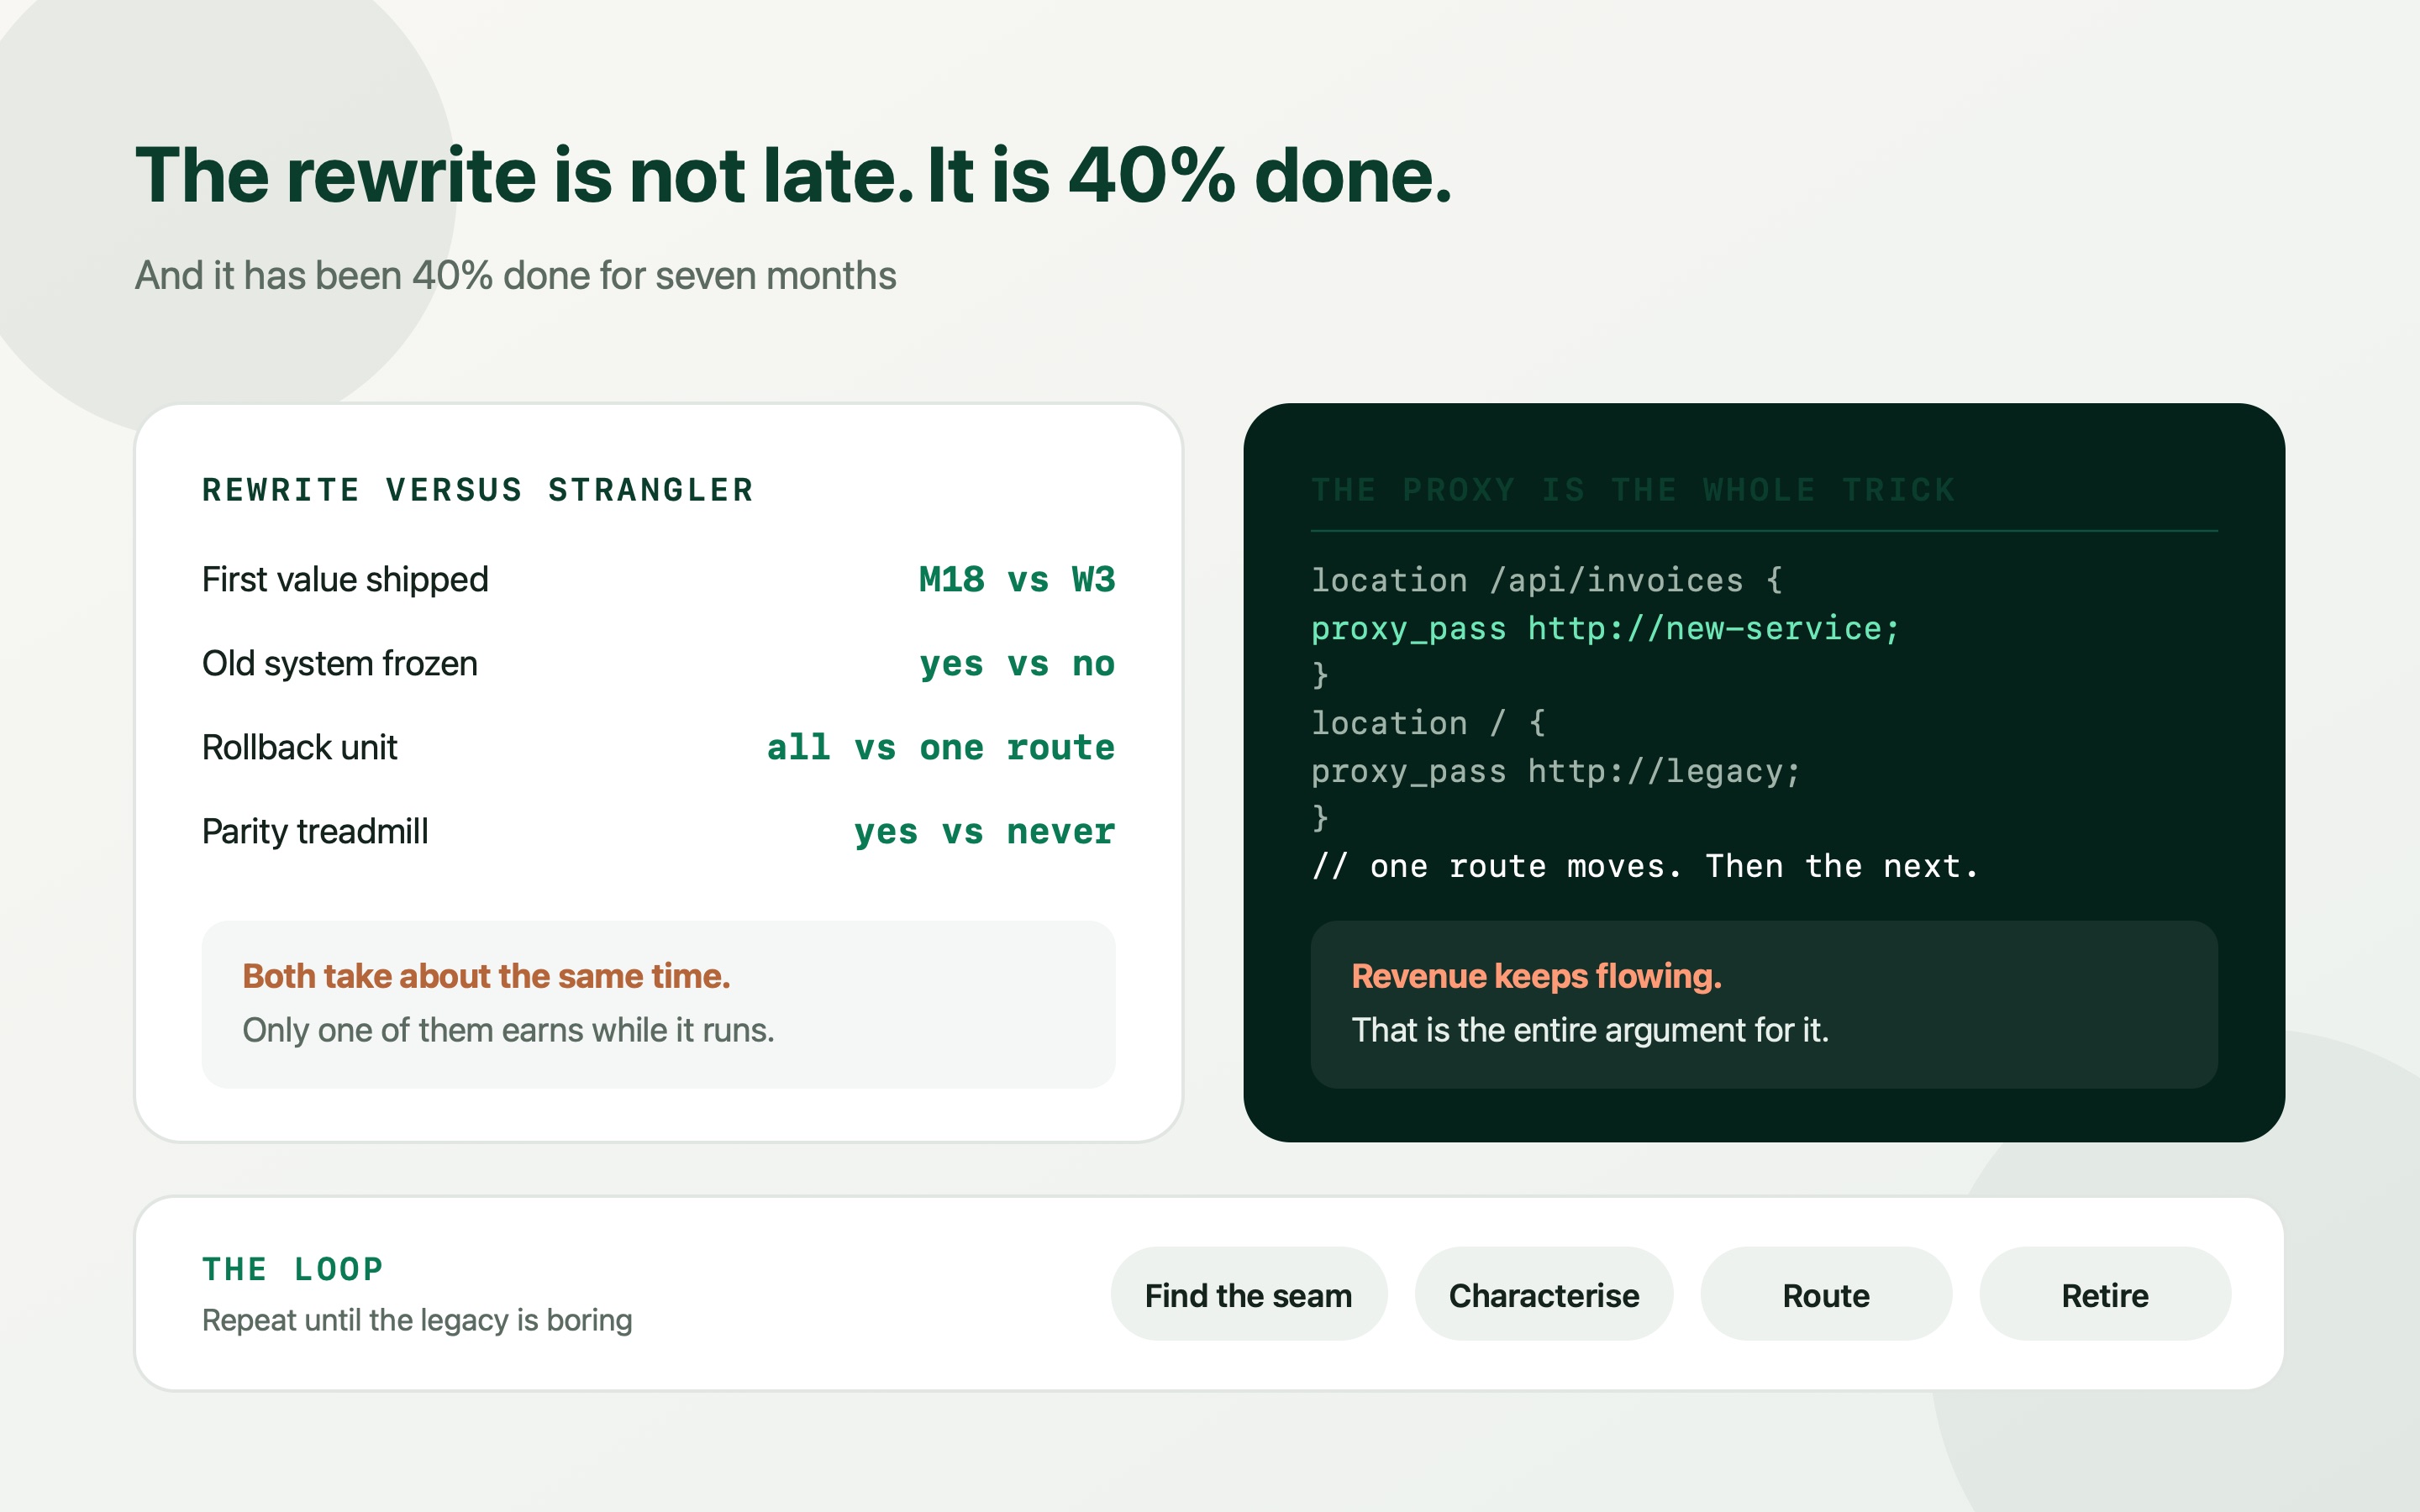
The 'Do Not Rewrite' Playbook: Modernising Legacy Systems Incrementally
Your team wants six months to rebuild it. Here's what actually happens in month seven, and the alternative: find the seam, characterise it, route it, retire it — with production live and revenue flowing the whole way.
Read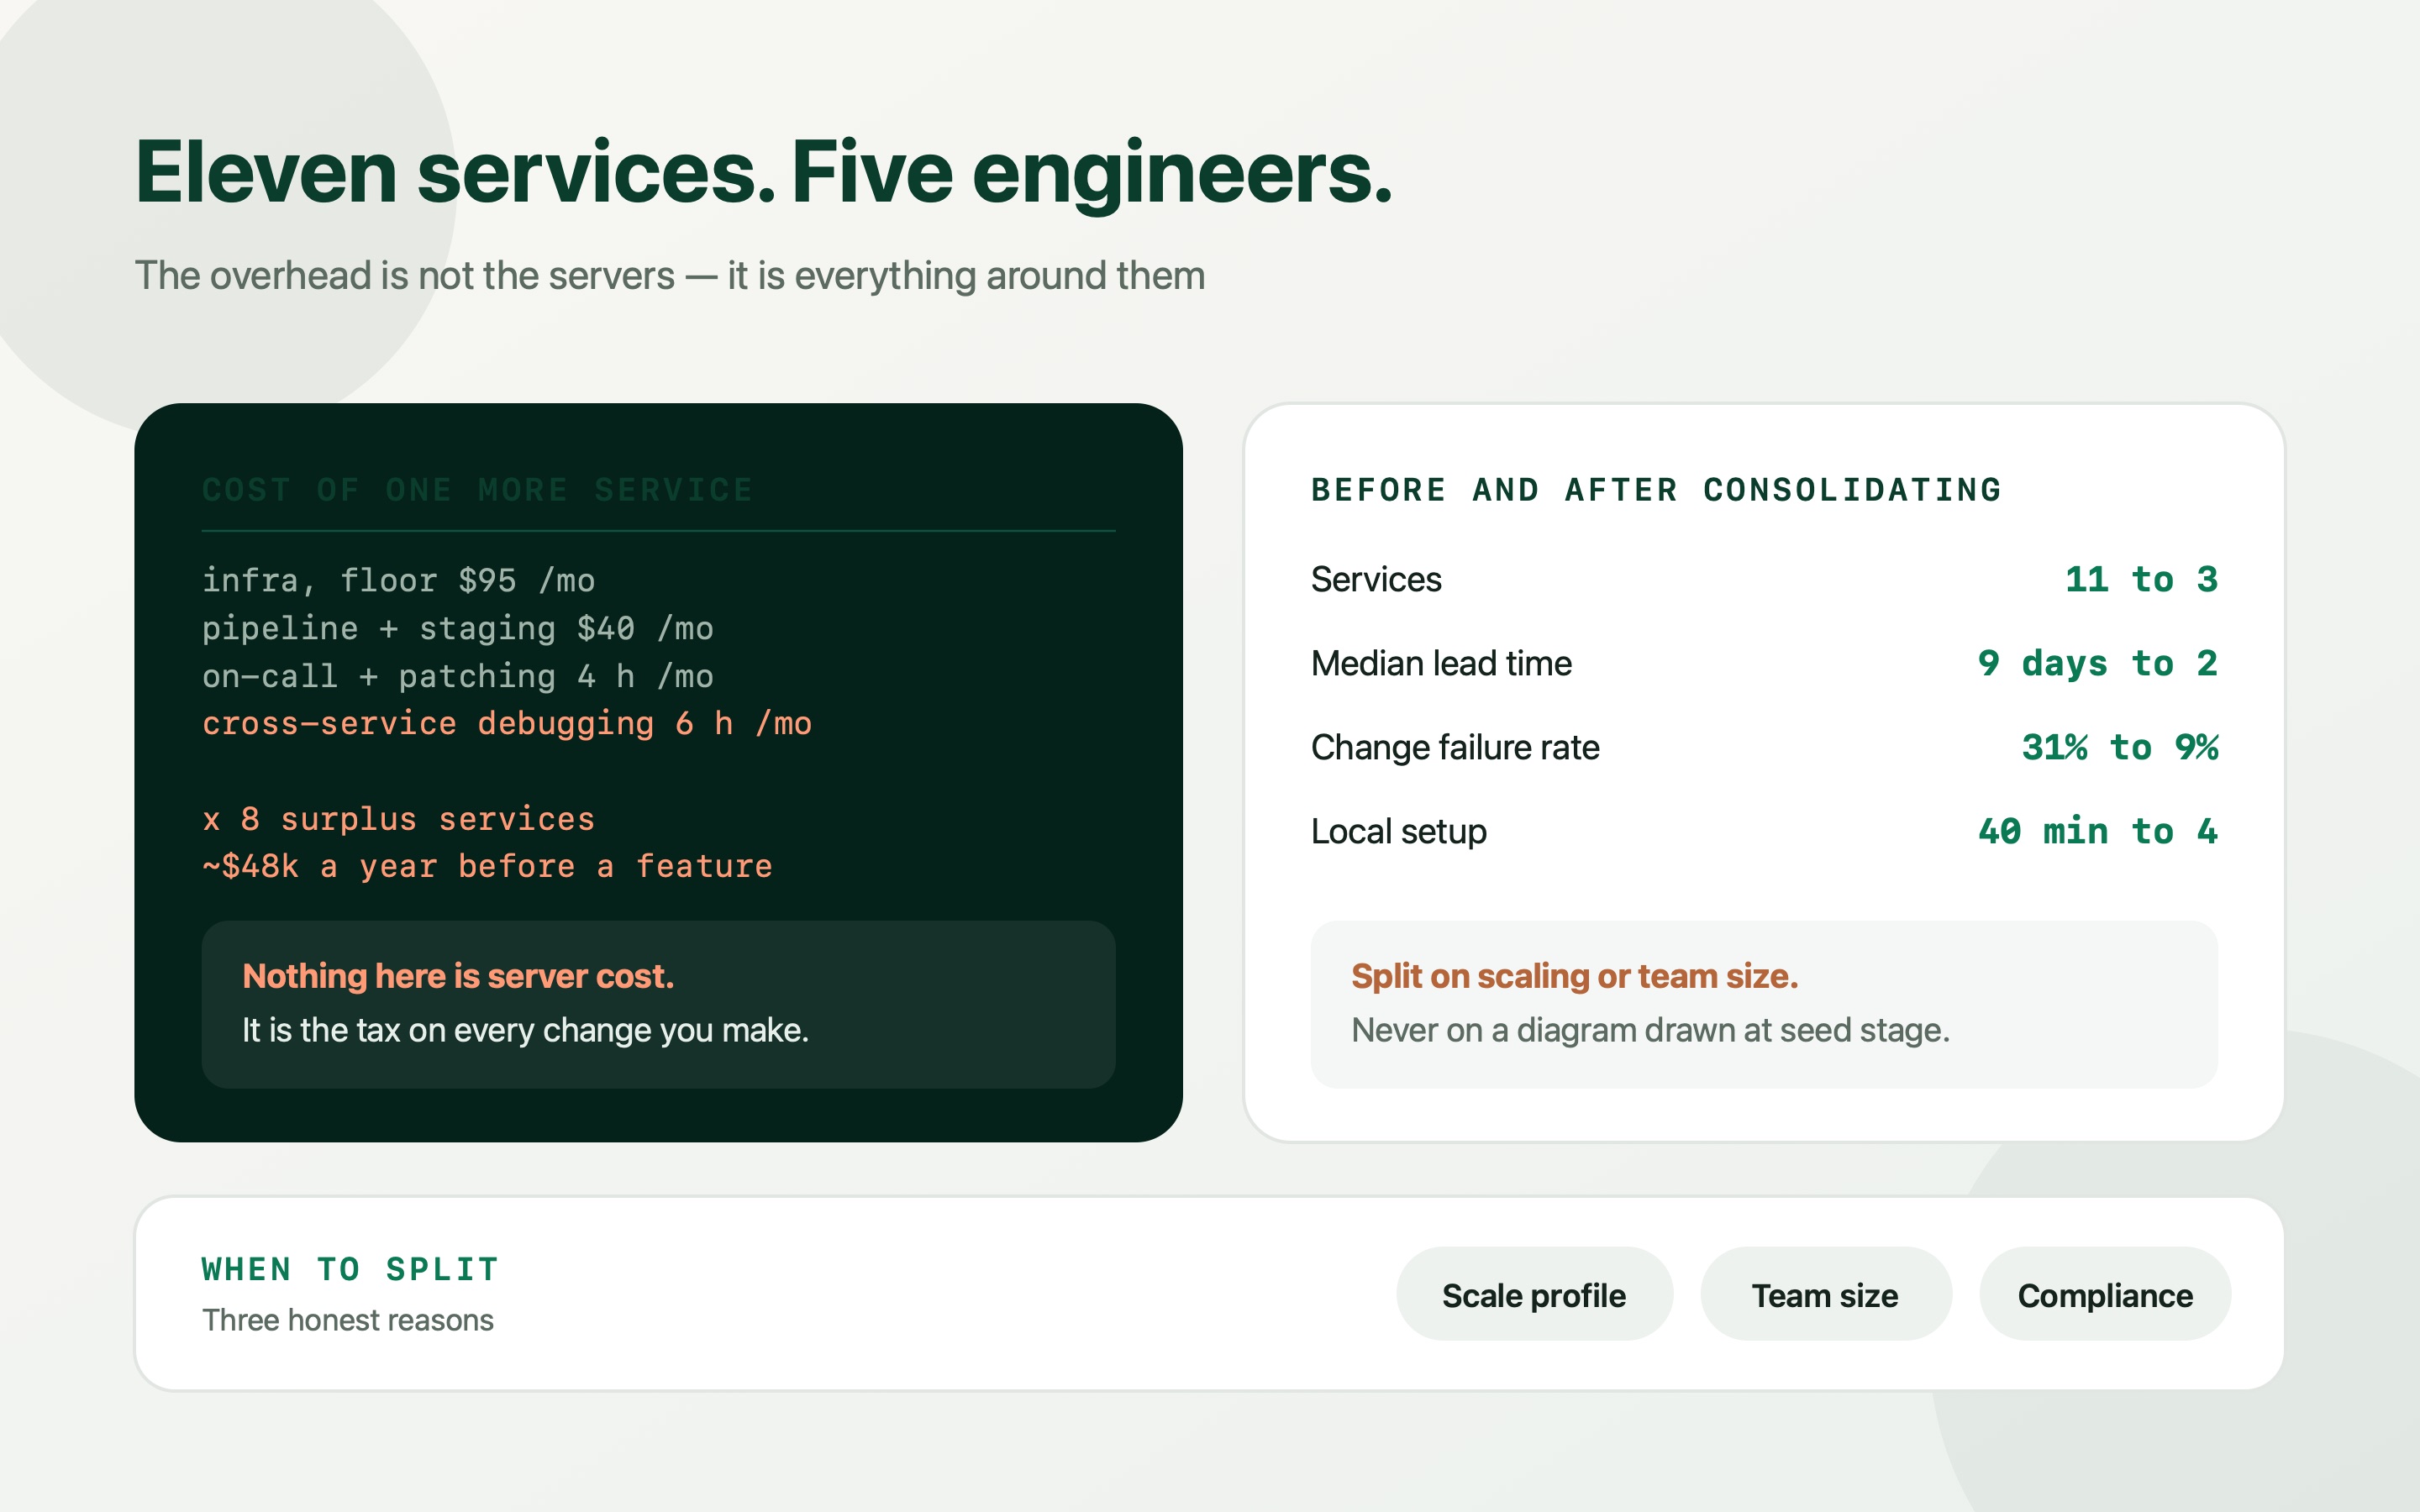
The $50,000 Microservices Mistake: When to Monolith Your SaaS Back First
A five-person team maintaining eleven services pays roughly $50,000 a year in overhead before writing a feature — and most of it is not server cost. Here's the arithmetic, the symptoms of a premature split, and how to merge back safely.
Read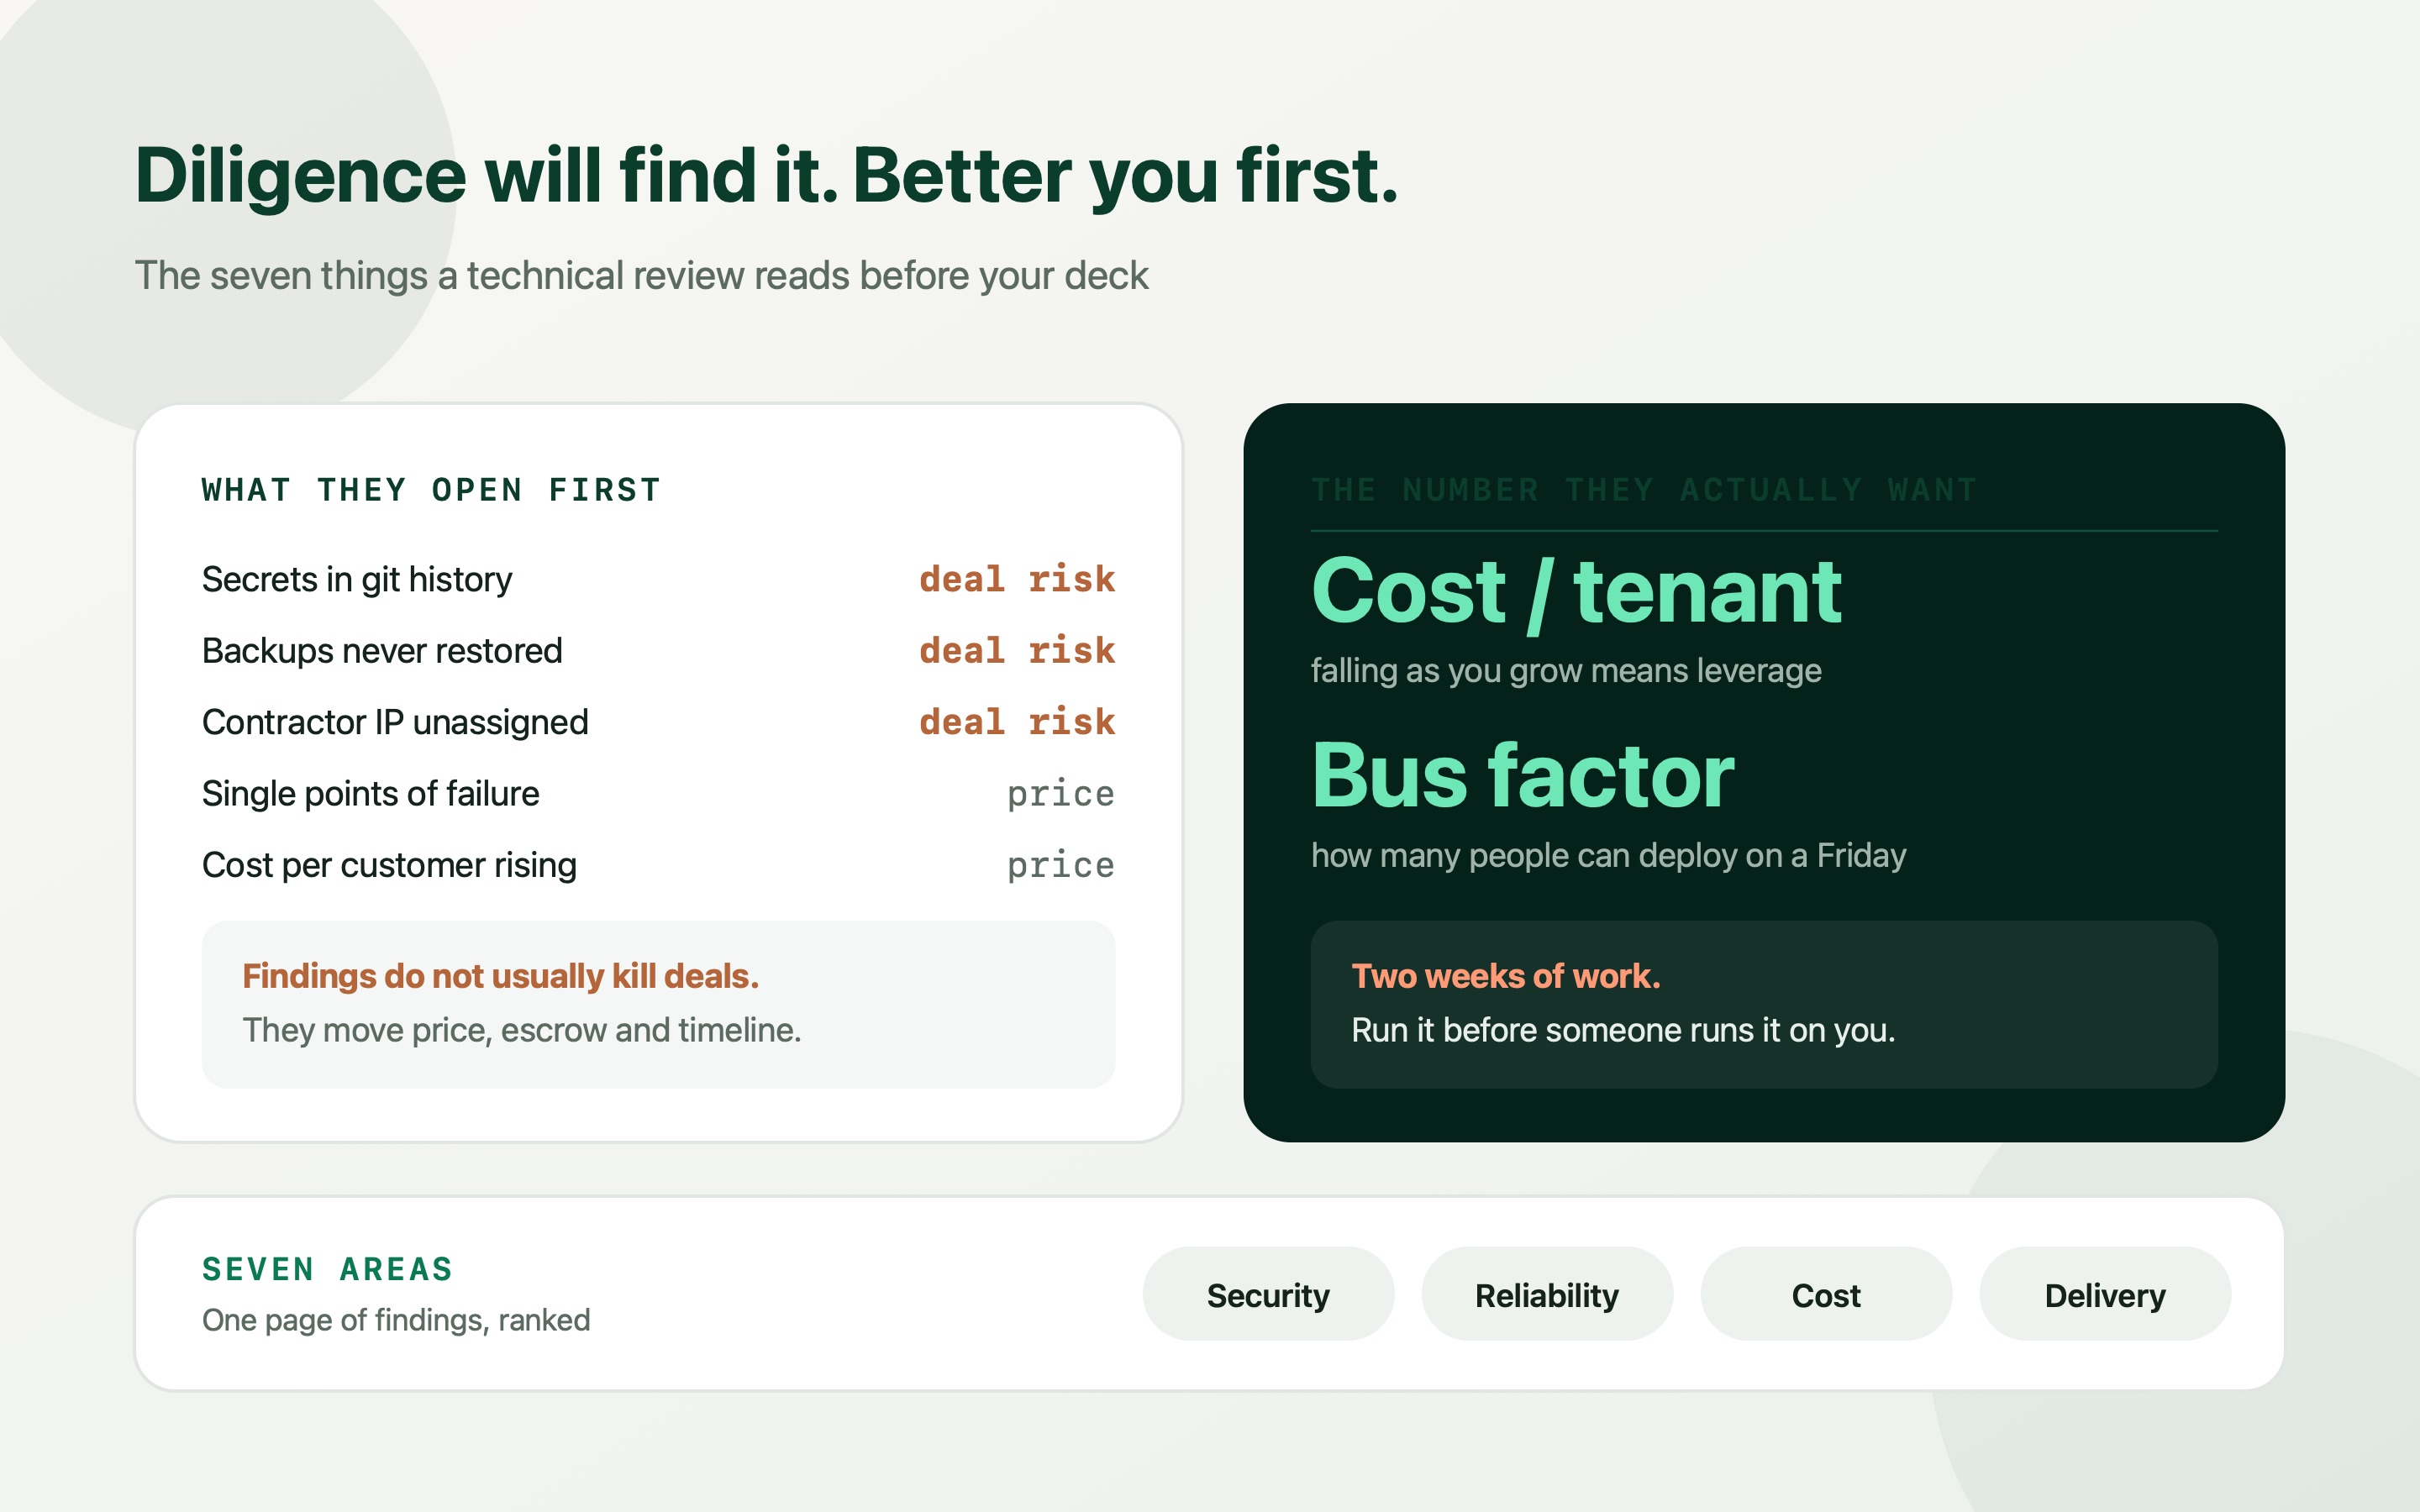
How to Run an In-House Architecture Audit Before Your Next Funding Round
A checklist for founders running their own technical due diligence before investors or an acquirer run theirs. Seven areas, what each finding does to price or timeline, and the one-page output to hand over.
ReadNeed a developer for your project?